For local AI, the 5060 Ti vs 5070 Ti decision comes down to memory bandwidth. Both RTX cards carry 16 GB of GDDR7 and load exactly the same models, but the 5070 Ti moves 896 GB/s to the 5060 Ti’s 448 GB/s, and in our Ollama runs it generated tokens 1.66x to 1.85x faster. Is that worth about $470 more? At Amazon’s own $1,300 price, yes: you pay less per token per second than for the 5060 Ti 16GB at $830. The catch is that Amazon only takes orders for a later ship date, and 5070 Ti cards that ship today start near $1,460, where the cheaper card wins on 8B and 14B models.
We rented both GPUs at the same time on vast.ai in June 2026 and ran identical benchmarks, so every 5070Ti vs 5060Ti figure below comes from those two boxes. Prices and stock were re-checked on Amazon on October 31, 2026, ahead of Black Friday.
Which to buy: 5060 Ti or 5070 Ti
Buy the RTX 5070 Ti if your case and PSU can take a 300W card and you can either wait for Amazon’s $1,300 card to ship or pay about $160 more for one in stock. Buy the RTX 5060 Ti 16GB if you need a 180W card, a shorter card, a card this week, or the lower total spend. Both run the same set of models, because both have 16 GB:

| If you… | Get the |
|---|---|
| Run 14B+ models daily, care about tool-use latency, want headroom for FP16 7B models | RTX 5070 Ti 16GB (~$1,300) |
| Mostly run 7-8B Q4 models, are budget-constrained, or want 16GB future-proofing without the 5070 Ti price | RTX 5060 Ti 16GB (~$830) |
The 5060 Ti 16GB is not a consolation prize. At 75 tok/s on Llama 8B it writes far faster than anyone reads, which is all a chat or code-completion window needs. The 5070 Ti is faster in every scenario we ran, but not every local AI workload needs 125 tok/s, and you can’t buy the extra speed this week at Amazon’s price.
How we tested
We rented two separate vast.ai instances running simultaneously so neither card’s results depend on the other’s load. The RTX 5070 Ti ran on instance ID 42905175 (PCIe 13.2 GB/s) and the RTX 5060 Ti 16GB on instance ID 42905169 (PCIe 13.8 GB/s). Both instances ran Ubuntu 22.04 with CUDA 12.8, and Ollama was started in Docker using ollama/ollama:latest.
Three models were benchmarked on each card:
- Llama 3.1 8B (Q4_K_M): the most common local AI workhorse, 4.9 GB loaded
- Qwen2.5 14B (Q4_K_M): representative of the mid-tier, 9.0 GB loaded
- Qwen2.5 7B (FP16): full precision, maximally bandwidth-bound, 15 GB loaded
Each run prompted the model to explain CPU cache hierarchy in 300 tokens. One warmup pass was discarded; the reported figure is from the timed pass. Tokens per second were computed from eval_count / eval_duration in the Ollama JSON response, not from wall-clock timing.
Compare the 5060 Ti and 5070 Ti specs
| Spec | RTX 5070 Ti | RTX 5060 Ti 16GB |
|---|---|---|
| Die | Blackwell GB203 | Blackwell GB206 |
| CUDA cores | 8,960 | 4,608 |
| VRAM | 16 GB GDDR7 | 16 GB GDDR7 |
| Memory bandwidth | 896 GB/s | 448 GB/s |
| TDP | 300 W | 180 W |
| PCIe interface | PCIe 5.0 x16 | PCIe 5.0 x8 |
| Launch MSRP | $749 | $429 |
| Amazon price (Oct 31, 2026) | ~$1,300 (later ship date); ~$1,460 in stock | ~$830 |
The PCIe x8 lane on the 5060 Ti is a real tradeoff for gaming (5-10% loss in CPU-GPU transfer-heavy workloads) but irrelevant for LLM inference where the bottleneck is the GDDR7 bus, not the PCIe slot. Once the model is loaded into VRAM, the PCIe link is essentially idle.
5070 Ti vs 5060 Ti benchmark results
Both cards ran the same three models at the same time on separate vast.ai instances, as described above:
| Model | RTX 5070 Ti | RTX 5060 Ti 16GB | Speedup |
|---|---|---|---|
| Llama 3.1 8B (Q4_K_M) | 125.0 tok/s | 75.1 tok/s | 1.66x |
| Qwen2.5 14B (Q4_K_M) | 73.2 tok/s | 42.3 tok/s | 1.73x |
| Qwen2.5 7B (FP16) | 51.8 tok/s | 28.0 tok/s | 1.85x |
The ratios track bandwidth because single-user token generation is memory-bound. At batch size 1 the GPU streams every weight from GDDR7 for each token and does very little math per byte, so you get close to twice the tokens from twice the bandwidth. Extra CUDA cores don’t help much here, so the 5070 Ti’s near-double core count is not why it wins.
The FP16 model shows the widest gap (1.85x) because it is the most memory-bandwidth-bound workload of the three. A 7B FP16 model loads about 15 GB of weights on every forward pass with zero weight reuse. The quantized 14B model is slightly less punishing because 4-bit packing reduces the bytes-per-weight ratio, so it lands at 1.73x. The 8B Q4 lands at 1.66x for the same reason. All three are within shouting distance of the 2x bandwidth ratio, confirming the bottleneck is exactly where theory predicted.
RTX 5070 Ti 16GB
The 5070 Ti is the right card if your primary use case is running 14B models interactively, using LLM APIs locally where latency matters, or running FP16 7B models without quantization artifacts. At 73 tok/s on Qwen 14B, responses feel immediate rather than typewriter-paced. At 125 tok/s on Llama 8B, even a heavily agentic workflow that chains many short completions stays snappy.
Pick the 5070 Ti when your workload looks like one of these, because each one multiplies the per-token speed gap:
- tool-use or multi-agent loops run locally
- rotating between several 7-13B models through the day
- FP16 models instead of quantized ones
- a homelab box serving several clients at once
Skip it if: your daily driver is a single 7-8B Q4 model for writing or code completion, or your PSU is 450W or smaller and can’t carry a 300W GPU under load. It’s also the wrong card for a low-profile system. For an SFF build, check your case’s GPU clearance against the card’s listed length first: the dual-slot PNY Slim linked here is marked SFF-Ready on Amazon, but most 5070 Ti boards are long triple-fan cards.
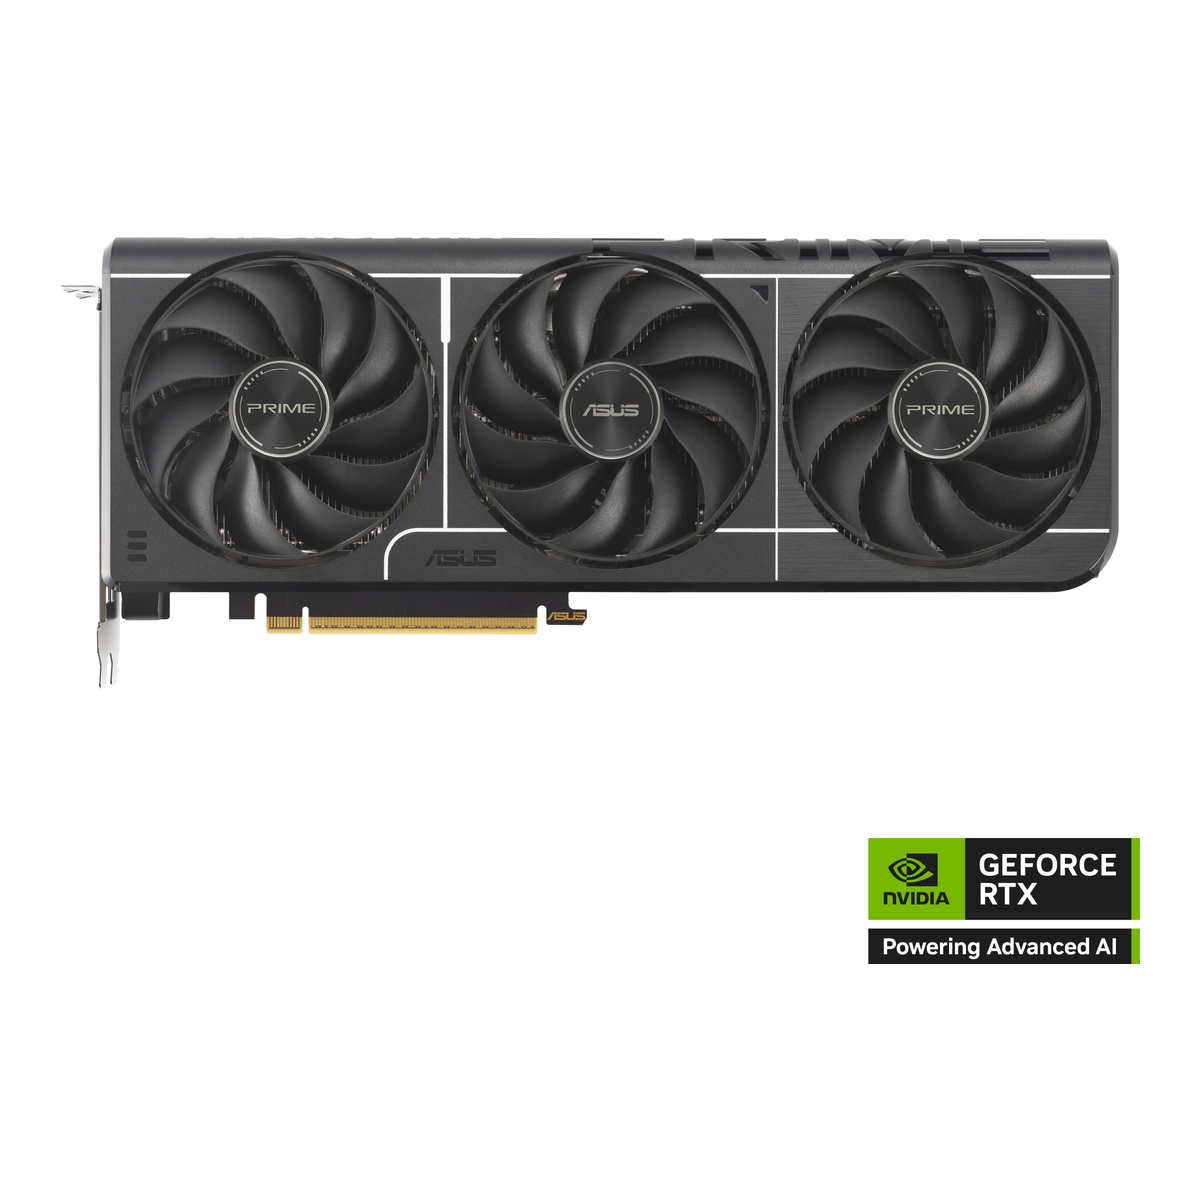
The 300W TDP needs a large cooler. Most add-in board variants ship with triple-fan coolers and are 2.7 to 3.0 slots thick, so plan case clearance accordingly. The PNY Slim OC linked here is the exception: PNY builds it as a dual-slot, two-fan card with the same 8,960 CUDA cores and a 2,572 MHz boost clock, which makes it the easier 5070 Ti to fit in a mid-tower.
Stock is the problem going into Black Friday. On October 31 Amazon was selling the PNY Slim itself at $1,299.99 but only taking orders for a later ship date, and every 5070 Ti that ships now came from a third-party seller. The cheapest new ones were the PNY Epic-X OC at about $1,458 and the MSI Ventus 3X OC at about $1,467, and the ASUS Prime OC that once held this slot was down to a single unit at about $1,735. If you need the card now, budget for the in-stock price and read the value table below at that number, not the $1,300 one.
RTX 5060 Ti 16GB
The 5060 Ti 16GB is a more interesting card than its specs suggest. At 75 tok/s on Llama 8B it is genuinely fast for conversational AI, code completion, and single-turn generation. The 16 GB frame buffer means it loads the same models as the 5070 Ti, so you are not trading model capability for price, only generation speed. How both cards rank against the wider field, including used options, is covered in the GPU buyer guide for LLMs.
An 8GB variant of the 5060 Ti exists at a lower price point but cannot load 14B models and runs 7B FP16 with significant offloading. At launch the gap was only $50 ($379 versus $429). On October 31, 2026 the ASUS Dual 8GB listed at about $548 against about $830 for the 16GB, so the premium is now closer to $280. Pay it anyway: 8 GB caps you at small models for the life of the card. The memory configuration gap matters far more than the bandwidth gap between the two 5060 Ti variants because both have the same 448 GB/s bandwidth regardless of VRAM amount.
Buyers like these get more from the 5060 Ti 16GB, since none of them gains much from the extra speed:
- mostly 7-8B Q4 models, with 16 GB as room for larger ones later
- SFF builds that need the 180W TDP
- budgets where the roughly $470 premium would buy RAM or faster NVMe
- anyone who needs a card shipped this week
Skip it if: you regularly run 14B models and 42 tok/s feels too slow for your workflow (a real complaint for agentic use where latency compounds across tool calls), or you want to experiment with FP16 7B models at reasonable speed. At 28 tok/s on Qwen 7B FP16 the 5060 Ti is technically running the model, but the experience is noticeably slower than the quantized alternative.
For a smaller case, or simply the lowest price, the PNY RTX 5060 Ti 16GB OC Dual-Fan (about $800) is the same GPU on a two-slot board that the Amazon listing marks SFF-Ready. It was the cheapest 5060 Ti 16GB that Amazon sold and shipped itself on October 31, about $30 under the ASUS Prime.
Cost per token per second at 2026 prices
Launch pricing made the 5060 Ti 16GB the obvious value pick: $429 against $749. The 2026 memory shortage changed that math, and it’s still moving: the ASUS Prime 5060 Ti 16GB went from $789 on October 18 to $830 on October 31. Dividing the October 31 Amazon prices by our measured throughput gives this, with the 5070 Ti shown at both the order-now price and the cheapest in-stock price:
| Metric | RTX 5070 Ti, Amazon (~$1,300, later ship) | RTX 5070 Ti, in stock (~$1,458) | RTX 5060 Ti 16GB (~$830) |
|---|---|---|---|
| Price per GB of VRAM | ~$81 | ~$91 | ~$52 |
| $ per tok/s, Llama 3.1 8B Q4 | ~$10.40 | ~$11.66 | ~$11.05 |
| $ per tok/s, Qwen2.5 14B Q4 | ~$17.76 | ~$19.92 | ~$19.62 |
| $ per tok/s, Qwen2.5 7B FP16 | ~$25.10 | ~$28.15 | ~$29.64 |
| Markup over launch MSRP | ~74% | ~95% | ~93% |
At Amazon’s own price the 5070 Ti is the cheaper card per unit of speed on all three workloads. Pay the in-stock premium and it loses that edge on Llama 8B and Qwen 14B, keeping it only on FP16, where its bandwidth lead is widest. Per gigabyte the 5060 Ti wins at every price, which is the number that matters if you only care about which models load.
Because the speedup is fixed, there’s a simple rule for any Black Friday listing. The 5070 Ti beats the 5060 Ti on cost per token per second whenever its price is under 1.66x the 5060 Ti’s price for 8B models, 1.73x for 14B and 1.85x for FP16. Against an $830 5060 Ti 16GB that puts the break-even 5070 Ti price at about $1,381, $1,436 and $1,535. Against the $800 PNY it drops to about $1,332, $1,384 and $1,480. A 5070 Ti deal below those numbers is the better buy for the model size you run; above them, the 5060 Ti is.
RTX 5060 Ti 16GB vs RTX 5070 12GB for AI
The non-Ti RTX 5070 sits between these two cards on price and bandwidth, and it is the card people most often weigh against the 5060 Ti 16GB. We did not benchmark it, so there are no tok/s figures for it here. The spec sheet and our measured VRAM footprints are enough to answer the model-fit question:
| Spec | RTX 5060 Ti 16GB | RTX 5070 12GB |
|---|---|---|
| CUDA cores | 4,608 | 6,144 |
| VRAM | 16 GB GDDR7, 128-bit | 12 GB GDDR7, 192-bit |
| Memory bandwidth | 448 GB/s | 672 GB/s |
| TDP | 180 W | 250 W |
| Launch MSRP | $429 | $549 |
| Amazon price (Oct 31, 2026) | ~$830 | ~$910 (later ship date) |
| Qwen2.5 7B FP16 (15 GB measured) | Fits | Does not fit |
| Qwen2.5 14B Q4 (9.0 GB measured) | Fits, room for context | Fits, less room for context |
With 1.5x the bandwidth, the 5070 should generate faster than the 5060 Ti 16GB on any model both can hold. The catch is the 12 GB ceiling. A 14B Q4 model leaves only about 3 GB for KV cache and context, FP16 7B models are out, and every future model you might want lands closer to the limit. For local AI the 5060 Ti 16GB is the safer buy at a lower price. The ASUS Prime RTX 5070 12GB only makes sense if gaming is the main job and LLMs are a side interest.
What actually matters for local AI hardware
Memory bandwidth beats CUDA core count for LLM inference. This benchmark makes that concrete. The 5070 Ti has 8,960 CUDA cores versus 4,608 on the 5060 Ti, but the inference speedup tracks bandwidth (2x), not core count (1.94x). The workload is memory-bound, not compute-bound, which is why “more CUDA cores” advice that works for rendering or scientific compute does not transfer here.
VRAM ceiling determines model access, bandwidth determines speed. Both cards load the same set of models: a 14B model at Q4 or a 7B model at FP16 fits entirely in 16 GB, while a 32B model at Q4 needs about 20 GB and does not. The VRAM sizing guide maps which models fit in 16 GB and at what quantization. The difference is how fast each card generates from those models. If you are choosing between a 5060 Ti 16GB and a 5060 Ti 8GB, the VRAM difference is more important than any bandwidth argument: the 8GB card cannot run 14B models at all without offloading, which collapses throughput by 5-10x.
PCIe x8 is not a local AI concern. The 5060 Ti uses PCIe 5.0 x8 rather than x16. Gamers see real performance loss in CPU-to-GPU transfer scenarios. LLM inference does not work that way: once the model is loaded into GDDR7, the PCIe link is nearly idle and token generation speed depends entirely on the GDDR7 bus. The x8 vs x16 slot is a meaningful spec for GPU rendering workloads and a non-issue for local LLMs.
Power headroom matters at 300W. At 300W the 5070 Ti needs real PSU planning, even though it draws well under a 450W flagship. A 750W PSU is the practical minimum for a system with a modern CPU and the 5070 Ti under full load. The 5060 Ti’s 180W TDP is much easier to accommodate in tighter builds and quieter cooling configurations.
Local AI inference reference
Use this as a quick reference for planning your local AI setup. Numbers from our June 2026 vast.ai benchmark runs:
| Model | VRAM used | 5070 Ti tok/s | 5060 Ti 16GB tok/s | Usable for |
|---|---|---|---|---|
| Llama 3.1 8B (Q4_K_M) | 4.9 GB | 125.0 | 75.1 | Both cards, conversational, code |
| Qwen2.5 14B (Q4_K_M) | 9.0 GB | 73.2 | 42.3 | Both cards; 5060 Ti slower for agentic |
| Qwen2.5 7B (FP16) | 15 GB | 51.8 | 28.0 | Both cards; prefer 5070 Ti for FP16 |
| Qwen2.5 32B (Q4_K_M) | ~20 GB (estimated) | N/A in 16 GB | N/A in 16 GB | Requires 24+ GB VRAM |
We kept the 32B row to set expectations, since neither card runs it without offloading, and offloading collapses throughput well below what the table shows for in-VRAM models. If 32B+ models are on your regular rotation, the decision shifts to 24 GB and 32 GB cards: our RTX 3090 vs RTX 5090 benchmarks cover the used and flagship options, and the RTX PRO 4000 vs PRO 5000 comparison covers the Blackwell workstation cards. If you would rather skip a discrete GPU entirely, unified-memory boxes are compared in the Ryzen AI Max+ 395 mini PC roundup.