Picking an Ollama model starts with how much memory you have, not with a leaderboard. A 16 GB graphics card runs gpt-oss:20b at 95 tokens per second with a 64K context and room to spare, while the 15 GB devstral-small-2, which looks like it should fit the same card, spills into system RAM and drops to 5.5 tokens per second. This Ollama models cheat sheet maps the models list to the memory you actually have, from a 16 GB laptop to a 24 GB card and beyond.
It’s a model-selection guide, so keep the Ollama commands cheat sheet open for syntax. You get a pick for each VRAM tier, the commands that list your models, measured speeds, a capability and license grid, and a one-page PDF. The GPU tables ran on Ollama 0.40.6 in October 2026 on an RTX 4090, an RTX 5060 Ti 16 GB and a 16 GB M4 MacBook Pro, and two late-October additions, d3 and the small Nemotron 3.5 Bolt, on Ollama 0.40.11 on a CPU-only Ubuntu 26.04 VM.
Pick an Ollama model by VRAM
Find your memory in the first column and pull from that row. The numbers in brackets are generation speeds in tok/s that we measured in October on Ollama 0.40.6, on an RTX 5060 Ti for the 16 GB row, an RTX 4090 for the 24 GB row and a 16 GB M4 MacBook Pro for the Mac row. The rest of the article explains each pick.
| You have | Best general chat | Best coding | Best vision |
|---|---|---|---|
| 4 GB VRAM (or CPU only with 8 GB RAM) | llama3.2:3b, qwen3.5:2b | qwen2.5-coder:1.5b | qwen3.5:2b (vision built in, 2.7 GB) |
| 8 GB VRAM (RTX 3060 Ti, RTX 4060) | qwen3.5:9b, ornith-1.5:9b, bonsai-2 (3.2 GB), llama3.1:8b | qwen2.5-coder:7b | qwen3.5:9b |
| 12 GB VRAM (RTX 3060 12GB, RTX 4070) | gemma4:12b, bonsai-2:27b (8.3 GB, a 27B that fits) | qwen2.5-coder:14b (Q4) | gemma4:12b, bonsai-2:27b |
| 16 GB VRAM (RTX 5060 Ti 16GB, RTX 5070 Ti, RTX 4080, RTX 5080) | gpt-oss:20b (95 tok/s, fits at 64K), ornith-1.5:9b (72), bonsai-2:27b (44) | gpt-oss:20b, qwen2.5-coder:14b (Q5) | gemma4:12b-it-qat (53), ornith-1.5:9b |
| 24 GB VRAM (RTX 3090, RTX 4090) | ornith-1.5:35b (215), qwen3.8:27b, gpt-oss:20b (195), gemma4:26b | qwen3-coder:30b, devstral-small-2, glm-4.7-flash | nemotron-3.5-bolt (114), qwen3.8:27b, gemma4:26b |
| 32 GB VRAM (RTX 5090), sized from manifests and our 4090 loads, not run | nemotron-3.5-bolt fully on the GPU (24.7 GB of weights, vision projector, and drafter), every 24 GB pick with room left for a second model | qwen3-coder:30b, devstral-small-2, glm-4.7-flash with headroom for long context | nemotron-3.5-bolt |
| 48 GB+ VRAM (2x RTX 3090, RTX 6000 Ada) | llama3.3:70b (43 GB), gpt-oss:120b on an 80 GB card (65 GB download), mistral-medium-3.5:128b on 96 GB+ | qwen3-coder:30b (Q8), devstral-small-2 (Q8, 26 GB) | qwen3-vl:32b, llama3.2-vision:90b |
| 16 GB Mac (M4, unified memory) | gemma4:e4b-it-qat (30), bonsai-2 (27), qwen3.5:9b on MLX (24) | qwen2.5-coder:7b | gemma4:e4b-it-qat, qwen3.5:9b |
The 16 GB row is the one most people buy into, and it’s more capable than its size suggests. On an RTX 5060 Ti, gpt-oss:20b loaded at 12.7 GB with the 4K default and only 12.8 GB at a 64K context, because its sliding-window attention keeps the KV cache small, so it stays 100% on the GPU at 95 tok/s for long coding sessions. The models that look like a fit by file size are the trap. qwen3.8:27b (17 GB) loaded 73% on the GPU and managed 15 tok/s, and devstral-small-2 fell to 5.5 tok/s at 64K. If you’re buying a card for this row, the RTX 5060 Ti 16GB we measured on is sold as the ASUS Prime RTX 5060 Ti 16GB (paid link) among other brands, and the GPU buying guide for local LLMs ranks the alternatives by VRAM per dollar.
The RTX 5070 Ti is the other 16 GB card worth a look, and it holds exactly the same models, so the choice comes down to speed and power: in our RTX 5070 Ti vs 5060 Ti benchmarks it generated 1.66x to 1.85x faster on the same models, because it has twice the memory bandwidth, but it is rated at 300 W against 180 W. Neither card changes what fits, and the newest coding model shows it: Flint’s 23 GB download is too big for both, so a 16 GB coding box stays on gpt-oss:20b or qwen2.5-coder:14b.
On Apple Silicon, treat unified memory as VRAM and keep about a quarter of it for macOS, since Metal on our 16 GB M4 reported 11.8 GiB usable. A 32 GB Mac behaves like a 24 GB card for model choice, a 64 GB Mac like a 48 GB card, and a 128 GB Mac is the smallest single box for nemotron-3.5-super (90 GB at Q4). Expect a fraction of a desktop GPU’s speed. qwen3.5:9b generated 24 tok/s on the M4 against 128 on the RTX 4090, and ornith-1.5:9b 15 against 141. If the memory ceiling matters more than speed, the mini PCs worth buying for local AI take the unified-memory route, where a 128GB Ryzen AI Max+ mini PC holds models no consumer card can, and unified memory vs VRAM explains the trade-off.
Ollama models list: list installed, running and new models
Run ollama list (or its alias ollama ls) to list every Ollama model installed on your machine, and ollama ps to list the ones loaded in memory right now. Neither command can see the library on ollama.com, because the CLI has no search command, so models you haven’t pulled are found on the website or checked against the registry, both covered below. These are the commands that list models, and the columns worth reading in each:
| Command | What it lists | Read this |
|---|---|---|
ollama list, ollama ls | Every model on disk | SIZE is the download size, the floor for the memory it needs |
ollama ps | Models loaded in memory | PROCESSOR shows the GPU and CPU split, CONTEXT the window it loaded with |
ollama show <model> | One installed model | Parameters, context length, quantization, capabilities, minimum Ollama version |
curl localhost:11434/api/tags | Installed models as JSON | Name, size in bytes, digest, quantization |
curl localhost:11434/api/ps | Loaded models as JSON | size_vram against size, which is how a script spots a model spilling into system RAM |
Start with the installed list:
ollama listThis is the list from the RTX 5060 Ti test instance in October, after pulling the models benchmarked on it. The SIZE column is the download size, which is the floor for the memory a model needs once loaded.
NAME                       ID              SIZE      MODIFIED
devstral-small-2:latest    24277f07f62d    15 GB     4 minutes ago
qwen3.8:27b                aaee06c39dcf    17 GB     25 minutes ago
llama3.1:8b                46e0c10c039e    4.9 GB    27 minutes ago
nimble:latest              6aa3fde96874    9.5 GB    28 minutes ago
bonsai-2:27b               f3c4f4208659    8.3 GB    28 minutes ago
gemma4:12b-it-qat          38044be4f923    7.2 GB    31 minutes ago
ornith-1.5:9b              e5df7dcdd8a2    6.6 GB    31 minutes ago
gpt-oss:20b                f38aa0c53da5    13 GB     33 minutes ago
qwen3.5:9b                 56671c2ab938    6.6 GB    33 minutes ago
bonsai-2:latest            c8b5462f8688    3.2 GB    35 minutes ago
Scripts and dashboards should read the same list from the REST API instead of parsing the table. The /api/tags endpoint returns JSON with the name, size in bytes, digest, and quantization of every local model.
curl -s http://localhost:11434/api/tags | jq -r '.models[] | "\(.name)\t\(.size)"'Each line is a model name and its size in bytes, tab separated, ready for sort or a monitoring check.
List running models with ollama ps
ollama ps answers the question ollama list can’t, which is whether a loaded model actually sits on your GPU. Send the model any prompt so it loads, then list what’s running:
ollama psWith the small Bolt loaded on the CPU-only lab VM, PROCESSOR reads 100% CPU, which on a machine with a graphics card would mean the model missed the card entirely:
NAME                     ID              SIZE      PROCESSOR    CONTEXT    RUNNER      UNTIL
nemotron-3.5-bolt:e4b    69f2be39b309    2.9 GB    100% CPU     4096       llamacpp    4 minutes from now
On a GPU box the line you want is 100% GPU. A split such as 27%/73% CPU/GPU means part of the model spilled into system RAM, and the 16 GB benchmark table further down shows what that does to speed. Don’t size a second model off the SIZE column for Bolt, though. It said 2.9 GB here while the llama-server process behind it held 8.5 GiB resident, and the VM’s used memory went from 0.5 to 8.9 GiB when the model loaded, so check free -m or nvidia-smi instead.
Check a model’s details with ollama show
Before you build a workflow on a model, read what Ollama knows about it. Since 0.40.7 the output also names the renderer and parser the model uses and where its chat template comes from, which is the first thing to check when a model’s tool calls or thinking blocks come back malformed. Here it is for the 2B decision model:
ollama show d3:2bThe requires line is the one that saves a support ticket. This model needs Ollama 0.40.9 or newer, so upgrade the server before you build anything on it:
  Model
    architecture        qwen35
    parameters          2.4B
    context length      262144
    embedding length    2048
    quantization        Q8_0
    requires            0.40.9
    renderer            d3
    template source     renderer

  Capabilities
    decision
    vision

  Projector
    architecture        clip
    parameters          331.42M
    embedding length    1024
    dimensions          2048

  Parameters
    num_ctx      4096
    num_batch    4096
Capabilities is the other line to read. This one lists decision and vision but not completion, so a chat frontend won’t offer it for conversation. The API returns the new values as the renderer, parser and template_source fields of /api/show, and parser comes back null for this model because it never generates free text to parse.
Browse Ollama models you haven’t pulled
There is no CLI command for the remote library. Ollama 0.40.11 rejects the obvious guess, and ollama show only knows about models already on disk:
ollama search flint
ollama show flint
Both fail before anything is downloaded:
Error: unknown command "search" for "ollama"
Error: model 'flint:latest' not found
Browse ollama.com/search instead, which sorts the whole catalogue by popularity or newest, and open a model’s Tags tab to see every quantization with its size and context window. To check a tag from a script before committing to a long download, ask the registry for its manifest. It returns the size of every layer without pulling anything:
curl -s https://registry.ollama.ai/v2/library/nemotron-3.5-bolt/manifests/e4b | jq '[.layers[] | {mediaType, size}]'The new E4B Bolt (7.5B parameters in ollama show) is more than its weights, and keep the :e4b tag, because plain nemotron-3.5-bolt pulls the 25 GB 74B model. The 6.2 GB model layer comes with a 992 MB vision projector and a 737 MB draft model for speculative decoding, so the Linux pull is 7.9 GB:
[
  {
    "mediaType": "application/vnd.ollama.image.model",
    "size": 6180446208
  },
  {
    "mediaType": "application/vnd.ollama.image.projector",
    "size": 991551808
  },
  {
    "mediaType": "application/vnd.ollama.image.draft",
    "size": 736812096
  },
  {
    "mediaType": "application/vnd.ollama.image.template",
    "size": 13
  },
  {
    "mediaType": "application/vnd.ollama.image.license",
    "size": 2620
  },
  {
    "mediaType": "application/vnd.ollama.image.params",
    "size": 64
  }
]
A 404 with MANIFEST_UNKNOWN means the tag doesn’t exist, which is what deepseek-v4.1-flash returns for latest while its cloud tag answers 200. Add up the layer sizes and compare them with your VRAM before you start a pull that could run for half an hour.
New local models worth pulling
These are the additions worth putting on the shortlist, most of them released or updated since August. Sizes are the default tag as ollama list or the library page reports it, the context is the trained maximum from the model page, and any speed quoted in the last column is our own measurement where we ran the model (RTX 4090 unless noted).
| Pull | Size | Context | What it is |
|---|---|---|---|
flint | 23 GB | 256K | Recursive’s 40B mixture-of-experts coding model (about 2.5B active) with tools and thinking, Apache 2.0. macOS only in 0.40.8, Linux and Windows since 0.40.9. We didn’t run it: 23 GB of weights before any context rules out every 16 GB card and leaves a 24 GB card only a GB or two for the KV cache |
nemotron-3.5-bolt:e4b | 7.9 GB | 128K on the page, 64K in ollama show | The small Bolt, built on Gemma 4, with vision, tools, and its own draft model, added in 0.40.10. On four vCPUs of an old i7-6700 with no GPU it generated 7.1 tok/s against 11.3 for llama3.2:3b, with thinking on by default |
d3 | 3.2 to 30 GB | 256K | vLLM Semantic Router’s decision models (2b, 4b, 9b, 27b) with image input. The 2b answers in about two seconds on a CPU, as the decision-model section shows |
nemotron-3.5-bolt | 25 GB | 256K | NVIDIA’s 74B mixture-of-experts (9B active) with vision, tools, and thinking, distilled from Nemotron 3.5 Super and shipped with its own draft model. Runs on a 24 GB card at 114 tok/s with part of its experts in system RAM |
ornith-1.5:9b, ornith-1.5:35b | 6.6 / 22 GB | 256K | 9B dense and 35B-A3B mixture-of-experts with vision, tools, and thinking, plus a 122b released in October. The 35b fits a 24 GB card whole and generated at 215 tok/s. No tag is called latest, so pull a size |
bonsai-2 | 0.9 to 8.3 GB | 256K | Prism ML’s ternary-weight family (2b, 4b, 9b, 27b) in the new q2_0 format. The 27b is 8.3 GB, so a 27B with vision and tools fits a 12 GB card |
devstral-small-2 | 15 GB | 384K | Mistral’s 24B coding agent model with vision and tools, Apache 2.0. Just misses a 16 GB card, with 97% on the GPU at a 4K context and 22.5 tok/s on an RTX 5060 Ti |
glm-4.7-flash | 19 GB | 198K | Z.ai’s 30B-class coding and agent model with tools and thinking, MIT licensed |
embeddinggemma-2 | 1.3 GB | 8K | Google’s multimodal embedder (744M) that takes text, images, and audio and returns 768-dim vectors |
nimble, clef, pplx-decider | 9.5 / 20 / 17 GB | 256K | Decision models that answer yes/no, pick a label, or score, and return probabilities instead of text. Covered in their own section below |
nemotron-3.5-super | 90 GB | 1M | The 120B (12B active) parent of Bolt. Q4_K_M needs a 96 GB card or a 128 GB Mac |
qwen3.8:27b | 17 GB | 256K | Newest dense Qwen. Vision, tools, and thinking with low / medium / xhigh effort levels. Speculative decoding on by default |
qwen3.6:35b | 22 GB | 256K | 35B mixture-of-experts sibling of the 27b, with draft decoding. 247 tok/s on a 24 GB card in September |
muse-glimmer:30b | 18 GB | 128K | Meta’s 30B agentic model with a vision encoder, distilled from Muse Spark. Setup notes in how to run Muse Glimmer locally |
qwen3.8-flash-next:125b-a6b-q4_K_M | 120 GB | 256K | 125B MoE (6B active), the preview of the Qwen4 architecture. Started as MLX only, and GGUF Q4_K_M and Q8_0 tags now exist alongside the MLX builds. There is no latest tag |
Several of the biggest 2026 releases never get a local tag at all. deepseek-v4-pro, deepseek-v4.1-flash, kimi-k3, glm-5.3, glm-5.3-flash, minimax-m3.1-flash, mistral-large-4, muse-spark-open, and beam are published as :cloud tags only, so ollama run kimi-k3:cloud works while a plain ollama pull kimi-k3 has nothing local to fetch. Try it with DeepSeek and the pull fails fast:
ollama pull deepseek-v4.1-flashOllama 0.40.11 tells you which tag does exist rather than leaving you to guess:
Error: pull model manifest: file does not exist

"deepseek-v4.1-flash:cloud" is available as a cloud model. Try:
  ollama pull deepseek-v4.1-flash:cloud
Don’t wait for a local DeepSeek tag to appear, because no desktop could hold it. The DeepSeek-V4.1-Flash-1017 weights take about 510 GB on Hugging Face, which is a multi-GPU server before you add a single token of KV cache, not a 24 GB card or a 128 GB Mac. Kimi K3 does have a local route outside the Ollama library, the GGUF builds covered in how to run Kimi K3 locally, and the cloud pricing for the rest is further down this page.
Install Ollama in 30 seconds
The same one-liner works on every supported Linux. On macOS download the .dmg from ollama.com/download. On Windows use the .exe installer.
curl -fsSL https://ollama.com/install.sh | sh
ollama --version
# ollama version is 0.40.11
The installer detects your GPU, drops the binary into /usr/local/bin/ollama, creates an ollama system user, and registers a systemd unit at /etc/systemd/system/ollama.service. The API listens on 127.0.0.1:11434 after install. For the multi-OS walkthrough with SELinux, firewall, and Nginx reverse proxy, follow the Ollama install guide for Rocky Linux 10 / Ubuntu 24.04. For the complete CLI, REST API, Python SDK, Modelfile, and environment variable reference, keep the Ollama commands cheat sheet open in a separate tab. This article focuses on which model to run, why, and how it performs.
On a Mac, Ollama 0.40 and later run supported architectures on Apple’s MLX runtime by default, and the library serves a different build to match. The same qwen3.5:9b pull was 6.6 GB on our Linux GPUs and 7.6 GB on the M4, and ollama ps lists the runner for each loaded model, so you can see which one you got. Not every tag has an MLX build: gemma4:e4b-it-qat, bonsai-2, and ornith-1.5 loaded on the llama.cpp runner on the same Mac.
Browse the Ollama model library by job
Ollama’s library page lists hundreds of tags, but most fall into five jobs: chat, coding, vision, embeddings, and since September, decision models that classify instead of writing text. Treat them separately. A coding model is not a chat model with extra steps, an embedding model is not a tiny chat model, and a decision model can’t hold a conversation at all, so choose the job first, then the size. For how these open families score against each other on public leaderboards, see the open-source LLM comparison table.
Popularity is a poor filter on its own, because the top of that page is still llama3.1 and deepseek-r1, two generations behind what fits the same memory now. Filter on what the model can do and what its license lets you ship instead.
Capabilities and licenses at a glance
One grid answers the questions people ask before a pull: does it call tools, can it think, does it read images, how much context, and can I use it commercially. Capabilities come from each model’s library page, sizes from ollama list on our test machines, and licenses from the license layer in the model’s registry manifest.
| Model | Size | Context | Tools | Thinking | Vision | License |
|---|---|---|---|---|---|---|
gpt-oss:20b | 13 GB | 128K | yes | yes | no | Apache 2.0 |
qwen3.8:27b | 17 GB | 256K | yes | yes | yes | Apache 2.0 |
qwen3.6:35b | 22 GB | 256K | yes | yes | yes | Apache 2.0 |
qwen3.5:9b | 6.6 GB | 256K | yes | yes | yes | Apache 2.0 |
gemma4:12b | 8.0 GB | 256K | yes | yes | yes, plus audio | Apache 2.0 |
gemma4:26b | 18 GB | 256K | yes | yes | yes, plus audio | Apache 2.0 |
ornith-1.5:9b / :35b | 6.6 / 22 GB | 256K | yes | yes | yes | not stated |
bonsai-2:27b | 8.3 GB | 256K | yes | yes | yes | Apache 2.0 |
nemotron-3.5-bolt | 25 GB | 256K | yes | yes | yes | OpenMDW 1.1 |
nemotron-3.5-bolt:e4b | 7.9 GB | 64K in ollama show, 128K on the library page | yes | yes, on by default | yes, plus audio | OpenMDW 1.1 |
flint | 23 GB | 256K | yes | yes | no | Apache 2.0 |
d3:2b | 3.2 GB | 256K | no, decision only | no | yes | Apache 2.0 |
nemotron-3.5-lightning | 25 GB | 1M | yes | yes | no | NVIDIA Open Model License |
devstral-small-2 | 15 GB | 384K | yes | no | yes | Apache 2.0 |
glm-4.7-flash | 19 GB | 198K | yes | yes | no | MIT |
qwen3-coder:30b | 18 GB | 256K | yes | no | no | Apache 2.0 |
muse-glimmer:30b | 18 GB | 128K | yes | yes | yes | Apache 2.0 |
lfm2.5 | 5.2 GB | 125K | yes | yes | no | LFM Open License 1.0 |
llama3.1:8b | 4.9 GB | 128K | yes | no | no | Llama 3.1 Community |
deepseek-r1:8b | 5.2 GB | 128K | yes | yes | no | MIT |
Two licenses on that list need a read before you ship anything built on them. The Llama 3.1 Community License needs a separate grant from Meta above 700 million monthly active users and a “Built with Llama” notice when you distribute a product built on it, and the NVIDIA and OpenMDW agreements on the Nemotron models are their own documents rather than an OSI license. ollama show --license <model> prints the full text for anything you have pulled. Ornith’s manifest ships no license layer and its page names none, so treat it as unknown until the authors say otherwise.
General chat and reasoning models
| Model | Sizes on Ollama | Default file | Ctx | Tools | Best for |
|---|---|---|---|---|---|
gpt-oss | 20b, 120b | 13 / 65 GB | 128K | yes | OpenAI’s open-weight MoE (Apache 2.0). 20b runs in 16 GB, 120b on one 80 GB GPU. The strongest open general/reasoning pick for most 2026 rigs |
llama3.3 | 70b | 43 GB | 128K | yes | Still a solid, widely supported 70B baseline. Performs near Llama 3.1 405B. No longer the outright best open 70B (gpt-oss and Qwen3 caught up) |
llama3.2 | 1b, 3b | 1.3 / 2.0 GB | 128K | yes | On-device, edge, mobile, fast tool routing, lightweight chat |
llama3.1 | 8b, 70b, 405b | 4.9 GB | 128K | yes | Solid 8B baseline, the safe default. 405B for serious infrastructure |
llama4 | 16x17b (Scout), 128x17b (Maverick) | 67 / 245 GB | 10M / 1M | yes | Natively multimodal MoE. Scout needs ~60 GB+ VRAM, Maverick is multi-GPU/enterprise only |
mistral-nemo | 12b | 7.1 GB | 128K | yes | Drop-in upgrade from Mistral 7B. Multilingual. The right “step up from 8B” pick |
mistral-small | 22b, 24b | 14 GB | 32K to 128K | yes (native) | Agentic workloads, JSON output, function calling, the strongest mid-range chat model |
mistral | 7b | 4.1 GB | 32K | partial | Apache 2.0 license requirement, legacy compatibility. New projects should pick Nemo |
mixtral | 8x7b, 8x22b | 26 / 80 GB | 32K / 64K | yes | Quality per active parameter, but loads all experts in memory. Needs ≥48 GB |
gemma4 | e2b, e4b, 12b, 26b, 31b | 8.0 / 18 / 20 GB | 256K | yes (native) | The current Gemma. Every size is multimodal with tool-calling and thinking built in. The 12b (dense, 11.9B) fits 12 GB. The 26b is a 26B-A4B MoE that runs at ~4B speed on a 24 GB card. Successor to gemma3 |
gemma3 | 270m, 1b, 4b, 12b, 27b | varies | 32K (1B) / 128K | yes | Best multilingual coverage (140 languages). 4b and up include vision. Superseded by gemma4 for new work |
deepseek-r1 | 1.5b, 7b, 8b, 14b, 32b, 70b, 671b | varies | 128K / 160K | yes | Reasoning, math, chain-of-thought workloads. Slower because the model thinks before answering (latest update is 0528) |
deepseek-v3.1 | 671b | 404 GB | 160K | yes | The last DeepSeek generation with local weights on Ollama (671B / ~37B active). Hybrid thinking and non-thinking. Serious multi-GPU territory |
deepseek-v4-pro, deepseek-v4.1-flash | cloud only | n/a | varies | yes | The current DeepSeek models. On Ollama they exist only as :cloud tags |
granite4.2 | 3b, 8b, 30b | 2.2 / 5.3 / 17 GB | 128K | yes | IBM’s dense Apache 2.0 family with thinking mode and structured JSON output. Solid enterprise RAG pick |
lfm2.5 | 8b, 24b | 5.2 / 15 GB | 125K / 128K | yes | Liquid AI hybrid built for on-device agents. The fastest 5 GB-class model we have measured on Ollama |
muse-glimmer | 30b | 18 GB | 128K | yes | Meta’s local agentic model with vision, distilled from Muse Spark |
nemotron-3.5-lightning | 30b | 25 GB | 1M | yes | NVIDIA’s 3B-active MoE for always-on agents. Needs more than 24 GB to stay on the GPU |
mistral-medium-3.5 | 128b | 80 GB | 256K | yes | Dense 128B Mistral flagship with vision and configurable reasoning effort |
phi4 | 14b | 9.1 GB | 16K | weak | Dense knowledge per parameter, STEM reasoning. Avoid for tool-using agents |
qwen2.5 | 0.5b, 1.5b, 3b, 7b, 14b, 32b, 72b | varies | up to 128K | yes | Best multilingual + reasoning under 32B, especially for Chinese, Japanese, Korean |
qwen3.8 | 27b | 17 GB | 256K | yes | The newest Qwen. Dense 27B with vision, tools, and adjustable thinking depth. Fits a 24 GB card at Q4 and runs speculative decoding by default |
qwen3.6 | 27b, 35b | 17 / 22 GB | 256K | yes | Tuned for agentic coding and long-horizon reasoning. The 27b is dense and multimodal. The 35b is a mixture-of-experts that fits 24 GB at an 8K context and generates at 7B-class speed |
qwen3.5 | 0.8b, 2b, 4b, 9b, 27b, 35b, 122b | varies | 256K | yes | Hybrid Gated-Delta + sparse-MoE generation. Every size is multimodal with tools and thinking. The 9b fits 8 GB, the 27b fits 24 GB, the 122b is cloud/multi-GPU |
qwen3 | 0.6b, 1.7b, 4b, 8b, 14b, 30b, 32b, 235b | varies | 40K to 256K | yes | Still fine where you have tooling built around it. Dense up to 32b, MoE at 30b/235b. Superseded by qwen3.5, qwen3.6, and qwen3.8 for new work |
Coding models
| Model | Sizes | Ctx | FIM | Best for |
|---|---|---|---|---|
qwen3-coder | 30b, 480b | 256K (to 1M) | yes | The new local-coding leader. 30b (18 GB) is a 30B-A3B MoE that fits a 24 GB card at Q4 and is the strongest model most people can run locally for agentic coding |
qwen2.5-coder | 0.5b, 1.5b, 3b, 7b, 14b, 32b | 32K | yes | The best small and mid-size coding family (0.5b to 32b). Reach for it when you cannot run qwen3-coder:30b. The 32B still scores near GPT-4o on Aider |
deepseek-coder-v2 | 16b, 236b | 16b: 160K, 236b: 4K | yes | Long-file refactors, repo-aware tasks. 16B is MoE so the active param count is small. The 236b on Ollama is capped at 4K context |
codegemma | 2b, 7b | 8K | yes (2b code variant) | Lightweight inline completion in editor plugins |
starcoder2 | 3b, 7b, 15b | 16K | yes | Permissive license, 600+ languages on the 15B. Reach for it when license matters |
deepseek-coder | 1.3b, 6.7b, 33b | 16K | yes | Legacy projects and the 1.3B for edge devices. New work, pick V2 or qwen2.5-coder |
devstral | 24b | 128K | yes | Local agentic coding from Mistral. Needs ≥16 GB VRAM |
Vision (multimodal) models
| Model | Sizes | Ctx | Notes |
|---|---|---|---|
qwen3.8 | 27b | 256K | Vision is built into the newest general Qwen, so one 17 GB pull covers chat, tools, and images on a 24 GB card |
muse-glimmer | 30b | 128K | Meta’s agentic model with a dedicated perception encoder. Built to act on what it sees |
qwen3-vl | 2b, 4b, 8b, 30b, 32b, 235b | 256K (to 1M) | The strongest open vision-language family on Ollama now. Best on screenshots, UI, and visual agents. The 8b fits 8 GB |
gemma4 | 12b, 26b, 31b | 256K | The current compact multimodal pick. Vision on every size plus tool-calling and thinking. The 12b fits 12 GB and the 26b is an A4B MoE that stays fast on a 24 GB card. Replaces gemma3 for new work |
gemma3 | 4b, 12b, 27b | 128K | Still strong on document, chart, and OCR work (DocVQA 85.6 on the 27B per Google’s report). Superseded by gemma4 |
mistral-small3.2 | 24b | 128K | Strong 24B multimodal with native function calling. Good when you want vision plus tool use |
llama3.2-vision | 11b, 90b | 128K | Still solid and tool-capable, but a generation older than qwen3-vl |
llava | 7b, 13b, 34b (1.6) | 32K (7/13B), 4K (34B) | Older but light, good for quick CPU vision experiments |
Embedding models
| Model | Dim | Ctx | Size | When to use |
|---|---|---|---|---|
embeddinggemma | 768 (MRL to 128) | 2K | 622 MB | Newest on-device embedder (300M, built on Gemma 3). 100+ languages and Matryoshka dims you can truncate to 512/256/128 to shrink the vector store |
nomic-embed-text | 768 | 2K | 274 MB | The long-time default for local RAG. Beats text-embedding-3-small on most benchmarks |
mxbai-embed-large | 1024 | 512 | 670 MB | Higher recall, English-leaning |
bge-m3 | 1024 | 8K | 1.2 GB | Multilingual + long-document RAG, also returns sparse vectors |
Check whether a model fits your VRAM
The first question every Ollama user gets wrong is “will this model fit?” because they only count weights. The full memory footprint is weights + KV cache + runtime overhead, and the KV cache scales with context length. Current Ollama sizes the default context to your VRAM: 4K under 24 GiB, 32K from 24 to 48 GiB, and 256K at 48 GiB or more, always capped at the model’s trained maximum (older releases used a flat 2,048). The cut-off is generous in practice. Our RTX 4090 reported 23.5 GiB and the server log still chose 32768, while the 15.5 GiB RTX 5060 Ti got 4096. So on a 24 GB card the KV cache is already large by default, which is exactly why a model that looks like it fits by weight alone still runs out of memory. Use this formula.
VRAM_weights ≈ (params_billions × bits_per_weight / 8) GB
VRAM_kv      ≈ num_layers × 2 × n_kv_heads × head_dim × num_ctx × 2 bytes  (fp16 KV cache)
Total        ≈ VRAM_weights × 1.15 + VRAM_kv + ~0.5 GB Ollama runtime
The 1.15x factor accounts for activations and CUDA workspace. The KV term is the one people get wrong, because modern models use grouped-query attention (GQA), so n_kv_heads is small (Llama 3.1 8B has 8 KV heads at head_dim 128, a 1024-wide cache, not the full 4096 hidden size). That is why the KV cache is a fraction of what a naive estimate predicts. Worked example for Llama 3.1 8B at the default Q4_K_M (4.5 bits per weight).
weights : 8 × 4.5 / 8 = 4.5 GB → ×1.15 ≈ 5.2 GB
KV @ 8K : 32 layers × 2 × 8 kv_heads × 128 head_dim × 8192 ctx × 2 ≈ 1.1 GB
KV @ 32K: same, with 32768 ctx ≈ 4.3 GB
total   : ~6.8 GB at 8K, ~10 GB at the 24-48 GB tier's 32K default
Drop the same model to num_ctx=2048 and KV falls to ~0.3 GB. The 8B fits in well under 6 GB. Even at its 32K default it only reaches ~10 GB, which is why the screenshot below shows Llama 3.1 8B using about 9 GB on a 24 GB card. Where the large default actually bites is the 30B-plus dense class. A dense 32B at Q4 is about 20 GB of weights before any cache, which is why our September run capped deepseek-r1:32b at 8K, where it loaded 21.8 GB fully on the GPU and generated 43.9 tok/s. The first fix is quantizing the KV cache with OLLAMA_KV_CACHE_TYPE=q8_0 (or q4_0), which halves or quarters it with negligible quality loss. It needs flash attention, which Ollama already turns on automatically where the GPU supports it (our RTX 5060 Ti server log shows --flash-attn auto on every load), so set OLLAMA_FLASH_ATTENTION=1 only to force it. You can also cap the context with OLLAMA_CONTEXT_LENGTH on the server or num_ctx per request.
Choose a quantization: Q4_K_M vs Q5_K_M vs Q8_0 vs FP16
Quantization is the lever that determines whether a 70B model fits on your hardware. Most users see Q4_K_M on a tag and assume “4-bit”. That is wrong. K-quants pack scale and minimum metadata alongside weights, so the actual bits-per-weight differ from the nominal label. The table below uses the real bits-per-weight from the llama.cpp k-quants spec.
| Tag | Bits / weight | Size vs FP16 | Quality tier | Pick when |
|---|---|---|---|---|
| FP16 / F16 | 16.0 | 100% | Reference | Fine-tuning, eval baselines, you have 24+ GB VRAM and want zero degradation |
Q8_0 | 8.5 | ~53% | Indistinguishable from FP16 | You have RAM to spare, want max quality, do not want to think about it |
Q6_K | 6.5625 | ~41% | Near lossless | Q5 feels just slightly off, Q8 will not fit |
Q5_K_M | 5.5 | ~34% | Excellent | The quality pick when VRAM permits |
Q4_K_M | 4.5 | ~28% | Recommended default | The pragmatic best balance. Most Ollama defaults are Q4_K_M |
Q4_K_S | 4.5 (smaller scales) | ~26% | Good | Squeeze a model into one less GB |
Q3_K_M | 3.4375 | ~22% | Noticeable degradation | Last resort to fit a 70B in 24 GB. Expect quality loss |
Q2_K | 2.625 | ~17% | Quality cliff | Emergency only, 70B on 16 GB at the cost of correctness |
IQ4_XS / IQ3_S | 4.25 / 3.44 | ~26% / ~22% | Better than Q4_0/Q3 at the same size | I-quants when available, in preference to legacy Q4_0/Q5_0 |
Q4_0, Q5_0 | 4.5, 5.5 | similar | Legacy round-to-nearest | Avoid in 2026 unless required for compatibility |
Three rules cover 95 percent of cases:
- Default to Q4_K_M. That is what Ollama ships when you run
ollama pull llama3.1with no tag. The quality cost is small, the size win is large. - Bump to Q5_K_M or Q6_K when you have ~30 percent VRAM headroom and the task is quality sensitive. Code review, technical writing, anything that gets shipped to humans.
- Drop to Q3_K_M only to fit a bigger model class, and verify quality on your own evals before committing. Llama 3.1 70B at Q3_K_M usually beats Llama 3.1 8B at Q8_0 for hard reasoning, but not always. If your eval prompts fail at Q3, downsize the model class instead of squeezing the bits.
Use Q8_0 only for embedding models, fine-tuning baselines, and side-by-side evals against FP16 ground truth. For chat and coding work, the perplexity gap between Q5_K_M and Q8_0 is too small to justify the size penalty.
To override Ollama’s default and pull a specific quantization, append the tag explicitly.
ollama pull llama3.1:8b-instruct-q5_K_M
ollama pull qwen2.5-coder:7b-instruct-q8_0
ollama pull deepseek-r1:14b-qwen-distill-q4_K_M
Browse ollama.com/library and click any model to see the full tag list. Not every quantization is published for every size, especially for smaller distilled models.
Pick between Llama 3.1, 3.2, and 3.3
Three Llama generations live on Ollama at the same time and they are not interchangeable.
llama3.3:70bis still a strong 70B for general chat if you have 48 GB or more of VRAM, performing near Llama 3.1 405B at a fraction of the size. It is no longer the outright best open model its size class, gpt-oss and Qwen3 have closed the gap, but it remains a widely supported, well-understood baseline.llama3.2:1bandllama3.2:3bare the small siblings (no 8B in this generation). They exist for on-device, mobile, and edge inference, and they are surprisingly capable at tool routing for their size.llama3.1:8bremains the safe default for general chat under 12 GB VRAM. There is no Llama 3.2 8B and Llama 3.3 starts at 70B, so 3.1 still owns the 8B slot.llama3.1:70bis superseded by 3.3 for chat. Keep it only when you need the exact 3.1 baseline (reproducibility, fine-tuned downstream work).llama3.1:405bneeds serious infrastructure (~230 GB at Q4_K_M). Most teams should pickllama3.3:70binstead.llama4:16x17b(Scout) and:128x17b(Maverick) are the natively multimodal MoE generation. Scout is 67 GB on disk with a huge context window and needs ~60 GB+ VRAM. Maverick is 245 GB and multi-GPU territory. Real, but for most readers gpt-oss or Qwen3 are the practical “frontier on my own box” picks.
Run gpt-oss, OpenAI’s open-weight models on Ollama
gpt-oss is OpenAI’s open-weight model family, the first since GPT-2, released under Apache 2.0 and available on Ollama in two sizes. Both are mixture-of-experts models shipped in MXFP4 precision, which is why they fit in far less memory than their parameter counts suggest.
gpt-oss:20b(13 GB) is the one most people run. It loaded at 12.7 to 13 GB in our runs, even at a 64K context, so it runs comfortably on a 16 GB or 24 GB GPU, and lands in the o3-mini class on reasoning. This is the default gpt-oss pull for a single consumer card.gpt-oss:120b(about 65 GB) targets a single 80 GB GPU or a multi-card box and approaches o4-mini on core reasoning. If you cannot fit it locally, run it as a cloud model (below).
Pull and run it like any other model. The 20B is a genuine step up in reasoning over similarly-sized chat models and has strong tool-calling, which makes it a good agent backbone.
ollama run gpt-oss:20bOn a 16 GB card it loads at 12.7 GB with the default 4K context and only 12.8 GB at 64K, so it is the rare 20B that leaves room for long sessions.
Sort out the Mistral family
The Mistral family is the most confusing namespace on Ollama because four distinct model lines share the prefix.
mistral:7bis the original Mistral 7B Instruct, Apache 2.0 licensed. Pull it for license-sensitive deployments and legacy compatibility. New projects should reach for Nemo.mistral-nemo:12bis the modern 12B model, 128K context, multilingual. The right “step up from 8B” pick for quality-sensitive chat that still fits in 12 GB VRAM at Q4_K_M.mistral-small:22b/:24bis the strongest mid-range Mistral. Native function calling, JSON output, and the model to use when you need agentic behavior without burning a 70B-class budget.mixtral:8x7bandmixtral:8x22bare mixture-of-experts. They activate only ~13B parameters per token but you still load all weights into memory: 26 GB and ~80 GB respectively. Pull them when you have surplus VRAM and want the quality-per-active-param tradeoff.devstral:24bis the agentic coding variant from Mistral. Pair it with a coding harness like Aider or OpenCode for local agent-style workflows.magistral:24bis Mistral’s reasoning model (Apache 2.0, 128K context), the option when you want chain-of-thought in the Mistral family rather than reaching for an R1 distillation.
Use Gemma 3 and Gemma 4 for multilingual and vision work
Gemma 3 from Google ships in five sizes (270m, 1b, 4b, 12b, 27b) and from 4B and up the model is multimodal: image input plus text output. Three reasons to pick it:
- Multilingual coverage of 140 languages, the broadest of any open model in 2026. If your users write in Swahili, Vietnamese, Tagalog, or Amharic, this is the model.
- Strong vision performance. Google’s Gemma 3 report puts the 27B at 85.6 on DocVQA, ahead of llava and competitive with closed VLMs on document tasks.
- Quantization-aware training (QAT) variants are published as
gemma3:<size>-it-qat. They were trained at low precision so they outperform standard post-training quantizations at the same bit width.
Tool calling on Gemma 3 is weaker than on Llama or Mistral, so if your workload routes to tools or builds agents, look elsewhere. The 1B Gemma 3 is text only with a 32K context (smaller than the 128K its larger siblings get).
Gemma 4 is the current generation and closes that gap. Every size (12b, 26b, 31b, plus the e2b / e4b nano variants) is natively multimodal, and ollama show gemma4:12b now lists vision, audio, tools, and thinking under Capabilities, so the agent and reasoning weaknesses that pushed you off Gemma 3 are gone. The context window jumps to 256K on the 12b and up (the e2b/e4b nano variants stay at 128K). The size math also shifts. gemma4:12b is a dense 11.9B that fits a 12 GB card, while gemma4:26b is a 26B-A4B mixture-of-experts that activates roughly 4B parameters per token, so it runs at small-model speed on a 24 GB GPU. For new multilingual, vision, or document work, start on gemma4 and only drop to gemma3 for the sub-1B sizes gemma4 does not ship.

ollama show gemma4:12b lists vision, audio, tools, and thinking under Capabilities, the multimodal-plus-agent jump over Gemma 3.Run the same ollama show on any model before you wire it into an agent, because a model without tools in that list was not trained for a tool-calling loop.
Tell the real DeepSeek R1 from the distills
This is the single most misunderstood model on Ollama. The real DeepSeek R1 is the 671B parameter MoE available as deepseek-r1:671b (~404 GB on disk), needing serious multi-GPU hardware to run. Every smaller tag (1.5b, 7b, 8b, 14b, 32b, 70b) is a distillation, a smaller base model (Qwen 2.5, Qwen3, or Llama 3.3) fine-tuned on R1’s reasoning traces. They inherit the chain-of-thought style but they are not the same model.
deepseek-r1:1.5b,:7b, and:14bare Qwen 2.5 distillations, and:8b(the default tag) is the newer DeepSeek-R1-0528 distilled onto Qwen3 8B. The 14B is the best local reasoning pick on 12 GB VRAM.deepseek-r1:32bis also Qwen-distilled and the strongest you can run on a 24 GB card at Q4_K_M.deepseek-r1:70bis a Llama 3.3 distillation, not the 671B model.deepseek-r1:671bis the actual R1.
R1 distillations write a long <think>...</think> reasoning block before they answer, so latency is significantly higher than a same-size chat model, and the reasoning text is part of the response (count it in your output token budget). For interactive chat where you do not want chain-of-thought, pick Qwen or Llama instead. For math, code review, and step-by-step problem solving, R1 is the right tool, and the DeepSeek R1 local guide sizes each distillation against real cards. The newer DeepSeek generations split the story. deepseek-v3.1:671b is the last one with local weights in the Ollama library, a hybrid that toggles thinking and non-thinking modes. deepseek-v4-pro and deepseek-v4.1-flash are cloud tags only, and the DeepSeek V4 vs Kimi K3 comparison covers how they stack up.
671b is the original R1.The tag names are the only honest label. Anything below 671b is a Qwen or Llama base model with R1-style reasoning trained in.
Choose between Qwen 2.5, Qwen 3, and Qwen 3.5, 3.6, and 3.8
Qwen from Alibaba is the under-discussed champion of the local LLM scene. The lines to know:
qwen2.5spans 0.5B, 1.5B, 3B, 7B, 14B, 32B, 72B. The best multilingual + reasoning model under 32B, especially strong on Chinese, Japanese, Korean. Use the 7B as a Llama 3.1 8B alternative when you want better non-English performance.qwen2.5-coderis still the best small coding family. The 32B variant scores within a few points of GPT-4o on Aider’s pass-rate benchmark and the 7B is a solid free upgrade over CodeLlama or DeepSeek-Coder for editor-side completion.qwen3was the successor generation. Dense up to 32B, MoE at 30B (A3B) and 235B (A22B), context up to 256K. The 235B ships as two separate builds,Instruct-2507(no chain-of-thought) andThinking-2507(reasoning), after Qwen dropped the hybrid-thinking toggle. Qwen 2.5 and Qwen 3 are still fine where you have existing tooling built around them.qwen3.5andqwen3.6are the versions to pick now.qwen3.5is a hybrid architecture (Gated Delta Networks plus a sparse mixture-of-experts) that spans 0.8B to 122B, and every size is natively multimodal with tools and thinking, so a single pull covers chat, vision, and reasoning: the9bfits an 8 GB card, the27bfits 24 GB, and the122bis cloud or multi-GPU.qwen3.6tightens that for agentic coding and long-horizon reasoning, with a dense27band a35bmixture-of-experts. Confirm the built-in capabilities yourself withollama show qwen3.6:27b, which listsvision,tools, andthinking.qwen3.8:27bis the newest and the one to pull first on a 24 GB card. It keeps the dense 27B shape and vision, adds thinking levels (off, low, medium, xhigh, with medium as the default), and ships with speculative decoding on, which is why it generates at more than twice the speed ofqwen3.5:27bon identical hardware.
For new work on a 24 GB card, start with qwen3.8:27b or qwen3-coder:30b and drop to the 2.5 coder sizes only when VRAM forces it.
Know when to use Phi 4, llava, codegemma, and starcoder2
phi4:14bfrom Microsoft is dense knowledge per parameter and strong on STEM and reasoning. Weak on tool calling and long-context retrieval. Pick it for analytic chat, avoid it for agents.phi4-mini:3.8bis the small variant, a competitor to Llama 3.2 3B and Qwen 2.5 3B for on-device reasoning.llava:7b/:13b/:34bis the older multimodal model. Light, easy to run, but llava 1.6 (the version on Ollama) is outclassed by gemma3 and llama3.2-vision in 2026. Use it for quick CPU vision experiments only.codegemma:7bis Google’s 7B coder. It targets editor-side completion (FIM mode) and is a good lightweight alternative to qwen2.5-coder for inline use.starcoder2:15btrains on 600+ programming languages with a permissive license. The pick when license matters more than raw quality.
Pick an embedding model for local RAG
Embedding models power semantic search, retrieval-augmented generation, deduplication, clustering, and classification. Three picks cover most workloads:
embeddinggemma(622 MB, 300M params, 2K ctx) is the newest pick and a strong default. Built on Gemma 3, it covers 100+ languages and uses Matryoshka representation learning, so you can truncate the 768-dim vector to 512, 256, or 128 dims to shrink your vector store with graceful quality loss.nomic-embed-text:v1.5(274 MB, 768 dim, 2K ctx) is the long-time default. It outperforms OpenAI’stext-embedding-3-smallon most public benchmarks and runs in milliseconds on CPU.mxbai-embed-large(670 MB, 1024 dim, 512 ctx) trades context length for higher recall. English heavy, strong on technical and conversational text.bge-m3(1.2 GB, 1024 dim, 8K ctx) is the right pick for multilingual + long-document RAG. It also returns sparse vectors alongside dense ones, which lets you build hybrid search without two models.
Use the embeddings endpoint, not ollama run.
curl http://localhost:11434/api/embed -d '{
  "model": "nomic-embed-text",
  "input": ["First doc to embed.", "Second doc to embed."]
}'
For pipeline integration, the official ollama-python client wraps this in three lines and is the cleanest way to feed pgvector or Qdrant. The newest option, embeddinggemma-2, also embeds images and audio into the same 768-dim space, which matters if your RAG corpus has screenshots or recorded calls in it. It’s 1.3 GB and returned its first vector in about 3 seconds on a 16 GB M4 MacBook Pro, model load included.
Run decision models for routing and classification
Decision models don’t write text. Since Ollama 0.35 they read a piece of text you call the state and answer typed questions about it: yes or no, one label from a list, or a score on a scale, each with a probability you can put a threshold on. That replaces the usual trick of prompting a chat model to “answer with one word” and parsing whatever comes back. ollama show nimble lists only decision under Capabilities, so chat frontends won’t offer these models for conversation. The ones in the library now:
nimblefrom Bespoke Labs, 9B, Apache 2.0, 9.5 GB at the default 8-bit, 5.6 GB as9b-q4_K_Mnimble-v3, its successor, licensed CC BY-NC 4.0, so noncommercial use onlytev1from Together AI, 0.8B and 4B, the small option for laptopsclefandclef-flashfrom Cloudflare, 27B and 9B, accept images with the state, andclefalso runs asclef:cloudpplx-deciderfrom Perplexity, a 27B fine-tune of Qwen 3.8, 17 GBd3from vLLM Semantic Router, 2B, 4B, 9B and 27B, takes images with the state, needs Ollama 0.40.9 or newerkev(0.8B to 27B),laya(322M and 421M),strands-decider(2B, MLX on Apple Silicon Macs only), and Liquid AI’s vision-capabled1andd1-omni
The fastest way to try one is the --ask flag added to ollama run in 0.40.4. Save a support ticket to a file first.
echo "Order 48213 arrived with a cracked screen. I want my money back, not a replacement." > ticket.txtThen ask a yes/no question about it. The state comes from standard input.
ollama run nimble --ask "Is a refund being requested?" < ticket.txtThe answer and the model’s probability come back on one line.
yes 100%Routing works the same way with --choice, one flag per label, each with a short description the model uses to decide.
ollama run nimble --ask "Which team should handle this?" \
  --choice billing="Payments and refunds" \
  --choice technical="Software problems" \
  --choice shipping="Damaged or lost deliveries" < ticket.txt
This is where the probability earns its place. A cracked screen plus “money back” is half a shipping problem and half a billing problem, and the model says so instead of pretending to be sure:
shipping 68%In a real queue you’d auto-route anything above about 90% and send the rest to a person, which is a rule you can’t write against a chat model’s free text. For scripts, the same model answers over the /v1/systemone endpoint, and you can ask several questions about one state in a single request.
curl -s http://localhost:11434/v1/systemone -d '{
  "model": "nimble",
  "state": "Our checkout has returned 500 errors since 9am.",
  "questions": {
    "label": {
      "type": "choice",
      "instructions": "Which label fits this ticket?",
      "criteria": {
        "billing": "Payments and refunds",
        "bug": "Software errors",
        "account": "Login and account access"
      }
    }
  }
}'
The response carries every label’s probability and generates zero output tokens, which is why it’s fast. On the RTX 5060 Ti the call returned in 0.09 seconds with the model already loaded.
{"model":"nimble","answers":{"label":{"type":"choice","choice":"bug","probabilities":{"billing":0.01588957214904755,"bug":0.9717168615755916,"account":0.012393566275360835},"confidence":0.9575752923633873}},"usage":{"input_tokens":198,"output_tokens":0}}Size the model to the box it runs on. The 8-bit default of nimble loaded at 9.7 GB on the 16 GB GPU, which is fine there, but on a 16 GB M4 MacBook Pro with a browser and an editor open the same 9.3 GB MLX build paged to disk and a single decision took over two minutes. On a 16 GB Mac, pull nimble:9b-q4_K_M or tev1:4b instead, or send the call to clef:cloud, which bills $0.24 per million input tokens and nothing for output.
A small decision model doesn’t need a GPU at all, which makes d3:2b the one to try first on a plain server. On an 8-vCPU VM with no GPU it loaded at 3.7 GB, all on the CPU, and the same two questions about the same ticket came back like this:
ollama run d3:2b --ask "Is a refund being requested?" < ticket.txt
ollama run d3:2b --ask "Which team should handle this?" \
  --choice billing="Payments and refunds" \
  --choice technical="Software problems" \
  --choice shipping="Damaged or lost deliveries" < ticket.txt
Each answer took about 2.1 to 2.3 seconds of wall time once the model was warm, and 6.5 seconds for the first call with the load:
yes  100%
shipping  90%
That’s about 20 times slower than nimble’s 0.09 seconds on the RTX 5060 Ti, and the gap is CPU against GPU inference, since both timings include starting the CLI. A ticket queue doesn’t care. Notice the second answer, though. The 2B put 90% on shipping for the ticket where nimble hedged at 68%, so the 90% auto-route rule above sends this ticket to a person on nimble and puts it right on the edge on d3. Set the threshold per model, against a few dozen tickets you have already labelled.
Run the five benchmark prompts yourself
Numbers without prompts are advertising. Every speed in the next section comes from these five prompts, sent through the API with a fixed seed so runs compare, and the ollama run --verbose loop below prints the same timing line on your own machine. Copy them, run them on your own hardware, post your numbers in the comments.
- Reasoning: “A bat and ball cost $1.10 total. The bat costs $1.00 more than the ball. How much does the ball cost? Show your steps.” Right answer: $0.05. Distinguishes shallow chat from real reasoning.
- Code: “Write a Python function
merge_intervals(intervals)that merges overlapping intervals. Include type hints, a docstring, and 3 test cases including an empty input and overlapping-at-endpoints case.” Tests correctness, edge handling, type hints, and code style. - Multilingual: “Translate the following Swahili sentence to English, then explain any cultural context: ‘Haraka haraka haina baraka, lakini polepole ndiyo mwendo.'” Tests the multilingual claims.
- Factual recall + uncertainty: “List the four moons of Jupiter discovered by Galileo, in order of distance from Jupiter, with their orbital periods in days. If you are unsure of a specific number, say so explicitly.” Right answer: Io 1.77, Europa 3.55, Ganymede 7.15, Callisto 16.69. Tests both knowledge and calibrated uncertainty.
- Creative + constrained: “Write a 6-line poem about a dying server in a datacenter. Each line must have exactly 7 words. The last line must rhyme with the first.” Tests instruction following under hard constraints.
Drop this loop into a script to time every model you have pulled.
#!/usr/bin/env bash
PROMPTS=(
  'A bat and ball cost $1.10 total. The bat costs $1.00 more than the ball. How much does the ball cost? Show your steps.'
  "Write a Python function merge_intervals(intervals) that merges overlapping intervals. Include type hints, a docstring, and 3 test cases."
  "Translate the following Swahili sentence to English: 'Haraka haraka haina baraka, lakini polepole ndiyo mwendo.'"
  "List the four moons of Jupiter discovered by Galileo, in order of distance, with orbital periods in days."
  "Write a 6-line poem about a dying server. Each line exactly 7 words. Last line rhymes with first."
)
for m in gpt-oss:20b qwen3-coder:30b qwen3.5:9b gemma4:12b llama3.1:8b; do
  echo "=== $m ==="
  for p in "${PROMPTS[@]}"; do
    echo "$p" | ollama run "$m" --verbose 2>&1 | grep '^eval rate'
  done
  ollama stop "$m"
done
The --verbose flag prints a timing breakdown after each response. The line that matters is eval rate, the generation speed in tokens per second.
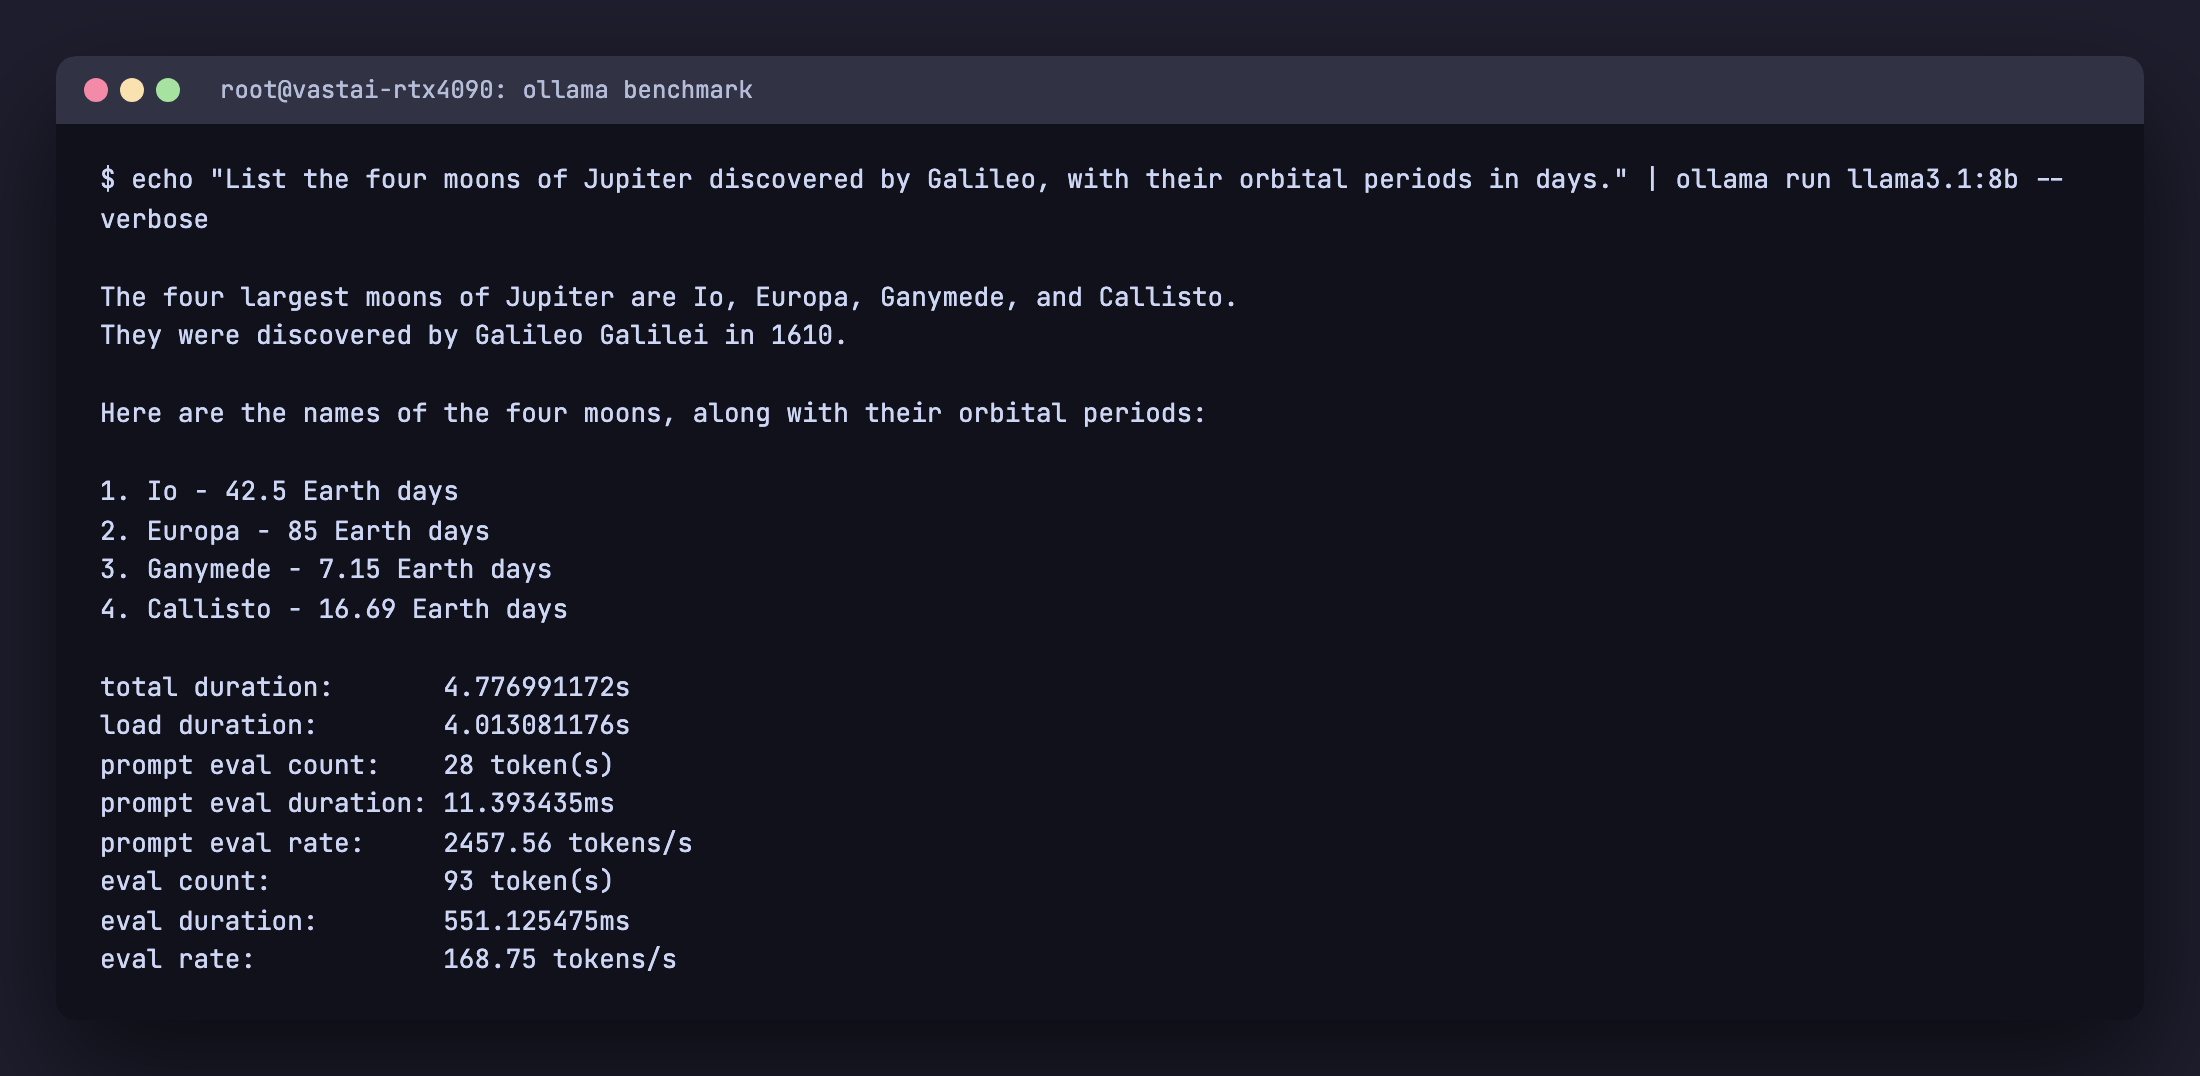
ollama run --verbose on Llama 3.1 8B answering Prompt 4. The eval rate line is the generation rate in tokens per second.Run the loop once on your own card before you trust anyone’s table, ours included, because the host CPU and driver move these numbers more than most people expect.
Benchmark results on RTX 4090, RTX 5060 Ti, and Apple M4
Each figure in these tables is the mean eval rate (tokens per second) across the five prompts above, captured through /api/generate with a fixed 256-token output, temperature 0, and seed 42 so reruns are comparable, and the ollama run --verbose loop reproduces the same line. The October tables ran on Ollama 0.40.6 at each card’s default context (32K on the 24 GB card, 4K on the 16 GB card) and again at num_ctx 65536, because the Ollama context-length docs say agents and coding tools need at least 64000 tokens. We rented the GPUs on vast.ai. The RTX 4090 sat in a Ryzen 7 9700X host and the RTX 5060 Ti in a Ryzen 5 5500 host, and the CPU matters more than you’d expect, as the Bolt row shows.
October run on the RTX 4090
The new models plus four from September as a control. The control rows landed within 2 percent of their September numbers except gemma4:26b, which gained 6 percent, so the two runs compare fairly.
| Model | Disk | Type | tok/s at 32K | tok/s at 64K | September |
|---|---|---|---|---|---|
gemma4:26b | 18 GB | MoE ~4B active, vision, draft decoding | 311.7 | 310.2 | 294.4 |
ornith-1.5:35b | 22 GB | MoE, 3B active, vision, thinking | 215.2 | 215.5 | new |
gpt-oss:20b | 13 GB | MoE, ~3B active | 194.6 | 194.6 | 192.0 |
bonsai-2 | 3.2 GB | 9B ternary (q2_0), vision | 189.0 | 189.5 | new |
ornith-1.5:9b | 6.6 GB | dense 9B, vision, thinking | 141.1 | 141.0 | new |
qwen3.5:9b | 6.6 GB | dense, multimodal | 127.9 | 128.1 | 127.5 |
qwen3.8:27b | 17 GB | dense 27B, vision, draft decoding | 120.3 | 120.1 | 119.1 |
nemotron-3.5-bolt | 25 GB | 74B MoE, 9B active, drafter, part in RAM | 114.4 | 158.4 | new |
bonsai-2:27b | 8.3 GB | 27B ternary (q2_0), vision | 84.2 | 84.2 | new |
devstral-small-2 | 15 GB | dense 24B coder, vision | 60.8 | not run | new |
Every model we ran at 64K, Bolt aside, reported 100% GPU in ollama ps at both contexts and kept the same speed, so on a 24 GB card the 64K setting a coding agent wants costs nothing for these picks (devstral-small-2 only ran at 32K, where it loaded 19.7 GB fully on the GPU). ornith-1.5:35b stands out because it’s a 35B-A3B mixture-of-experts, so only about 3B parameters work per token and a 22 GB model generates at 215 tok/s, ahead of gpt-oss:20b. The ternary bonsai-2 models are the other standout, because a 27B that downloads as 8.3 GB and holds 84 tok/s puts a 27B-class model with vision on a 12 GB card.
Bolt needs its own explanation. At 24 GB it doesn’t fit the card whole, so Ollama 0.40’s llama-server backend fits it automatically. The server log on our first host showed a 17,561 MiB model buffer on the GPU (about 18.4 GB), around 3.4 GB of expert tensors left in system RAM, and a 0.9 GB draft model running speculative decoding on the GPU. The per-prompt rates swung from 83 to 193 tok/s, which is what a drafter with a variable acceptance rate looks like, and the 64K run happened to average higher than the 32K one. Read it as roughly 100 to 160 tok/s for a 74B model on one consumer card. Treat any rented-GPU number with care, though: on our first host, a busy shared EPYC server with a different RTX 4090, every model ran at half these speeds or less, and Bolt fell to 38 tok/s.
16 GB tier on the RTX 5060 Ti
The 16 GB card is where the loaded size decides everything, so this table shows it next to the speed. Ollama’s default here is a 4K context, and the second pair of columns is the same model forced to 64K.
| Model | tok/s at 4K | Loaded at 4K | tok/s at 64K | Loaded at 64K |
|---|---|---|---|---|
bonsai-2 | 117.1 | 2.8 GB | 117.9 | 5.1 GB |
gpt-oss:20b | 94.5 | 12.7 GB | 94.8 | 12.8 GB |
llama3.1:8b | 83.2 | 5.3 GB | 82.9 | 13.4 GB |
ornith-1.5:9b | 71.6 | 5.6 GB | 71.7 | 7.7 GB |
qwen3.5:9b | 67.7 | 5.6 GB | 67.7 | 7.7 GB |
gemma4:12b-it-qat | 53.0 | 7.7 GB | 52.8 | 8.1 GB |
bonsai-2:27b | 44.2 | 8.1 GB | 44.2 | 12.2 GB |
devstral-small-2 | 22.5 | 15.0 GB, 97% GPU | 5.5 | 19.6 GB, 73% GPU |
qwen3.8:27b | 15.2 | 18.3 GB, 73% GPU | 10.1 | 20.7 GB, 53% GPU |
Compare llama3.1:8b with gpt-oss:20b in the 64K column. The older 8B keeps a full-size KV cache, so it grows from 5.3 to 13.4 GB, while the 20B with sliding-window attention barely moves. Newer architectures (gpt-oss, the Qwen 3.5 family, Gemma 4) are what make long context practical on a 16 GB card. The bottom two rows are the trap. Neither fits even at 4K, and devstral-small-2 drops from 22.5 to 5.5 tok/s once the 64K context pushes another chunk of it off the card.
Apple M4 MacBook Pro, 16 GB
Same prompts on a 16 GB M4 MacBook Pro running a browser and an editor, which is how most people use one. The runner column is what the Ollama server log reported.
| Model | Runner | tok/s | RTX 4090 for comparison |
|---|---|---|---|
gemma4:e4b-it-qat | llama.cpp (Metal) | 29.8 | not run |
bonsai-2 | llama.cpp (Metal) | 26.8 | 189.0 |
qwen3.5:9b | MLX | 24.2 | 127.9 |
ornith-1.5:9b | llama.cpp (Metal) | 15.3 | 141.1 |
Twenty-five tokens per second reads faster than you can follow it, so a 16 GB Mac is a perfectly usable chat box for 4B to 9B models. It isn’t a coding-agent box, where a task generates thousands of tokens and a 5x to 9x speed gap against the RTX 4090 turns a one-minute task into several.
September run: 31 models on the RTX 4090
The full catalogue run from September stays below for the models we didn’t repeat. It used Ollama 0.34.4 on a different RTX 4090 host. Models under 26B, plus qwen3-coder:30b (21.7 GB loaded, still fully on the GPU), ran at the 32K default. The rest of the 26B-and-up group ran at num_ctx 8192 so they stayed on the GPU. The last column is the same model on the same rig in July.
| Model | Disk | Type | Mean tok/s | July tok/s |
|---|---|---|---|---|
llama3.2:1b | 1.3 GB | dense 1B | 482.7 | 422.7 |
deepseek-r1:1.5b | 1.1 GB | reasoning (Qwen distill) | 445.8 | 396.8 |
lfm2.5 | 5.2 GB | hybrid 8B, on-device | 401.7 | new |
qwen3.5:0.8b | 1.0 GB | multimodal | 339.3 | 360.7 |
llama3.2:3b | 2.0 GB | dense 3B | 312.8 | 284.0 |
gemma4:26b | 18 GB | MoE ~4B active, vision, draft decoding | 294.4 | 157.0 |
phi4-mini | 2.5 GB | dense 3.8B | 262.5 | 235.2 |
qwen3.6:35b | 22 GB | MoE, vision, draft decoding | 247.5 | new |
qwen3.5:2b | 2.7 GB | multimodal | 235.7 | new |
qwen3-coder:30b | 18 GB | MoE, ~3B active | 224.7 | 218.9 |
gpt-oss:20b | 13 GB | MoE, ~3B active | 192.0 | 175.1 |
qwen3.5:4b | 3.4 GB | multimodal | 183.3 | 187.8 |
mistral:7b | 4.4 GB | dense 7B | 177.0 | 176.2 |
qwen2.5-coder:7b | 4.7 GB | dense coder | 174.4 | 162.0 |
qwen2.5:7b | 4.7 GB | dense 7B | 174.1 | 160.7 |
llama3.1:8b | 4.9 GB | dense 8B | 164.7 | 156.1 |
qwen3-vl:8b | 6.1 GB | vision | 155.3 | 143.7 |
qwen3:8b | 5.2 GB | dense 8B | 152.9 | 151.0 |
deepseek-r1:8b | 5.2 GB | reasoning (Qwen3 distill) | 152.5 | 144.1 |
granite4.2:8b | 5.3 GB | dense 8B | 142.8 | new |
qwen3.5:9b | 6.6 GB | dense, multimodal | 127.5 | 128.8 |
qwen3.8:27b | 17 GB | dense 27B, vision, draft decoding | 119.1 | new |
qwen3.6:27b | 17 GB | dense 27B, vision, draft decoding | 115.4 | 48.0 |
gemma3:12b | 8.1 GB | dense 12B | 99.3 | 91.3 |
gemma4:12b | 7.6 GB | dense 11.9B, vision | 97.1 | 88.9 |
muse-glimmer:30b | 18 GB | 30B agentic, vision | 50.9 | new |
gemma3:27b | 17 GB | dense 27B | 49.0 | 46.9 |
qwen3.5:27b | 17 GB | dense 27B, vision | 48.1 | 48.1 |
granite4.2:30b | 17 GB | dense 30B | 47.9 | new |
deepseek-r1:32b | 19 GB | reasoning (Qwen distill) | 43.9 | 42.9 |
nemotron-3.5-lightning | 25 GB | MoE, 3B active, 14% on CPU | 8.6 | new |
All 31 of those models were pulled onto one instance for the September run.

ollama list on the RTX 4090 test instance after pulling all 31 benchmarked models.Most of the older non-Qwen models gained 5 to 14 percent over July (llama3.2:1b went from 423 to 483 tok/s and gpt-oss:20b from 175 to 192), while the small qwen3.5 sizes were flat or a few percent slower. The big jumps come from somewhere else. qwen3.6:27b went from 48 to 115 tok/s while qwen3.5:27b, the same size class and quantization, stayed flat at 48. gemma4:26b nearly doubled to 294. Both fast ones carry a draft_num_predict parameter in their Modelfile, and so do qwen3.8:27b and qwen3.6:35b. That parameter tells Ollama to run speculative decoding: several tokens are proposed cheaply and the full model verifies them in a single pass. The Parameters block at the end of ollama show gives it away.
ollama show qwen3.6:27bThe model asks for three draft tokens per step, and it sets repeat_penalty to 1, which the Ollama release notes say speeds up speculative decoding.
  Parameters
    repeat_penalty       1
    temperature          1
    top_k                20
    top_p                0.95
    draft_num_predict    3
    min_p                0
    presence_penalty     0
To prove the parameter is doing the work, we reran the Jupiter prompt with "draft_num_predict": 0 in the request options. qwen3.6:27b dropped from 122.6 to 48.9 tok/s, which is right back to the July figure, and gemma4:26b fell from 289.6 to 155.9. Speculative decoding does not change output quality, because the full model still verifies every token. Leave it on. If a model without the parameter feels slow next to one that has it, this is why, and it is a better reason to move from qwen3.5:27b to qwen3.8:27b than any benchmark leaderboard.
Two rows need context. qwen3.6:35b is a mixture-of-experts that also uses draft decoding, so a 22 GB model generates at 247 tok/s, faster than any dense 7B. nemotron-3.5-lightning is the opposite lesson. At 25 GB it cannot fit a 24 GB card whole, ollama ps showed a 14%/86% CPU/GPU split, and generation collapsed to 8.6 tok/s even though only 3B parameters are active per token. A model that spills to system RAM is slow no matter how sparse it is. That was Ollama 0.34.4, and we haven’t rerun Lightning on 0.40.6, so treat 8.6 tok/s as a September number. The dense 27B to 32B class (muse-glimmer, gemma3:27b, granite4.2:30b, deepseek-r1:32b) lands between 44 and 51 tok/s, and those ran at an 8K context because a dense 32B at Q4 leaves little room for a 32K cache on a 24 GB card. For how the same card compares across runtimes, the Ollama vs vLLM vs llama.cpp benchmark runs identical models through all three.
Build custom models with Modelfile recipes
To see how an existing model is configured, run ollama show --modelfile <name>. The output reveals the system prompt, template, default parameters, license, and the underlying GGUF blob path. This is the right starting point when you want to build a customized variant.
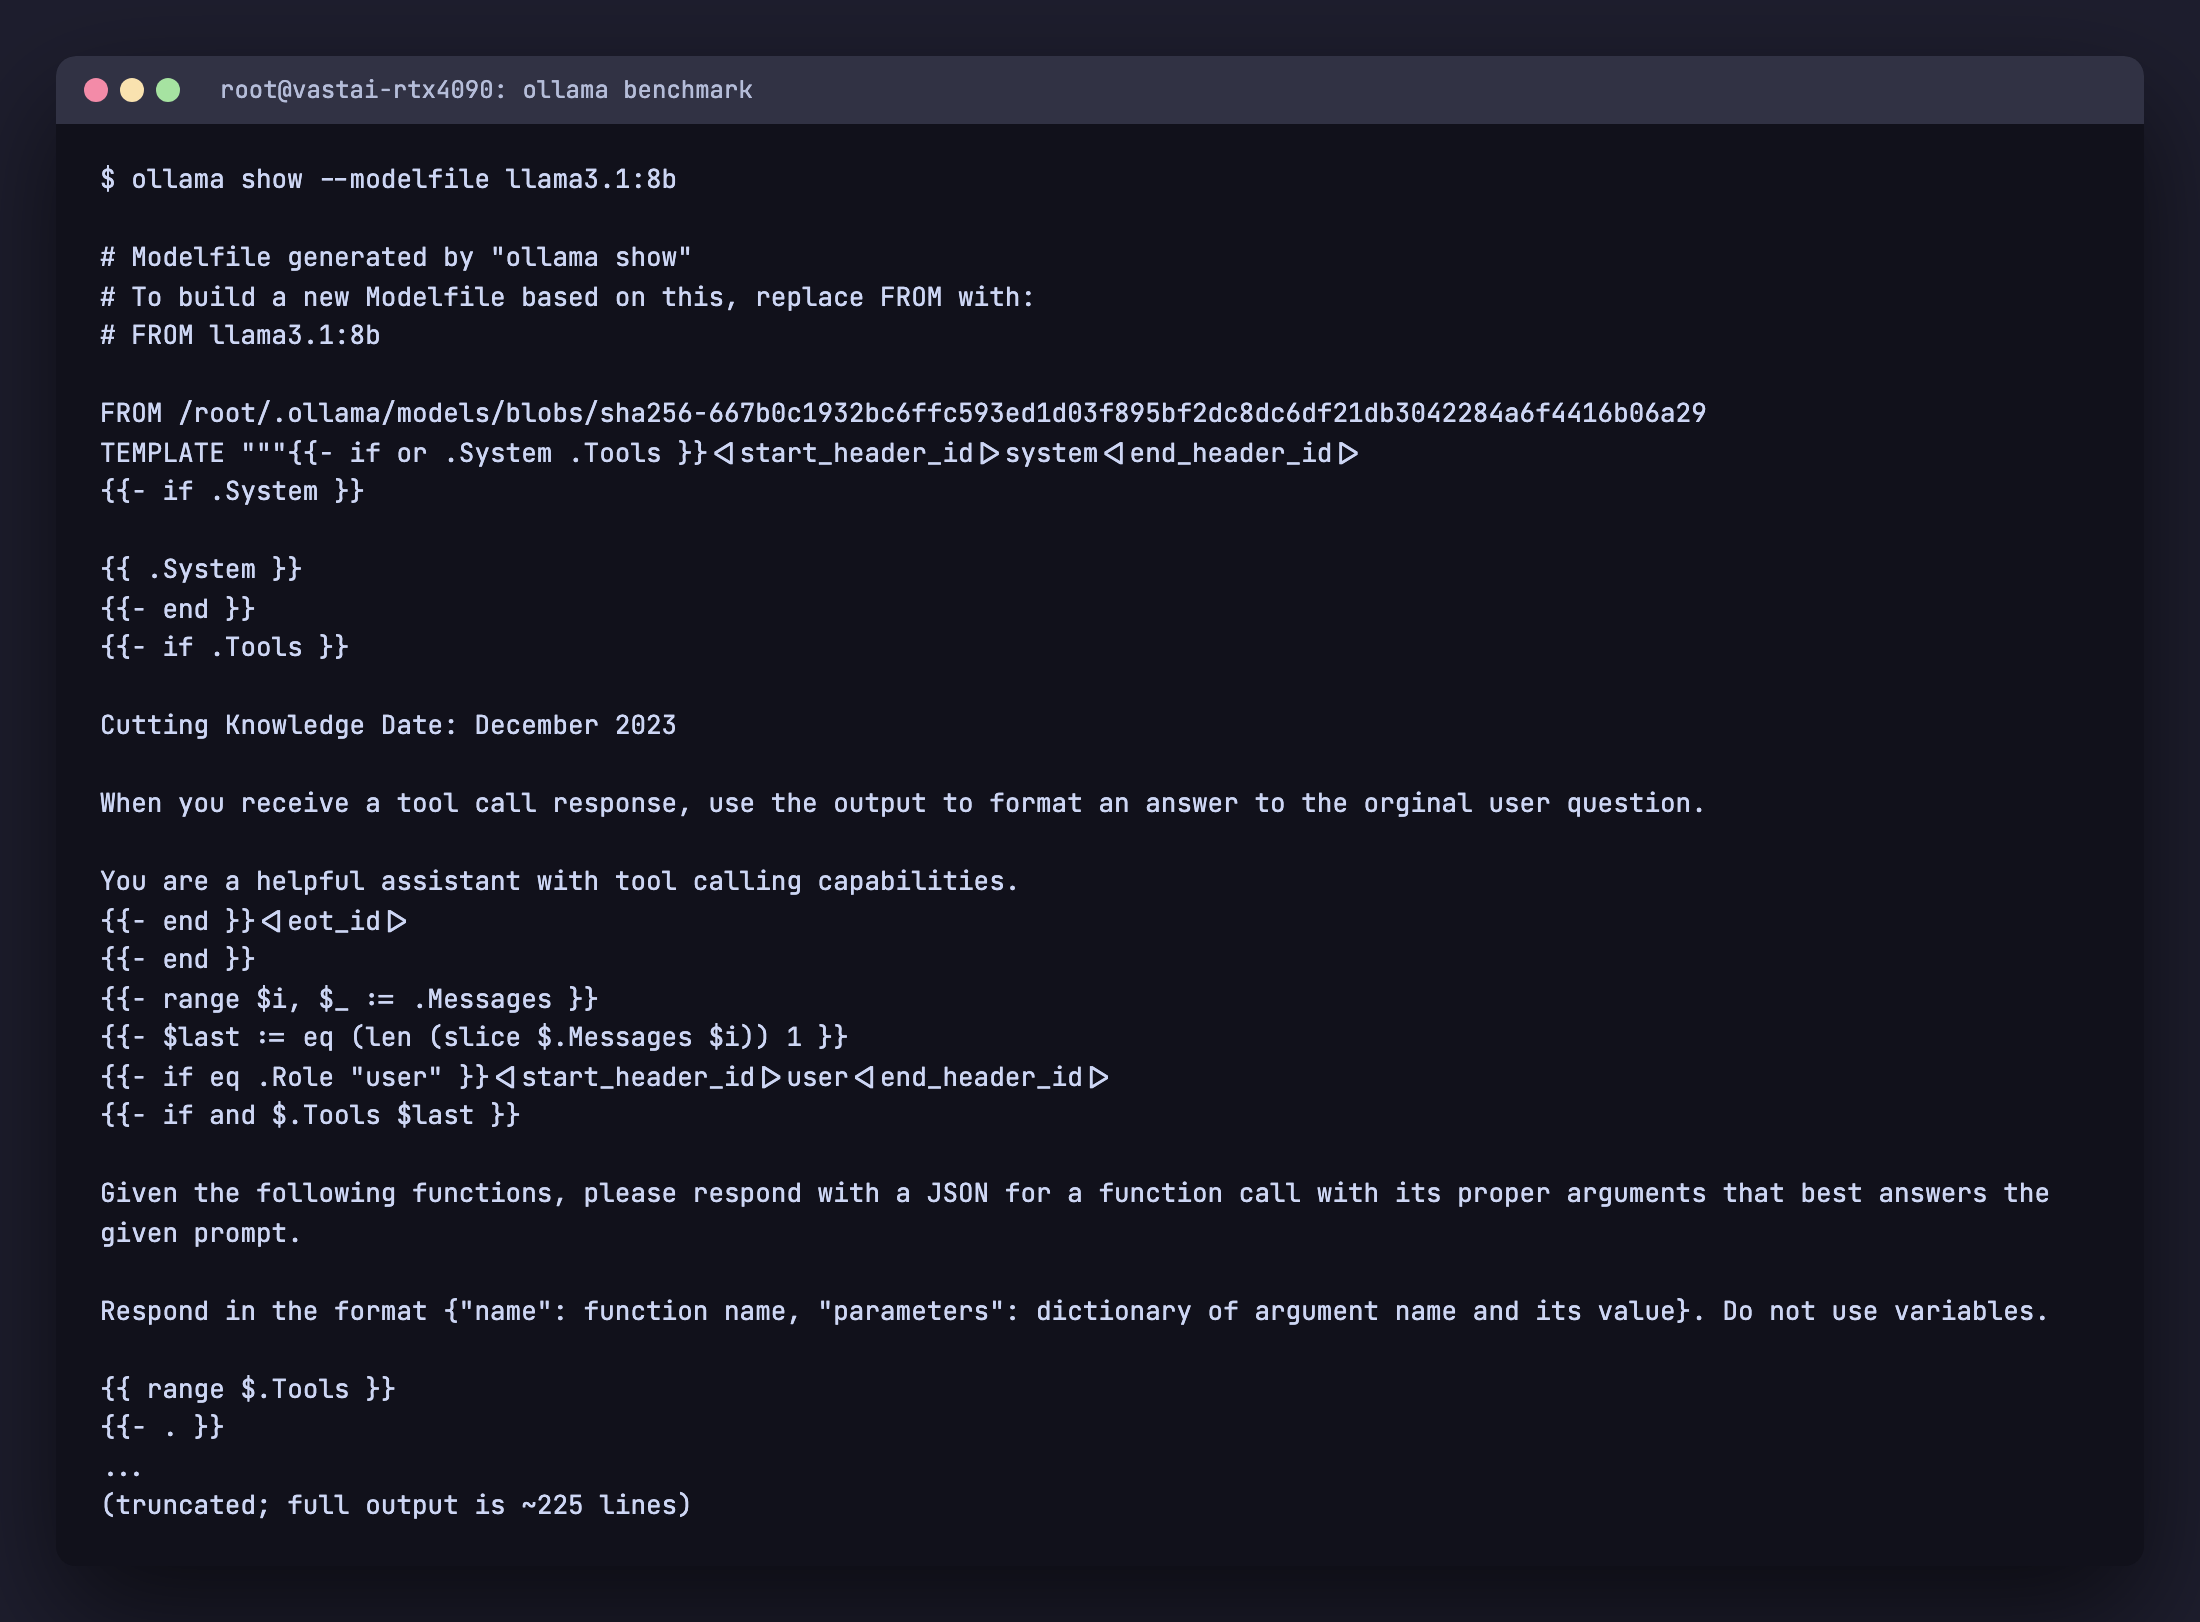
ollama show --modelfile llama3.1:8b. Use the output as a starting template for your own Modelfile.A Modelfile lets you create a customized variant of a base model. Four recipes cover most production needs.
Coding assistant with deterministic output
Low temperature for predictable code, a wide context for whole-file edits, and a system prompt that forces a code-first style. Save it as Modelfile.coder.
FROM qwen2.5-coder:7b

PARAMETER temperature 0.1
PARAMETER top_p 0.9
PARAMETER repeat_penalty 1.0
PARAMETER num_ctx 16384

SYSTEM """You are a senior software engineer. Always respond with code first, comments second.
Use type hints in Python, JSDoc in JavaScript, and prefer the standard library where possible.
When asked to fix a bug, output a unified diff."""
Build the variant and run it.
ollama create coder-strict -f Modelfile.coder
ollama run coder-strict "fix the off-by-one in this for loop: for i in range(len(arr)+1): print(arr[i])"
The diff-first system prompt is the part that pays off, because a reviewer can apply the output with git apply instead of reading prose.
RAG retriever (deterministic, short answers)
Temperature zero so retrieval answers stay grounded, plus a system prompt that refuses to answer outside the provided context and cites its source.
FROM llama3.1:8b

PARAMETER temperature 0.0
PARAMETER top_p 1.0
PARAMETER repeat_penalty 1.0
PARAMETER num_ctx 8192
PARAMETER stop "<end>"

SYSTEM """You answer ONLY using the context provided.
If the context does not contain the answer, reply: "Not in the provided context."
Cite the source paragraph index in square brackets after each claim."""
Build it with ollama create the same way as the coder variant, and keep num_ctx at 8192 unless your retrieved chunks are long.
JSON-only output for tool routing
A router that must emit a single JSON object and nothing else. Mistral Small’s native function calling makes it reliable at this.
FROM mistral-small:24b

PARAMETER temperature 0.0
PARAMETER num_ctx 8192

SYSTEM """You are a function-call router. Always respond with a single JSON object and nothing else.
Schema: {"tool": string, "args": object}.
Available tools: search_docs, run_sql, send_email, file_read."""
Pair this with Ollama’s structured outputs feature (the format field on /api/chat) and you get hard JSON schema enforcement instead of relying on the prompt alone.
Reproducible eval (seeded, deterministic)
A fixed seed plus greedy decoding so the same prompt returns the same output on every run, which is what you want when comparing models.
FROM llama3.1:8b

PARAMETER seed 42
PARAMETER temperature 0.0
PARAMETER top_p 1.0
PARAMETER top_k 1
PARAMETER repeat_penalty 1.0

SYSTEM "Answer concisely. No preamble."
Use this variant when you compare model quality across benchmark prompts. Without seed, two runs of the same prompt will not match exactly even at temperature 0.0.
Tune the parameters that matter
| Parameter | Default | What it controls | When to change |
|---|---|---|---|
num_ctx | 4K/32K/256K by VRAM | Context window in tokens (capped at the model max) | Lower it to save VRAM, or raise toward the model max for long docs, RAG, code review. Server-wide via OLLAMA_CONTEXT_LENGTH |
temperature | 0.8 | Randomness | Drop to 0.0 to 0.2 for code, factual answers, JSON output. Up to 1.0+ for creative writing |
top_p | 0.9 | Nucleus sampling cutoff | Leave at 0.9 unless you know what you are doing. 1.0 disables it |
top_k | 40 | Top-k sampling | 1 forces greedy decoding (fully deterministic with seed). 0 disables it |
repeat_penalty | 1.0 (off) unless the model sets one | Penalize token repetition | Raise to 1.1 or 1.2 only if an older model loops. Higher values slow speculative decoding |
draft_num_predict | set by the model | Tokens drafted ahead per step for speculative decoding | Leave the model default. Set 0 to turn drafting off when you need a like-for-like speed comparison |
seed | random | Deterministic sampling | Set any integer for reproducible outputs across runs |
num_predict | -1 (unlimited) | Max tokens to generate | Cap to control latency and cost; -2 means fill the context |
num_gpu | auto | Layers offloaded to GPU | Set explicitly to force CPU mode (0) or full GPU (-1, all layers) |
num_thread | auto | CPU threads | Set to physical core count for CPU inference. Hyperthreading rarely helps |
keep_alive | 5m | How long to keep model loaded | Set -1 for permanent residency, 0 to unload immediately |
Stop thinking models from overthinking
Thinking models write a reasoning block before the answer, and on an easy prompt that block is most of the cost. We timed it on the 16 GB M4, where qwen3.5:4b spent 1,457 tokens and 62 seconds on the bat-and-ball question with thinking on, and 426 tokens and 17 seconds with it off, and both runs got $0.05 right. Bigger thinking models behave the same way, so turn thinking down or off for requests that don’t need it. Start by checking which levels the model accepts:
ollama show qwen3.5:4bThe Capabilities block lists the levels and the default. This model only takes on or off, while qwen3.8:27b lists false, low, medium, xhigh with medium as its default.
    thinking
        levels     false, true
        default    true
Pick the control that matches how you call the model:
ollama run qwen3.8:27b --think=falseskips the reasoning block--think=lowkeeps a short one on models that list levels--hidethinkingstill reasons but prints only the answer"think": falseor"think": "low"in an/api/chatrequest
For an agent loop, set it per request rather than globally. Tool routing, extraction, and short answers rarely gain anything from reasoning, while a multi-step refactor or a math problem does, and paying 3.4 times the tokens on every call is how a local agent ends up feeling slow on a fast card.
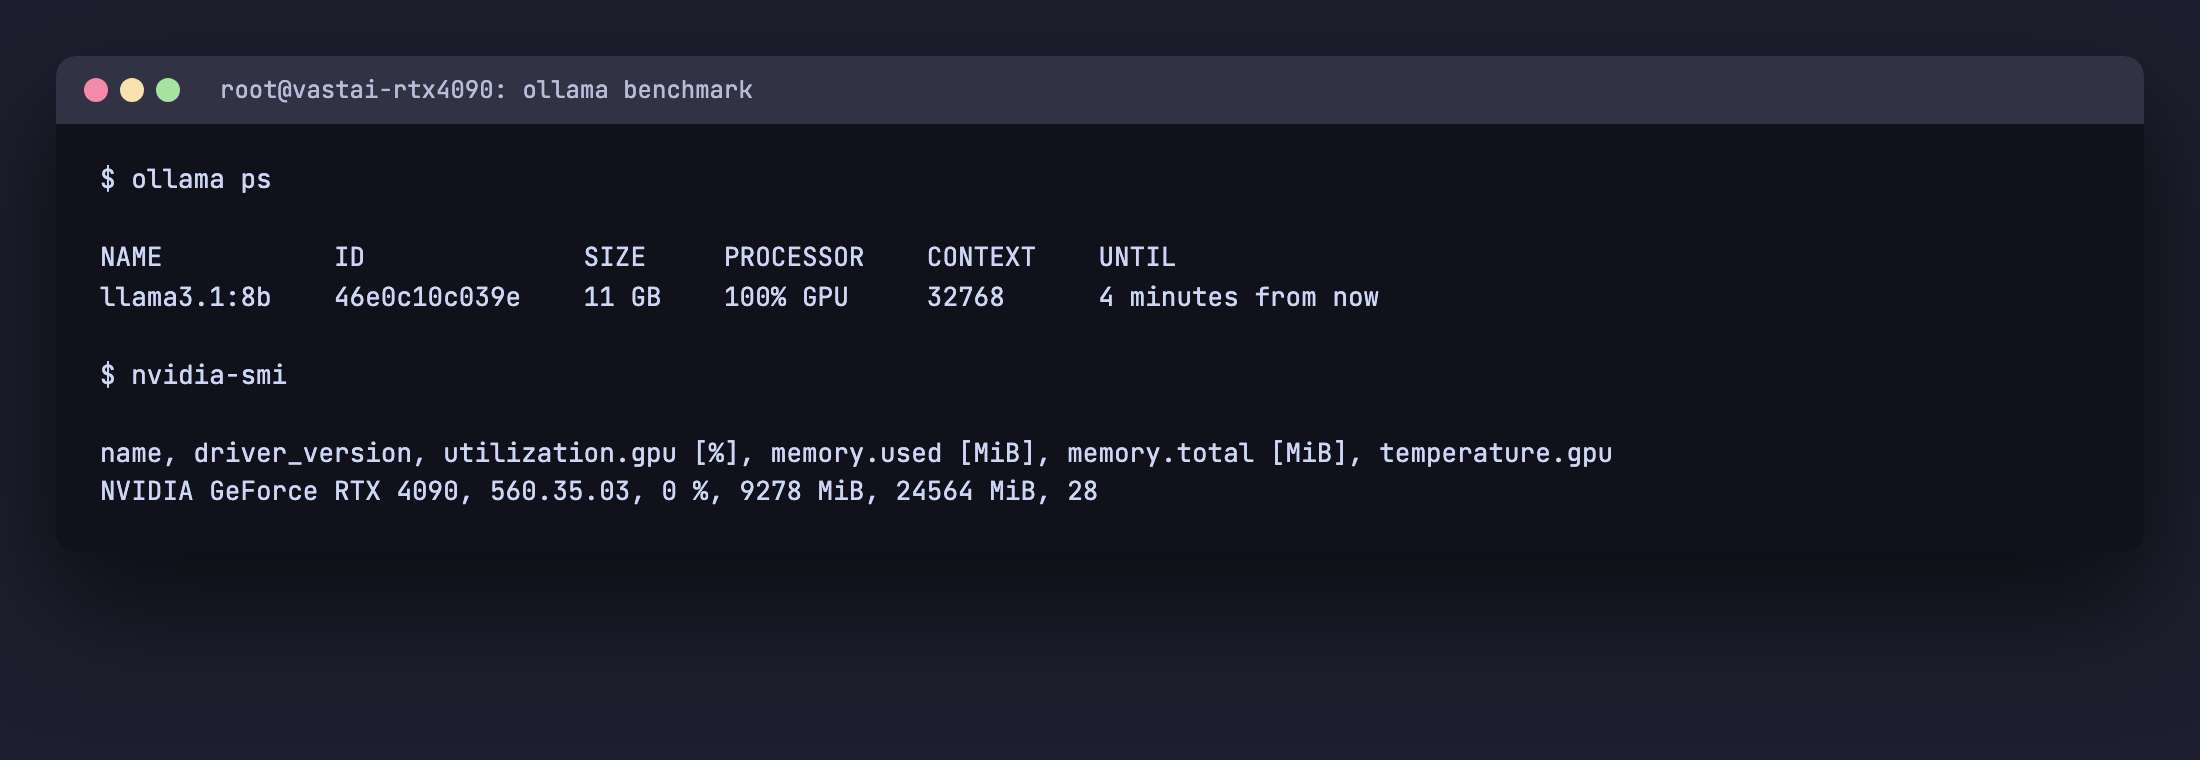
ollama ps confirms the model is on GPU at the 24-48 GB tier’s 32K default context. nvidia-smi shows about 9 GB (9,278 MiB) in use for Llama 3.1 8B, in line with the GQA KV math above.That screenshot is the check to run after any of the changes above. ollama ps should still read 100% GPU once the new context or parallel setting is live, and if it doesn’t, the last change cost you more than it bought.
Avoid these model selection mistakes
- The default
num_ctxis now VRAM-tiered, not a flat 2,048. Current Ollama loads 4K under 24 GB VRAM, 32K from 24 to 48 GB, and 256K at 48 GB or more (capped at the model’s trained max). On a bigger card that convenience sizes the KV cache large, so cap it withOLLAMA_CONTEXT_LENGTH(server) ornum_ctx(per request) when VRAM is tight, and only push toward the model’s full max when you genuinely need long context. - Tags shift over time. The
:latesttag points to whatever Ollama considers default for that model family today. Pin to explicit sizes (:7b,:14b) and quantizations (-instruct-q4_K_M) for reproducibility. - “R1 8B is not real R1.” The 1.5B through 70B DeepSeek R1 tags are distillations. Only
deepseek-r1:671bis the genuine model. - KV cache silently OOMs at long context, but it is the dense 30B-plus models that bite, not 8B. An 8B with grouped-query attention only reaches about 10 GB at 32K, while a dense 32B is already about 20 GB of weights at Q4, so a large cache on top pushes it off a 24 GB card. Quantize the cache with
OLLAMA_KV_CACHE_TYPE=q8_0(flash attention is already automatic on supported GPUs), or trimnum_ctx. ollama pscan under-report a model that spills. Withnemotron-3.5-boltloaded on a 24 GB card,ollama psshowed 3.0 GB and 97% GPU, while the llama-server log showed a 17,561 MiB model buffer on the card and about 3.4 GB of expert tensors in system RAM. The smallnemotron-3.5-bolt:e4bdoes it too with no GPU at all: 2.9 GB inollama psagainst 8.5 GiB resident for itsllama-serverprocess. Checknvidia-smi,free -mor the server log before trusting the SIZE and PROCESSOR columns for the Bolt family or any mixture-of-experts model bigger than your card.- Benchmark the host, not only the card. Our first RTX 4090 sat in a busy shared EPYC server, and every model ran at half the speed or less of a second 4090 in a quiet Ryzen 7 9700X box:
ornith-1.5:9b67 against 141 tok/s, Bolt 38 against 114. Run one control model you already have a number for before trusting any rented GPU. keep_alive=0on every request kills throughput. Each call reloads the model from disk. SetOLLAMA_KEEP_ALIVE=24hin the systemd override for the service host, or pass"keep_alive": -1on the API request.- One model serves one request at a time by default.
OLLAMA_NUM_PARALLELdefaults to 1, so set it to 4 for multi-user load, and remember the memory it needs scales withOLLAMA_NUM_PARALLELtimes the context length. - Vision models on Ollama need image input through the API or
ollama run model "describe this" /path/to/image.png, not pasted into a chat. Make sure the file path resolves where Ollama runs (different user, different working directory).
Common questions about Ollama models
Which Ollama model is best for coding?
qwen3-coder:30b is the strongest coding model most people can run locally in 2026. It is a 30B-A3B mixture-of-experts model (about 3B active per token) that fits a 24 GB GPU at Q4 and handles agentic, repo-scale work with a 256K context. If you cannot run it, qwen2.5-coder is the next rung: :14b on a 16 GB GPU, :7b on 8 GB (still beating CodeLlama and DeepSeek-Coder for editor-side completion), and :32b (near GPT-4o on Aider) if you have the headroom. The newer dense option is qwen3.8:27b, tuned for agentic coding with vision included, and at 120 tok/s on a 4090 it is fast enough for interactive use. Two coding models this page didn’t cover before are worth a trial on a 24 GB card: devstral-small-2 (Mistral’s 24B coding agent, 61 tok/s, Apache 2.0) and glm-4.7-flash (MIT). On a 16 GB card, gpt-oss:20b is the pick, because it keeps a 64K context on the GPU at 95 tok/s. Without local hardware, the cloud tags such as glm-5.3:cloud and kimi-k3:cloud run frontier-size coding models through the same CLI.
How much RAM do I need for Llama 3.3 70B?
At Q4_K_M (~43 GB on disk), Llama 3.3 70B needs roughly 48 GB of unified memory or VRAM with a small context window, 56 GB with a 32K context. On a single 24 GB GPU it will not fit even at Q3_K_M without partial CPU offload, and the offloaded version drops to single-digit tokens per second. Either pair two RTX 3090s or use Apple Silicon with 64 GB unified memory. The size-by-size breakdown lives in how much VRAM you need to run an LLM.
Can I run Ollama on Apple Silicon?
Yes. M1 through M4 chips all work, with unified memory acting as VRAM, and since 0.40 Ollama runs supported models on Apple’s MLX runtime and the rest on llama.cpp with Metal. On a 16 GB M4 MacBook Pro we measured 30 tok/s for gemma4:e4b-it-qat, 27 for bonsai-2, 24 for qwen3.5:9b on MLX, and 15 for ornith-1.5:9b, between a fifth and a ninth of what the RTX 4090 did on the same models. Metal reported 11.8 GiB usable on that machine, so stay under roughly 9 GB of model to leave room for the context and your other apps. Bigger Macs scale the same way, and 64 GB holds a 70B at Q4_K_M with a small context.
Mistral vs Llama vs Qwen, which is best?
Different niches. Llama 3.1 8B is the safe English-first general default. Qwen 2.5 7B beats it on multilingual and on Asian languages and matches it on English reasoning. Mistral Nemo 12B is the right pick when you have ~12 GB VRAM and want better-than-8B quality. Mistral Small 24B owns the agentic and JSON output niche thanks to native function calling. There is no single “best” answer. Pick by use case.
What is the smallest Ollama model that is actually useful?
llama3.2:1b and qwen2.5:1.5b are both genuinely useful at their size. They are good enough for tool routing, classification, simple summarization, and structured extraction, especially with a tight system prompt. Below 1B (gemma3:270m, qwen2.5:0.5b) the models are real but quality drops sharply on anything but the simplest classification.
DeepSeek R1 vs Claude or GPT-4, when to pick local?
Pick local R1 distillations when privacy, latency, or per-call cost matters more than top-end quality, or when you specifically want chain-of-thought reasoning to stay on your hardware. The 14B and 32B distillations are strong on math and step-by-step problem solving but they are not a one-to-one replacement for Claude or GPT-4 on creative writing, long-form synthesis, or complex tool use. Run an honest eval on your real prompts before committing.
How do I update an installed Ollama model?
Run ollama pull <model> again. Ollama only downloads new layers, so the update is incremental. Confirm with ollama list that the modified date refreshed. To track which version of Ollama itself you have, run ollama --version.
Why does my model run slow on CPU?
CPU inference is bandwidth-bound, not compute-bound. A 7B model at Q4_K_M reads ~4.5 GB of weights for every token, so total throughput is your memory bandwidth divided by model size. A DDR5-5200 dual-channel desktop reads ~80 GB/s and gets ~15 tok/s on a 7B. A server with 8-channel DDR5 (~400 GB/s) does ~80 tok/s. Adding more CPU cores past your core count does not help. Quantize harder (Q3_K_M) or pick a smaller model. To match a card to the model size, see how much VRAM to run an LLM.
Can I run two Ollama models at the same time?
Yes. OLLAMA_MAX_LOADED_MODELS defaults to 3 per GPU (3 on CPU), so several models stay loaded as long as they fit in memory, and Ollama unloads idle ones when a new load needs the room. Raise OLLAMA_NUM_PARALLEL from its default of 1 if requests queue on the same model. Inspect what is loaded with ollama ps. The column PROCESSOR tells you whether each model is on GPU, CPU, or split.
Should I use the GGUF tag or the default?
Stick with the default unless you have a reason. Ollama defaults are curated GGUF files at sensible quantizations. Pull custom GGUFs from Hugging Face only when you need a specific quantization, fine-tune, or merge that is not in the official library. Use ollama create <name> -f Modelfile with FROM ./model.gguf to import.
Run models bigger than your GPU: Ollama Cloud
Ollama Cloud runs models that are far too large for local VRAM through the same CLI and API you already use. Cloud-only models carry a plain :cloud tag (kimi-k3:cloud, mistral-large-4:cloud, muse-spark-open:cloud), while families that also ship local weights use a size-prefixed tag such as gpt-oss:120b-cloud. October added four cloud-only heavyweights: Mistral Large 4 (about 1T total, 52B active), Muse Spark Open (816B total, 42B active, 1M context), MiniMax M3.1 Flash, and Reflection’s Beam. Authenticate the machine once, then run a cloud model exactly like a local one.
ollama signin
ollama run kimi-k3:cloud
ollama run gpt-oss:120b-cloud
Billing is per token against a monthly credit allowance, and the plan mostly decides how many requests run at once. The plans on the Ollama pricing page in October 2026:
- Free plan with pay-as-you-go starter credits and 1 concurrent request
- Pro at $20 a month ($200 a year) with $60 of credits and 3 concurrent requests
- Max at $100 a month with $300 of credits and 10 concurrent requests
- Team at $500 a month with $1,000 of shared credits and unlimited users
Credits drain at each model’s per-million-token rate, so the table below is what actually decides your bill.
| Cloud model | Input | Cached input | Output |
|---|---|---|---|
nemotron-3-super | $0.015 | $0.015 | $0.60 |
gpt-oss:20b | $0.07 | $0.035 | $0.30 |
gemma4 | $0.14 | $0.05 | $0.40 |
gpt-oss:120b | $0.15 | $0.014 | $0.60 |
glm-5.3-flash | $0.15 | $0.03 | $0.50 |
minimax-m3.1-flash | $0.15 | $0.015 | $0.60 |
clef (decision model) | $0.24 | n/a | n/a |
deepseek-v4.1-flash | $0.30 | $0.006 | $1.20 |
minimax-m3 | $0.60 | $0.12 | $2.40 |
mistral-large-4 | $0.68 | $0.07 | $2.09 |
muse-spark-open | $1.25 | $0.15 | $4.25 |
deepseek-v4-pro | $1.32 | $0.044 | $3.96 |
glm-5.3 | $1.40 | $0.26 | $4.40 |
kimi-k3 | $3.00 | $0.30 | $15.00 |
Both DeepSeek models (deepseek-v4-pro and deepseek-v4.1-flash) bill at half those rates off-peak, which Ollama defines as outside 12:00 to 18:00 UTC on weekdays and all weekend. The workflow is the real point. Prototype against a frontier model in the cloud, then switch the tag to a local model that fits your card, with no code change. Cloud tags also work behind Open WebUI, so a team can share one chat frontend where some models run on your GPU and the biggest ones bill per token.