Exa has been building search since 2021, when it launched as Metaphor (it renamed to Exa in January 2024). Its API searches its own index and returns page text with results. Exa isn't open source, so there's no self-hosted option. It's also built search-first, so teams that need to crawl whole sites, interact with pages, or pull structured data from them often pair it with a scraping tool. Those gaps are the main reasons teams look for an Exa alternative, and the four tools below fill them in different ways.
TL;DR: Best Exa alternatives
| Tool | Best for | Search price per 1,000 | Free tier | Page content in search results | Scrape and crawl sites |
|---|---|---|---|---|---|
| Firecrawl | Agents that need search, scraping, and page interaction in one API | About $2 (Standard plan) | 1,000 credits/month | Full page markdown with scrapeOptions | Yes |
| Perplexity | Cited answers, or raw ranked results | $5 (Search API) | None (prepaid credits) | Extracted page text in each result | No |
| Linkup | Sourced facts and company research | $5 standard, $50 deep | $20 in credits/month (professional email) | Snippets; full pages through its Fetch endpoint | Single URLs only |
| Brave | Independent index, high request volume | $5 | No free plan; $5 in credits/month | Up to 5 snippets per result; LLM Context endpoint | No |
Quick answer:
- Choose Firecrawl if your agent needs live search results with full page content in one call (add
scrapeOptions), plus scraping, crawling, page interaction, and Firecrawl Alexandria's data providers and indexes from the same API. - Choose Perplexity if you want cited answers generated for you, or ranked results with page text from its Search API.
- Choose Linkup if you need sourced facts and company research, with structured output.
- Choose Brave Search API if you want an independent index that doesn't depend on Google or Bing.
- Stay with Exa if semantic discovery (Find Similar, Websets, and its people and company indexes) is the core of your workflow.
Why users look for Exa alternatives
Teams may explore alternatives when they need a fully open-source, self-hosted option, an all-in-one web data stack (search + scrape + extraction), predictable flat pricing, or parallel processing at scale.
Because Exa answers from its own index, pages published since its last crawl may not show up yet, and sites that block crawlers can be thin in results. Its Search endpoint also defaults to 10 queries per second (up to 25 on pay-as-you-go), which high-volume agents can hit.
For the wider field, see our guides to the best web search APIs and search tools for AI agents.
What is Exa: Quick overview
Exa is an AI-powered search engine built specifically for machines. Unlike traditional search engines, Exa uses embeddings-based semantic search to understand meaning rather than just matching keywords, making it ideal for feeding results directly into LLMs, AI agents, and RAG systems.
Main APIs:
- Search: Semantic queries that understand context and intent, in Lite, Auto, and Deep modes
- Contents: Retrieve full page text and highlights from search results
- Find Similar: Feed one URL, get 20 similar pages
- Answer: Summarized responses with citations
- Agent: Asynchronous deep research runs with structured, cited output
- Monitors: Searches that run on a schedule and send updates by webhook
- Websets: Complex queries returning thousands of results (can take up to 1 hour)
Pricing: Free tier with $10 in credits every month plus a $10 onboarding bonus, no payment method required. Search costs $4 (Lite) to $7 (Auto) per 1,000 requests with up to 10 results, and Deep Search $12. Contents is $1 per 1,000 pages, Answer $5 per 1,000, and Monitors $2 per 1,000. Enterprise plans come with zero data retention and custom rate limits.
Top 4 Exa alternatives
Each alternative offers different approaches to AI-powered web search and data extraction.
1. Firecrawl: Web data APIs for AI agents

Firecrawl searches, scrapes, and cleans the web for AI agents. It's built AI-first from the ground up: every output format, every endpoint, and every default is designed for what agents actually need, not retrofitted from a human-facing product. Through Firecrawl Alexandria, the same API key also reaches official data providers and Firecrawl's own indexes for papers, code, and US law.
With over a million developers using it, Firecrawl has become the default web data stack for AI teams and the go-to choice for production AI agents and workflows. It's fully open source (190K+ GitHub stars) and can be self-hosted for teams with data residency, compliance, or infrastructure requirements. Teams that stay on the managed API get an enterprise-ready option: Enterprise plans include zero data retention for web search, with an end-to-end mode where the upstream provider also retains nothing (ZDR searches don't include Firecrawl Alexandria results), plus a DPA and SSO with SCIM.
| Feature | Firecrawl | Exa |
|---|---|---|
| Primary use case | Web data APIs: Search, Scrape, Interact, Crawl | Semantic search & discovery |
| Extraction method | Natural language prompts (zero selectors) | Search results + basic content |
| JavaScript rendering | Automatic (included) | Automatic (Contents API) |
| Output format | Token-efficient markdown, structured JSON | Page text and highlights |
| Free tier | 1,000 credits/month | $10 in credits/month (+$10 bonus) |
| Credit model | 1 credit per page scraped, 2 credits per search | Per request ($4 to $7/1k search, $1/1k contents) |
| Open source / self-hosted | Yes (190K+ GitHub stars) | No (closed source, cloud-only) |
| Benchmark performance | 77.2% coverage, 0.638 F1 (scrape-evals) | 69.2% coverage, 0.508 F1 (scrape-evals) |
| Legal search (official doc ranked first) | 76.2% with the Government & Legal Index (legal retrieval) | 59.6% (legal retrieval) |
| Browser interact | Yes (/interact endpoint) | No |
| Data providers in search | Yes (Firecrawl Alexandria, via sources) | No |
| Specialized indexes | Research, Developer, Government & Legal | People and company indexes |
| CLI | Yes (built-in Claude skill) | No |
How Firecrawl compares to Exa
Full content, not snippets
Most search APIs return links and snippets that still need post-processing before they're useful in an agent context. Firecrawl's Search finds the relevant pages and, when you add scrapeOptions, returns each one's full content as clean, token-efficient markdown or structured JSON in the same call. Without it, each result comes back with query-relevant highlights picked by a custom relevance model; in our SimpleQA eval, a GPT-5.4 agent using /search scored 94.7% on the full SimpleQA set (best of two sessions) while using 10x fewer tokens than processing full pages.
Beyond standard web results, Search supports specialized source types: news for fresh coverage, research for pages on academic sites such as arXiv and PubMed, and pdf for document searches, all returning full content in a single call. The developer category searches issues, pull requests, and READMEs from public code repositories, plus documentation sites, and gov searches US statutes, regulations, and court opinions. Add alexandria to sources and the same call also returns matching data tools (more on that below).
One API replaces a multi-vendor stack
With Exa, you search for pages, then make separate extraction calls via the Contents API. Most teams end up stitching together a search API, a scraper, and a browser tool. Firecrawl covers the full workflow (Find → Extract → Clean → Use) in a single API, at 2 credits per search and 1 credit per page scraped. Fewer vendors, simpler code, predictable costs.
For the full feature-by-feature breakdown, see Firecrawl vs. Exa.
Performance in independent benchmarks
In scrape-evals, our open-source benchmark of 13 web scraping engines on the same 1,000 real URLs, our testing showed the following results:
- Coverage: Firecrawl 77.2% vs Exa 69.2% in our evaluation
- Quality (F1 score): Firecrawl 0.638 vs Exa 0.508 in our evaluation
The F1 score measures how much useful content you capture versus noise. Higher F1 generally means cleaner, more complete extraction, which can be valuable when feeding data into LLMs where context windows matter.
A separate agentic search benchmark by AIMultiple (8 search APIs, 100 real-world AI/LLM queries, 2026) found Firecrawl and Exa statistically tied at the top of the field: Firecrawl ranked #2 (Agent Score: 14.58) and Exa ranked #3 (14.39), with overlapping confidence intervals. Both outperformed the remaining field by a meaningful margin.
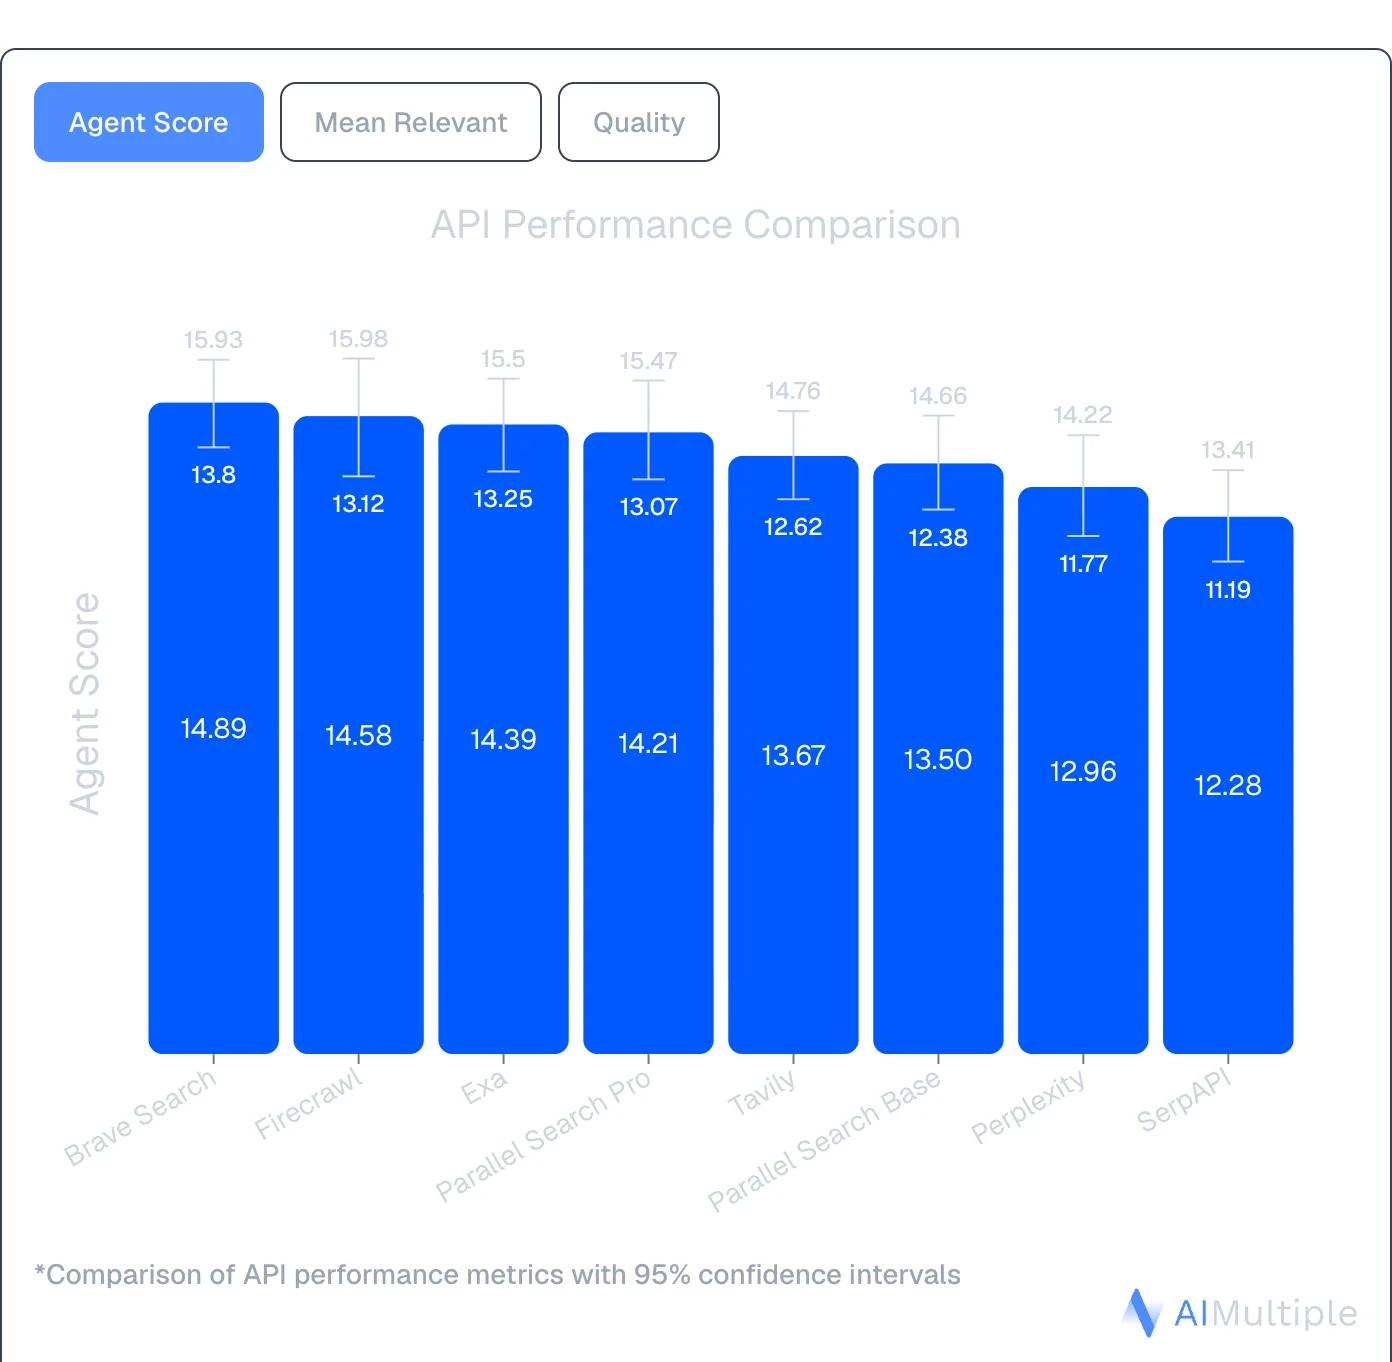
Source: AIMultiple Agentic Search Benchmark 2026
Clean, usable context, not snippets
Exa returns page text and highlights optimized for discovery. Firecrawl goes further: Scrape turns any URL into token-efficient markdown, structured JSON, HTML, links, or a screenshot, and JSON mode pulls exactly the fields you describe in plain English. No CSS selectors, no XPath, no parsing logic required, and when a site changes its HTML, the extraction keeps working.
Handles dynamic pages with Interact
Many sites hide content behind "Load More" buttons, require form submissions, or spread data across paginated views. Firecrawl's Interact endpoint handles these automatically, clicking buttons, filling fields, and navigating pagination, without custom automation code for each site.
Structured data with Firecrawl Alexandria
Exa answers from its own indexes, including its people and company indexes. Firecrawl Alexandria gives your agent official data providers and Firecrawl's own indexes, reached with the same API key as Search and Scrape. Add alexandria to sources on a search and the response carries a tools array next to the web results. Run a tool with scrape and an alexandria block, and the record comes back as typed JSON.
Providers your agent can call include:
- Apollo, FullEnrich, and Data Legion for company enrichment, people and company search, and work emails
- Fiscal.ai for standardized and as-reported financial statements, segment KPIs, and earnings dates
- Particle for podcast episode search
# Web results plus matching Firecrawl Alexandria tools
results = firecrawl.search(
    "NVIDIA revenue by segment",
    sources=["web", "alexandria"],
    limit=3,
)

# Run one tool, billed at the credits listed on it
profile = firecrawl.scrape(
    alexandria={
        "provider": "fiscal-ai",
        "capability": "company/profile",
        "options": {"ticker": "NVDA"},
    },
)
print(profile.alexandria[0].data)
Finding a tool costs nothing, and each tool shows its price in credits before you call it. Some providers, including Apollo, FullEnrich, and Particle, need an org admin to accept their terms first. Keyless sessions don't include Firecrawl Alexandria.
Firecrawl's indexes
Four of the sources inside Firecrawl Alexandria are indexes Firecrawl builds and runs itself:
| Index | What it covers | How to call it | Cost |
|---|---|---|---|
| Web index | The live web, with news and image results | /search | 2 credits per 10 results |
| Research Index | About 43 million paper abstracts from PubMed, bioRxiv, medRxiv, and arXiv, with passage reads and related papers | /search/research/papers | Free, daily limit by plan (unlimited on Scale and Enterprise) |
| Developer Index | 70 million+ issues, merged pull requests, and READMEs from public code repositories, plus documentation sites | /search/developer or categories: ["developer"] | 2 credits per 10 results |
| Government & Legal Index | 30 million+ US federal, state, and local pages: statutes, regulations, codes, and court opinions | /search/gov or categories: ["gov"] | Free, daily limit by plan (unlimited on Scale and Enterprise) |
Firecrawl surfaces that work together
Firecrawl isn't a single-purpose tool. It offers complementary surfaces across the AI-agent web data loop:
- Search: Search the live web and get full content back immediately
- Scrape: Convert any URL into clean markdown or JSON
- Parse: Convert PDFs and documents into usable text
- Crawl: Navigate entire sites without sitemaps
- Map: Discover site structure fast
- Interact: Automate browser actions: click buttons, fill forms, navigate multi-step flows
- Agent: Describe the data you need and let it search and navigate to find it, no URLs required
- Monitor: Schedule recurring checks on pages and get notified by webhook or email when they change
- Firecrawl Alexandria: Find and run data provider tools and Firecrawl's indexes with the same API key
Firecrawl is also an official Claude plugin, integrating directly into Claude for AI-powered web research. The Firecrawl CLI, with a built-in Claude skill, is ideal for terminal-based workflows.
It also integrates with no-code tools like Lovable and n8n, now with a native n8n Cloud integration for one-click connection.
When to choose Firecrawl over Exa
Exa is a search engine. Firecrawl is the web data API to search, scrape, and interact with the web at scale, covering discovery, extraction, crawling, and live page interaction in one workflow.
- Choose Firecrawl when you need the full workflow in one API: Search finds fresh sources, Scrape turns them into token-efficient context, Interact handles dynamic pages, Crawl goes deep across sites (Find → Extract → Clean → Use).
- Choose Firecrawl when extraction quality and depth matter. In our scrape-evals benchmark, Firecrawl achieved 77.2% coverage and 0.638 F1 quality versus Exa's 69.2% coverage and 0.508 F1.
- Choose Firecrawl when your agent looks up statutes, regulations or court opinions. On the Legal Retrieval Benchmark, the Government & Legal Index put the official document first on 76.2% of 581 requests against Exa's 59.6%, at $0 for a full run against $4.07 on Exa.
- Firecrawl handles JavaScript rendering automatically at no extra cost, with predictable pricing: 1 credit per page scraped.
- Choose Firecrawl when your agent needs structured records as well as pages. Firecrawl Alexandria adds company, people, and financial data providers plus the Research, Developer, and Government & Legal indexes to the same API key.
- It's fully open source (190K+ GitHub stars) and can be self-hosted for data residency, compliance, or infrastructure control.
2. Perplexity API
Perplexity's API gives agents two ways to use the live web. The Agent API generates cited answers using models from providers including OpenAI, Anthropic, and Google, and the Search API returns ranked web results as JSON with page text extracted into each result. Instead of just returning search results like Exa, Perplexity can search, process, and summarize information with source citations. Its older Sonar chat completions API has been replaced by the Agent API and stays available only to existing customers.
| Feature | Perplexity API | Exa |
|---|---|---|
| Primary use case | Cited answers and ranked web results | Semantic search & discovery |
| Search method | Live web search + LLM processing | Embeddings-based semantic |
| Output format | Answers with citations, or JSON results with page text | Page text and highlights |
| Pricing | $5 per 1,000 Search API requests; Agent API per token plus tool fees | $4 to $7 per 1,000 searches |
| Free tier | None (prepaid credits) | $10 in credits/month |
| Best for | Fast cited answers, chatbots | Semantic discovery, research |
How Perplexity compares to Exa
Answers, not just links
Perplexity doesn't just find relevant pages. It reads them, synthesizes the information, and returns a coherent answer with citations. Perfect for applications where users need answers, not a list of URLs to read themselves.
Built-in citations
Every answer includes source links, making it ideal for applications where verifiable information matters like legal research, financial analysis, healthcare queries, or academic work.
Raw results when you want them
The Search API skips the model entirely: it returns ranked results with extracted page text for $5 per 1,000 requests, or $1 per 1,000 with Fast Search. A request can carry up to five queries and is billed once.
Simpler than semantic search
While Exa requires understanding embeddings-based semantic search, Perplexity works like a traditional chatbot. Ask a question, get an answer. No need to learn about vector databases or semantic matching.
When to choose Perplexity over Exa
Choose Perplexity when you need fast, summarized answers with citations rather than raw search results. It's ideal for building conversational AI applications, research assistants, or knowledge bases where users expect direct answers backed by sources.
The tradeoff is that pricing differs by API (the Agent API bills per token plus tool fees, the Search API per request), and you lose Exa's semantic search capabilities for discovering conceptually similar content.
3. Linkup
Linkup is an AI search engine optimized for LLMs and AI agents, with a focus on sourcing data from trusted, authoritative sources. Linkup reports ranking #1 on OpenAI's SimpleQA factuality benchmark and positions itself as the world's most accurate search for AI applications.
| Feature | Linkup | Exa |
|---|---|---|
| Primary use case | Fact retrieval & company enrichment | Semantic search & discovery |
| Search method | Two-tier (Standard & Deep) | Embeddings-based semantic |
| Unique feature | Trusted source integration | Find Similar (semantic matching) |
| Output format | Search results, sourced answers, or structured output | Page text and highlights |
| Free tier | $20 in credits/month (professional email) | $10 in credits/month |
| Best for | Business intelligence, enrichment | Semantic discovery, research |
How Linkup compares to Exa
Two-tier search approach
Linkup offers both fast fact retrieval (Standard) and comprehensive deep intelligence searches (Deep). Standard search handles quick queries like "What is Microsoft's Q3 2024 revenue?" while Deep search uses chain-of-thought reasoning for complex questions like "What are Apple and Samsung's strategy differences for 2026?"
Company enrichment capabilities
Unlike Exa's general search focus, Linkup specializes in enriching company profiles with market and competitive intelligence. It can automatically pull product information, target markets, ICP ratings, and customer testimonials, making it powerful for sales and GTM teams.
Transparent pricing with monthly credits
Linkup charges $5 per 1,000 standard searches ($6 with a sourced answer or structured output) and $50 per 1,000 deep searches. Accounts that sign up with a professional email get $20 in credits, topped back up to $20 each month, which covers about 4,000 standard searches.
Native integrations
Linkup integrates natively with CrewAI, LangChain, Make, n8n, and Zapier, making it easy to add to existing AI workflows without custom code.
When to choose Linkup over Exa
Choose Linkup when you need verifiable facts from trusted sources rather than broad semantic discovery. It's ideal for business intelligence applications, company research, competitive analysis, and GTM automation where data accuracy is critical.
The tradeoff is that Linkup's Fetch endpoint reads single URLs and its crawl-based Extract endpoint is in closed beta, so you'll still need a separate tool like Firecrawl to crawl whole sites and extract structured data beyond search results.
4. Brave Search API

Brave Search API stands out with its own independent search index of 30+ billion pages. Unlike some competitors that may rely on Bing or Google, Brave crawls and indexes the web itself. This may be a consideration given Bing's API changes affecting some search services.
Brave dropped its free plan in February 2026. Every plan now includes $5 in credits each month (about 1,000 Search requests), and you need a payment method on file. If you're looking for a free plan, see our Brave Search API alternatives.
| Feature | Brave Search API | Exa |
|---|---|---|
| Primary use case | Independent search, privacy-focused | Semantic search & discovery |
| Search index | Independent (30B+ pages) | Custom (30B+ pages claimed) |
| Pricing | $5 per 1,000 requests (Search plan) | $4 to $7/1k search; $12/1k deep search |
| Free tier | No free plan; $5 in credits/month | $10 in credits/month |
| Rate limits | Up to 50 requests/second | 10 queries/second (25 on pay-as-you-go) |
| Privacy | SOC 2 Type II, no tracking | SOC 2 Type II |
| Best for | Privacy-centric apps, high volume | Semantic discovery, research |
How Brave compares to Exa
Privacy-first architecture
SOC 2 Type II certified with no user tracking. May be well-suited for applications where privacy matters or where you're handling sensitive queries. Brave reports not building user profiles or selling data, which may be relevant for healthcare, legal, or financial applications.
Up to 5 snippets per result
Get more context from each search result, useful for training foundation models or building comprehensive RAG systems. More content per result means fewer API calls for the same information depth.
Search Goggles for customization
Customize search behavior by discarding specific domains or re-ranking results. Build custom search experiences tailored to your use case without forking an entire search engine. This level of control isn't available with Exa's fixed semantic ranking.
Specialized endpoints
- Web Search: General queries across Brave's full index
- LLM Context: Ranked, extracted page content for grounding LLMs
- Answers: Grounded answers with citations, billed per search plus tokens
- Image, Video, News: Vertical-specific search
- Autocomplete and Spellcheck: Query suggestions and correction
When to choose Brave over Exa
Choose Brave for privacy-centric applications where data handling and compliance matter. If you're building tools for sensitive industries, handling confidential research, or serving privacy-conscious users, Brave's architecture and certifications provide guarantees Exa doesn't emphasize.
The tradeoff is that Brave's web search returns SERP-style JSON results rather than Exa's semantic matches; LLM-ready content comes from its separate LLM Context endpoint.
For a deeper look at how Brave compares to other search APIs, see our Brave Search API alternatives guide.
How to switch from Exa to Firecrawl
Most Exa calls map to one Firecrawl endpoint, so a switch is usually a change of client and a few parameter names. The biggest difference is what a search returns: Exa includes page text with its results, while Firecrawl returns query-relevant highlights by default and full-page markdown when you add scrapeOptions. Domain filters carry over as include_domains or exclude_domains (one per request, not both), and date filters move to the tbs parameter.
| Exa endpoint | Firecrawl equivalent | Notes |
|---|---|---|
| Search | Search (/search) | Add scrapeOptions to get full-page markdown for each result in the same call |
| Contents | Scrape (/scrape) or Batch Scrape | Markdown, HTML, JSON, links, or screenshots per URL |
| Answer | No direct equivalent | Search returns the content; your own model writes the answer |
| Agent | Agent (/agent) | Describe the data you need; URLs are optional |
| Monitors | Monitor | Recurring checks with webhook or email alerts |
| Find Similar | No direct equivalent | Describe the kind of page you want in a Search query instead |
| Websets | Firecrawl Alexandria (partial) | No prebuilt entity lists; FullEnrich's people and company search filters by role, industry, size, or location |
A search that returns full page content looks like this in Python:
from firecrawl import Firecrawl

firecrawl = Firecrawl(api_key="fc-YOUR_API_KEY")

results = firecrawl.search(
    "open-source vector databases for RAG",
    limit=5,
    scrape_options={"formats": ["markdown"]},
)

for doc in results.web or []:
    print((doc.markdown or "")[:200])
If your agent calls Exa through a framework, swap the tool rather than the code: Firecrawl has LangChain and LlamaIndex integrations, and the Firecrawl MCP server replaces Exa's MCP server in Claude, Cursor, and other MCP clients. The Search docs cover every parameter, and Firecrawl vs. Exa compares the two feature by feature.
Which Exa alternative should you choose?
- If you need search, scraping, crawling, page interaction, and structured data providers in one API, choose Firecrawl.
- If you want answers written for you with citations, choose Perplexity.
- If you need sourced facts or company research, choose Linkup.
- If you want an independent index with no Google or Bing dependency, choose Brave Search API.
- If semantic discovery is the core of your product, stay with Exa.
Conclusion: Choosing your Exa alternative
Exa brought embeddings-based semantic search to AI agents. When your application needs deep extraction, an open-source option, or different performance characteristics, these alternatives offer specialized approaches for those use cases.
If you need the full web data stack, Firecrawl covers Search, Scrape, Interact, and Crawl in one API, and Firecrawl Alexandria adds data providers and Firecrawl's indexes on the same key. It's built AI-first, with over a million developers and 190K+ GitHub stars. At $99/month billed monthly ($83/month billed annually) for 100K credits, it delivers token-efficient output with no post-processing required. For a deeper feature-by-feature comparison, see Firecrawl vs. Exa.
Try Firecrawl free with 1,000 credits per month (no card required) or explore the docs.
Use Firecrawl in your agent
Add Firecrawl to ChatGPT, Claude, Cursor and more in one click.
Frequently Asked Questions
Is Exa AI free?
Yes, Exa has a free tier: $10 in credits every month plus a $10 onboarding bonus, with no payment method required. At $7 per 1,000 Auto searches, that covers about 1,400 searches a month. If you also need page scraping and crawling on a free plan, Firecrawl gives 1,000 free credits a month with no card required, shared across Search, Scrape, Crawl, and Interact.
Which Exa alternative is most cost-effective?
At high volume, Perplexity's Fast Search is cheapest at $1 per 1,000 requests, with Firecrawl next at about $2 per 1,000 searches on the Standard plan, versus $5 for Perplexity's standard Search, Linkup, and Brave. At low volume, start on a free tier: Firecrawl gives 1,000 free credits a month (about 500 searches), and those credits also cover scraping the pages you find.
Can Exa alternatives handle JavaScript rendering?
Yes, most of them do. Firecrawl renders JavaScript automatically on every scrape at no extra cost, and its Interact endpoint goes further, clicking buttons, filling forms, and paging through content that only loads after user actions.
Which alternative is best for RAG applications?
Firecrawl is a strong choice for RAG: add scrapeOptions to a /search call and each result comes back as full-page markdown, so context arrives ranked and clean without a separate extraction step.
Are these alternatives compatible with LangChain?
Yes. Firecrawl and Linkup both have LangChain integrations, and Firecrawl also has a LlamaIndex integration. If your agent calls Exa through LangChain, switching to Firecrawl usually means swapping the Exa tool for the Firecrawl one rather than rewriting your code.
Which alternative handles complex websites best?
Firecrawl, because it can act on pages, not just read them. It renders JavaScript on every scrape, and its Interact endpoint clicks buttons, fills forms, and moves through multi-page flows. Exa returns search results and page text but doesn't click or fill forms, so pages behind those steps usually call for a separate browser tool.
Does Firecrawl have people and company data like Exa?
Yes, through Firecrawl Alexandria. The same API key that runs Search and Scrape can call official data providers, including Apollo, FullEnrich, and Data Legion for company enrichment, people and company search, and work emails, and Fiscal.ai for company financials. Finding a tool is free, running one costs the credits listed on it, and some providers ask an org admin to accept their terms first.
What indexes does Firecrawl have?
Firecrawl runs four indexes inside Firecrawl Alexandria: the web index behind /search, the Research Index of about 43 million paper abstracts from PubMed, bioRxiv, medRxiv, and arXiv, the Developer Index of 70 million+ issues, pull requests, READMEs, and documentation pages, and the Government & Legal Index of 30 million+ US government pages. The Research and Government & Legal indexes are free, with a daily limit set by your plan.