Brave Search API no longer has a free plan. Every account needs a credit card, and the $5 monthly credit covers about 1,000 searches before Search costs $5 per 1,000 requests. If you used Brave to prototype or run evals for free, you now need billing set up first. Its LLM Context endpoint returns ranked page chunks for agents, but it still can't fetch a page you choose, return a full page as Markdown, or crawl a site. The alternatives below are compared on that gap and on price.
If you're switching, here is the best pick per job: Firecrawl for search plus full-page content and extraction in one API, Parallel for deep research, LLMLayer for low per-call prices across search, scraping and answers, Exa for meaning-based search, and Tavily for agent-ready results with LangChain support.
TL;DR: Best Brave Search API alternatives
| Tool | Best for | Standout feature | Price per 1,000 searches | Free tier | What search returns |
|---|---|---|---|---|---|
| Firecrawl | Full web data stack for AI agents | Search, Scrape, Interact, Crawl, plus 400+ data providers via Firecrawl Alexandria | About $2 on Standard (billed monthly) | 1,000 credits/month (500 searches), no card | Full pages as Markdown in the same call, or snippets |
| Parallel AI | Agentic web research at scale | Search, Extract, Task and FindAll APIs built for agents | $1 to $5 (10 results per request) | $5 in credits/month | Ranked URLs and compressed excerpts |
| LLMLayer | All-in-one web infrastructure | Search, scrape, crawl, and answers in one API | $2 | $1 in free credits, no card | Search results; full pages through its Scraper |
| Exa | Semantic search for research-heavy apps | Embedding-based search that understands meaning | $4 (lite), $7 (auto), $12 (deep) | $10 in credits/month, no card | Text and highlights for the top 10 results |
| Tavily | AI search and research workflows | AI-optimized results, include_raw_content and /extract for full content | $8 pay as you go (basic search) | 1,000 credits/month, no card | Ranked snippets, raw content optional |
For reference, Brave Search API costs $5 per 1,000 requests at up to 50 requests per second, with $5 in monthly credit and a card required, and returns snippets or ranked chunks. Prices and limits come from each vendor's pricing page and docs, read in October 2026.
What is Brave Search API: Quick overview
Brave Search API is a programmable web search service from Brave that lets developers query Brave's independent web index over HTTP and use the results inside their own apps, search experiences, and AI systems.
Unlike search APIs that license results from Google or Bing, Brave crawls and indexes the web itself: over 40 billion pages as of February 2026, updated with millions of new pages daily to capture recent events and fresh content. Brave is also the web search provider Anthropic lists for Claude.
Brave's browser built a reputation on privacy-first browsing (no user tracking, no profile building), and that same philosophy carries into the search API.
Main capabilities:
- Standard web search: URLs, titles, snippets, and metadata from an index of 40B+ pages
- Vertical and rich results: specialized endpoints for news, images, videos, and local results
- LLM Context: ranked page chunks from Brave's index, sized by a token budget you set (1,024 to 32,768 tokens, 8,192 by default) across up to 50 URLs
- Answers (formerly AI Grounding): an OpenAI-compatible endpoint that returns grounded answers with citations
- Real-time data: index updated daily to surface recent content
What Brave Search API sells today: two self-serve plans, both prepaid credits with no subscription. Search costs $5 per 1,000 requests at up to 50 requests per second and includes LLM Context. Answers costs $4 per 1,000 queries plus $5 per million input tokens and $5 per million output tokens, at up to 2 requests per second. Each plan includes $5 in credits a month, and a credit card is required. The older free, Base AI and Pro AI plans are no longer listed.
That matters more now that Google's Custom Search JSON API shuts down on January 1, 2027, which leaves fewer general web search APIs to choose from.
Quick specs:
| Feature | Detail |
|---|---|
| Index size | 40B+ pages |
| Index freshness | Millions of pages updated daily |
| Free tier | No free plan; $5/month in credits (~1,000 Search requests), credit card required |
| Paid plans | Search $5 per 1,000 requests; Answers $4 per 1,000 queries plus token costs |
| Privacy | SOC 2 Type II certified, no user tracking |
| Rate limits | 50 requests/second on Search, 2 requests/second on Answers |
Best suited for:
Teams that need a lightweight, privacy-respecting search layer integrated into a product where search is a supporting feature, not the core offering. If your app needs to surface relevant links or ground AI responses with fresh web results, and you don't want to build on top of Google or Bing, Brave Search API is a solid starting point.
Why do users look for Brave Search API alternatives?
| Issue Category | Key Problem |
|---|---|
| Pricing | No free plan; $5 monthly credit (~1,000 searches) and a card required |
| Search quality | Independent index still maturing; niche query results lag behind Google |
| AI agent support | Agentic workflow features still developing for production use cases |
| Extraction depth | Snippets or ranked chunks; can't fetch a URL you choose or a full page |
| Rate limits | Answers capped at 2 requests/second; Search at 50 requests/second |
| Output format | Raw JSON SERPs require additional processing for AI/LLM consumption |
A developer who ran Brave Search API in production for three months shared a detailed breakdown of where it fell short for their research agent:
We saw our free tier going from 5,000 queries/month to $5 in credits which is fine for production but very annoying when you're burning through queries during eval runs. For a bigger structural limitation for my use case, Brave gives you search results and not full page content so if your agent needs to read the article or report, you need a separate scraping layer on top.
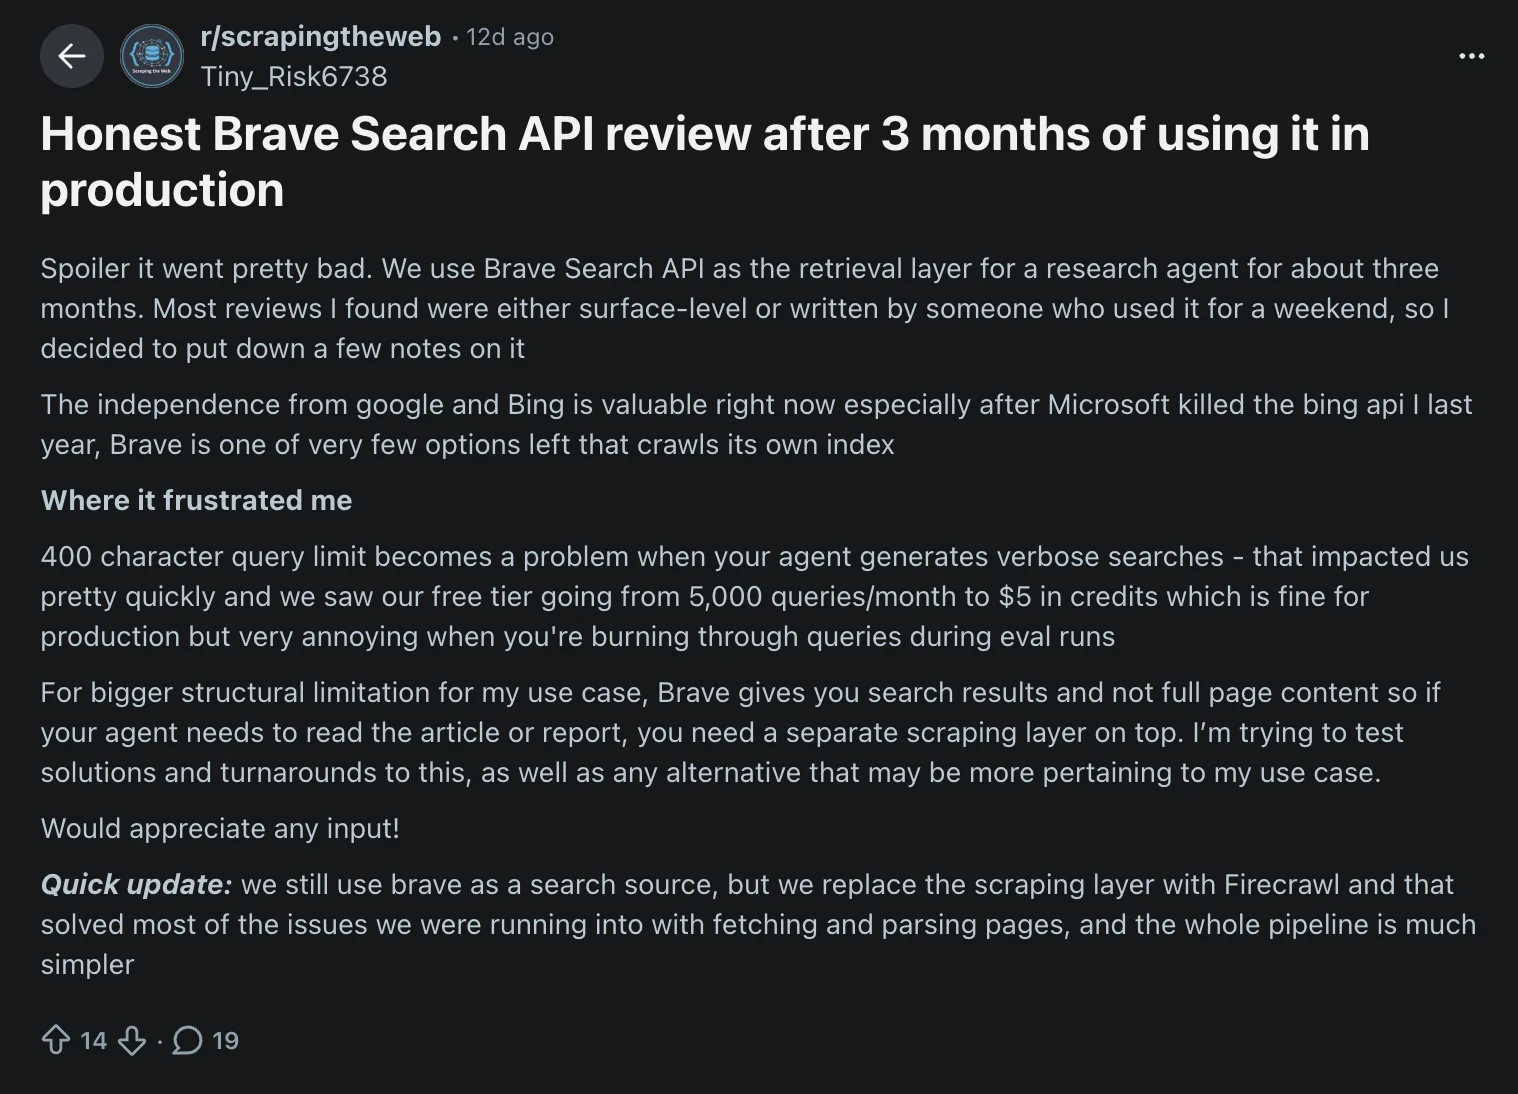
Honest Brave Search API review after 3 months of using it in production (r/scrapingtheweb)
Their eventual fix was replacing the scraping layer with Firecrawl, which simplified the pipeline and resolved most of the fetching and parsing issues. The reasons below explain why teams reach that same conclusion.
Reason #1: The free tier was quietly removed
The biggest recent friction point for developers is the elimination of Brave's zero-cost plan.
As recently as August 2025, Brave offered up to 5,000 free queries per month with no billing required. By February 2026, that plan was gone for new users. In its place: a credit-based system where every plan includes $5 in monthly credits (roughly 1,000 searches) before charges kick in, and a credit card is required to sign up. Brave's pricing page no longer lists a free plan at all.
A Reddit thread flagged the change and drew significant developer pushback.
For developers who relied on Brave as a zero-cost search layer for prototyping or low-volume apps, this change prompted a search for alternatives. Teams using Brave as their OpenClaw search provider were directly affected, since Brave is OpenClaw's default web_search configuration.
Reason #2: Search quality is still maturing
Brave's independent index is a genuine differentiator, but it comes with a trade-off. Because Brave crawls and ranks the web without relying on Google or Bing, its result quality is still catching up for long-tail or niche queries.
As one user put it in a Reddit thread: Brave's fully independent index is a good thing, but it means quality gaps exist compared to more established engines. Brave acknowledges this is an ongoing journey (their index is growing by 100M+ pages/day), but for production use cases that require Google-level result quality, it remains a gap to consider.
Reason #3: AI agent support is still catching up
We're in an era where developers routinely run 10+ agentic workflows: research pipelines, competitive monitoring, RAG systems, real-time assistants, all depending on reliable web data under the hood. For these use cases, the web data stack needs to hold up under real load: deep extraction, structured output, and the ability to handle dynamic pages without extra configuration.
Brave is clearly investing in this direction with its Answers endpoint and LLM Context API. But for teams building production-grade agents today, Brave's tooling for agentic workflows (full-page content retrieval, multi-step navigation, and structured data extraction) is still developing. It's a solid foundation, and the trajectory is promising, but developers with demanding AI workflows often find themselves needing more. For a side-by-side look at accuracy benchmarks, latency, and cost tradeoffs for these production workloads, see our full best deep research APIs comparison, or our web search APIs guide for a broader look at SERP providers alongside AI-native platforms.
Reason #4: Chunks from its index, not full pages you choose
Brave Search API returns URLs, titles, and snippets, and its LLM Context endpoint returns ranked chunks of those pages within a token budget. Both come from Brave's index. It can't fetch a URL you choose, return a full page as Markdown, crawl a site, or pull structured JSON from a page.
For AI workflows that need complete article text, product details, or structured data from specific pages, developers must pair Brave with a separate scraping tool. This adds integration complexity and cost to what was meant to be a simple search layer.
One Firecrawl user on G2 describes the alternative:
One call gives me search results and the page content as clean markdown, so my agent can read the actual page instead of a snippet.
Andreas K., Senior Projektmanager (G2 review)
Reason #5: Rate limits differ by endpoint
Search runs at up to 50 requests per second, but Answers, the endpoint that returns grounded responses, is capped at 2 requests per second. That can be tight for real-time agents or batch research pipelines that lean on answers rather than raw results.
Reason #6: Raw JSON output needs post-processing for AI
Brave returns standard SERP-style JSON: links, snippets, metadata. LLM Context and Answers add model-ready chunks and cited answers, but the base search output isn't directly optimized for LLM consumption. Teams building RAG pipelines or AI agents often find they need to clean, reformat, or chunk the results before feeding them into a model.
What are the top 5 Brave Search API alternatives in 2026?
These alternatives offer different approaches to the gaps we outlined above: deeper extraction, stronger AI agent support, broader index quality, and output that feeds directly into LLM pipelines without extra processing.
| Alternative | Best for | Quick differentiator |
|---|---|---|
| Firecrawl | Full web data stack for AI agents | Search, Scrape, Interact, Crawl, plus 400+ data providers via Firecrawl Alexandria |
| Parallel AI | Agentic web research at scale | Search, Extract, Task and FindAll APIs |
| LLMLayer | All-in-one web infrastructure | Search, scrape, crawl, and answers in one API |
| Exa | Semantic search for research-heavy apps | Embedding-based search that understands meaning |
| Tavily | AI search and research workflows | AI-optimized results, include_raw_content and /extract for full content |
1. Firecrawl: Web data APIs for AI agents
Firecrawl searches, scrapes, and cleans the web for AI agents. It's built AI-first from the ground up: every output format, every endpoint, and every default is designed for what agents actually need, not retrofitted from a human-facing product.
Over a million developers and thousands of enterprise teams use Firecrawl, which has become the default web data stack for AI teams and the go-to choice for production AI agents and workflows. It's fully open source (190K+ GitHub stars) and ready for enterprise search workloads. On Enterprise plans, zero data retention keeps queries and results off Firecrawl's side, and you can sign a DPA and use SSO. For Search, end-to-end ZDR also relies on the upstream search provider enforcing it, and ZDR searches leave out Firecrawl Alexandria provider results.
| Feature | Firecrawl | Brave Search API |
|---|---|---|
| Primary use case | Web data APIs: Search, Scrape, Interact, Crawl | Web search and discovery |
| Output format | Token-efficient markdown, structured JSON | JSON results (snippets), or ranked chunks via LLM Context |
| Full-page extraction | Yes, included | No, snippets or chunks from its index |
| JavaScript rendering | Automatic, included at no extra cost | Handled in index, not extractable |
| Post-processing needed | No | Yes, for most AI workflows |
| Free tier | 1,000 credits/month, no card | No free plan; $5/month in credits, card required |
| Open source | Yes (190K+ GitHub stars) | No |
| Interact endpoint | Yes (session-based page interaction) | No |
| Data providers in search | Yes (Firecrawl Alexandria, 400+ providers via sources) | No |
| CLI | Yes (built-in Claude skill) | No |
Full content, not snippets
Most search APIs return links and snippets that still need post-processing before they're useful in an agent context. Firecrawl's Search finds the relevant pages and returns their full content: clean, token-efficient markdown or structured JSON ready to use immediately.
Search also supports specialized source types: news for fresh coverage, research for academic papers from arXiv and PubMed, and pdf for document searches, all returning full content, not snippets. The developer category searches GitHub issues, pull requests, READMEs, and docs.
One API replaces a multi-vendor stack
With Brave Search API, you get snippets or chunks from Brave's index and then need a separate scraper to get the full page you want. Most teams end up stitching together a search API, a scraper, and a browser tool. Firecrawl covers the full workflow (Find → Extract → Clean → Use) in a single API at one flat credit per page. Fewer vendors, simpler code, predictable costs.
Context-aware queries
Firecrawl supports a context parameter so agents can describe what they're actually trying to do, not just fire off a keyword query. Search bars were built for humans. Agents have more to say, and Firecrawl lets them.
Find, extract, and clean in one call
Brave Search API gives you links, snippets, or ranked chunks. To get the full page, you need a second tool. Firecrawl handles both in a single API call: it finds the relevant pages and extracts their full content, returning structured data ready for your model.
Search costs 2 credits per 10 results, and each result you scrape is billed like a scrape, with no parsing logic required.
Beyond standard web results, the search endpoint supports specialized source types (web, news, images) and content categories (developer for GitHub issues, pull requests, READMEs, and docs, research for academic sources like arXiv and PubMed, pdf for document searches). You can filter by time range (past hour through custom date ranges), target results by country, and search for HD images by exact resolution using Google Images operators. For compliance-sensitive teams, the endpoint also supports Zero Data Retention (ZDR) via the enterprise parameter: end-to-end ZDR (enterprise: ["zdr"]) asks both Firecrawl and its upstream search provider not to store query or result data, so it relies on that provider enforcing it too; anonymized ZDR (enterprise: ["anon"]) covers Firecrawl's side at standard search rates. ZDR searches leave out Firecrawl Alexandria provider results.
Since September 2026 the same call can also return data tools: add alexandria to sources and the response carries a tools array from Firecrawl Alexandria, drawn from official APIs such as SEC EDGAR and FRED, licensed publishers such as Fiscal.ai and Particle, and Firecrawl's Research, Developer, and Government indexes. Finding a tool costs nothing, and running one is billed at its listed price.
The catalogue itself is the argument for choosing Firecrawl here. It includes the Wayback Machine for how a page looked on any past date, Greenhouse job boards for every open role at a company, GitHub, Hugging Face, PyPI, and Stack Exchange for developer questions, Companies House and SEC EDGAR for registries and filings, and the rest of its 400+ providers, all reachable from the one search call an agent already makes.
Output that goes straight into your models
Brave returns SERP-style JSON that needs cleaning, chunking, and formatting before it's useful in an LLM context. Firecrawl returns output your pipeline can consume immediately: markdown, html, json, links, screenshot, summary, or image, no post-processing required.
You define what you need ("get product name, price, and reviews"), and Firecrawl's extraction engine pulls exactly that. No CSS selectors, no XPath.
from firecrawl import Firecrawl

firecrawl = Firecrawl(api_key="fc-YOUR-API-KEY")

# Search: find fresh sources and get full content back
results = firecrawl.search(
    query="firecrawl",
    limit=3,
    scrape_options={"formats": ["markdown"]}
)
print(results)

# Scrape: turn any URL into clean, structured data
result = firecrawl.scrape(
    "https://example.com",
    formats=["json"],
    json_options={"prompt": "Extract the founder names, roles, and backgrounds"}
)
print(result.json)
The /interact endpoint: Go deeper into any result
/interact is built for the search-then-dig-deeper workflow: scrape a page to get its initial content, then call /interact on the same scrapeId to keep going. Describe what you want in natural language ("click the next page and extract the pricing table") or write Playwright code directly for full control.
Sessions preserve state between calls, so you can chain multiple interactions without reinitializing: click a tab, then extract its content, then paginate. Persistent profiles let you save login state (cookies, localStorage) across separate scrapes, making authenticated content accessible at scale without re-entering credentials.
Endpoints that work together
- Search: Search the live web and get full content back immediately
- Scrape: Convert any URL into clean markdown or JSON
- Interact: Automate browser actions: click buttons, fill forms, navigate multi-step flows
- Crawl: Navigate entire sites without sitemaps
Firecrawl is also an official Claude connector, integrating directly into Claude for AI-powered web research without writing code. The Firecrawl CLI, with a built-in Claude skill, covers terminal-based workflows. It also works with no-code tools like Lovable and n8n.
Pricing
You can try Search and Scrape with no API key or account through Keyless, within a daily per-IP limit. With an account, the Free plan adds 1,000 credits a month (500 searches) with no card, and paid plans start at Hobby.
| Plan | Price (billed monthly) | Price (billed annually) | Credits included |
|---|---|---|---|
| Free | $0 | $0 | 1,000 credits |
| Hobby | $19/mo | $16/mo | 5,000 credits |
| Standard | $99/mo | $83/mo | 100,000 credits |
| Growth | $399/mo | $333/mo | 500,000 credits |
| Scale | $749/mo | $599/mo | 1,000,000 credits |
| Enterprise | Custom | Custom | Unlimited |
When to choose Firecrawl over Brave Search API
Choose Firecrawl if you need:
- The full workflow in one API: Search finds fresh sources, Scrape turns them into token-efficient context, Interact handles dynamic pages, Crawl goes deep across sites (Find → Extract → Clean → Use)
- Clean web context without post-processing: markdown and structured JSON built for agents, not humans
- Real-web handling: JS-heavy pages, SPAs, geo-sensitive sources
- Session-based interaction with dynamic pages (forms, auth flows, pagination)
- ZDR compliance for sensitive query workloads
- Predictable flat-rate pricing per page
- Open source with self-hosting option
2. Parallel AI: Agentic web research built for scale
Parallel AI (officially Parallel Web Systems) is a newer entrant building web infrastructure specifically for AI agents. It raised a $100M Series A in November 2025 with a thesis that the web's next major user is AI, and that existing search infrastructure wasn't built for it.
The core differentiator is accuracy. Parallel benchmarks itself at 47% on the HLE (Humanity's Last Exam) benchmark compared to Exa at 24%, Tavily at 21%, and Perplexity at 30%. Results include provenance and evidence for every output, rather than raw links or ranked snippets.
| Feature | Parallel AI | Brave Search API |
|---|---|---|
| Primary use case | Agentic web research and deep data retrieval | Web search and discovery |
| Search method | Multi-agent, evidence-based retrieval | Keyword-based against independent index |
| Output format | Structured results with full provenance | JSON results (snippets), or chunks via LLM Context |
| Pricing model | Pay per query, not per token; Search $1 to $5 per 1,000 requests | Pay per request, $5 per 1,000 searches |
| Free tier | $5 in credits a month | No free plan; $5/month in credits, card required |
| Privacy | SOC 2 Type II certified | SOC 2 Type II, no user tracking |
| Maturity | Newer, still building out ecosystem | Established, growing index |
What it offers
Parallel's product suite covers four main use cases:
- Search API: Real-time web queries optimized for agent consumption with sourced, evidence-backed results
- Task API (Deep Research): Multi-step research that reasons across sources, not just returns links
- Find All: Dataset building at scale, for teams that need comprehensive coverage of a domain
- Web Enrichment and Monitor API: Enrich records with live web data, and track changes over time
When to consider Parallel AI
Parallel is worth evaluating if you're building research-heavy agents that need high-accuracy outputs with clear sourcing, particularly for enterprise or compliance-sensitive workflows. Its pay-per-query model (not per token) is also useful for teams that need predictable cost scaling.
That said, it's a newer solution. Ecosystem integrations, SDKs, and community resources are still maturing compared to more established tools on this list. For teams that need a proven, production-ready stack today, Firecrawl or Exa may be the lower-risk choice. But if you're actively evaluating Parallel AI alternatives, that comparison covers the full competitive landscape.
3. LLMLayer: All-in-one web infrastructure for AI
LLMLayer offers a unified API that combines search, scraping, crawling, and LLM-powered answers in one platform. Where Brave covers search and Firecrawl covers extraction, LLMLayer tries to bundle both, along with a few additional capabilities, under a single integration.
| Feature | LLMLayer | Brave Search API |
|---|---|---|
| Primary use case | Unified web infrastructure (search + scrape + answers) | Web search and discovery |
| Output format | Markdown, HTML, screenshots, PDFs, cited answers | JSON results (snippets), or chunks via LLM Context |
| Search pricing | $2 per 1,000 requests, prepaid | $5 per 1,000 requests |
| Free tier | $1 in free credits, no card required | No free plan; $5/month in credits, card required |
| JavaScript rendering | Included in scraper | Handled in index, not extractable |
| Best for | Teams needing search, scraping, and answers in one | Lightweight privacy-first search layer |
What it offers
LLMLayer bundles six APIs that normally require multiple services:
- Web Search: Query across web, news, images, videos, and more. Filter by recency, localize by country, include or exclude domains
- Scraper: Convert any URL to markdown, HTML, screenshots, or PDFs, with JavaScript rendering included
- Map: Discover complete website structure in seconds
- Crawler: Navigate entire websites with sitemap generation and deep crawling
- Answer API: Search, reason, and answer in one call with citations included
- Extract: Pull structured data from a page
When to consider LLMLayer over Brave
LLMLayer is worth considering when you need both search and scraping but want a single vendor rather than combining Brave with a separate scraper. Its search costs $2 per 1,000 requests, answers $0.007 per call and scraping $0.001 per page, all from prepaid credits that never expire.
One consideration: LLMLayer is newer and has less market presence than the other tools on this list. Community adoption and third-party integrations are still growing, so teams that need a well-documented, widely-used stack may find the established alternatives lower risk.
4. Exa: Semantic search for research-heavy applications
Exa takes a fundamentally different approach to search than Brave. Where Brave matches keywords against its index, Exa uses embeddings to understand the meaning and context of a query. This makes it particularly useful for research-heavy applications where intent matters more than exact keyword match.
| Feature | Exa | Brave Search API |
|---|---|---|
| Primary use case | Semantic search and research | Web search and discovery |
| Search method | Embedding-based (understands meaning) | Keyword-based against independent index |
| Unique feature | Deep search and an async research Agent | Search Goggles for custom ranking |
| Output format | Text and highlights, full page text via Contents, cited answers | JSON results (snippets), or ranked chunks via LLM Context |
| Free tier | $10 in credits a month, no card | No free plan; $5/month in credits, card required |
| Privacy | SOC 2 Type II | SOC 2 Type II, no user tracking |
| Best for | Research, technical discovery, semantic queries | Lightweight privacy-first search layer |
How Exa compares to Brave
Understands meaning, not just keywords
Brave matches your query against its index using traditional keyword signals. Exa uses embeddings to understand intent. Ask Exa "find articles explaining how LLMs handle long context" and it aims to understand the concept, not just match those exact words. This approach makes it well-suited for research assistants, competitive intelligence, and complex question answering where keyword search falls short.
Five endpoints
- Search: Semantic queries in lite, auto and deep modes
- Contents: Retrieve page text, highlights and summaries from URLs
- Answer: Get summarized, cited responses instead of just links
- Agent: Async research, list building and enrichment with structured output (it replaced the retired
/researchendpoint) - Websets: List building with criteria checks and enrichments, sold as a separate subscription
When to choose Exa over Brave
Consider Exa when your application needs to understand conceptual similarity and intent, not just surface pages that contain specific words. Technical documentation discovery, academic research assistants, and competitive intelligence workflows can benefit from semantic search.
One consideration: Exa prices search by type, at $4 per 1,000 requests for lite, $7 for auto and $12 for deep, with text and highlights included for the first 10 results. Extra content types and results above 10 add $1 per 1,000 each, so costs climb when you want full pages or more results.
For a detailed breakdown, see Firecrawl vs. Exa and our full Exa alternatives guide.
5. Tavily: AI search and research API
Tavily is a search API built for AI agents and LLMs. Unlike Brave, it optimizes results specifically for LLM consumption: ranked results with relevance scores and citations formatted for agent workflows. Tavily's platform also spans /extract, /crawl, /map, and /research, and /search supports include_raw_content for inline raw HTML alongside results.
It's particularly popular in the LangChain ecosystem, where native integrations make it easy to drop into an existing agent with minimal setup.
| Feature | Tavily | Brave Search API |
|---|---|---|
| Primary use case | AI search and research workflows | Web search and discovery |
| Output format | Ranked results with raw content via include_raw_content or /extract | JSON results (links, snippets), or chunks via LLM Context |
| LLM optimization | Yes, results ranked for agent context | Partial (Answers endpoint only) |
| Free tier | 1,000 credits/month, no card | No free plan; $5/month in credits, card required |
| Entry pricing | $30/month (4,000 credits) | $5 per 1,000 requests |
| At 100k requests | ~$800 PAYG basic search | ~$500 at $5 per 1,000 |
| LangChain native | Yes | Available via community integrations |
| Best for | AI search and research workflows | Lightweight privacy-first search layer |
How Tavily compares to Brave
Results formatted for LLMs, not humans
Brave returns standard SERP JSON. Tavily's results include relevance scoring and are structured for direct injection into agent context windows. If you want search results that are already ranked and formatted for LLM consumption without post-processing, Tavily is closer to plug-and-play than Brave.
Native LangChain integration
Tavily is one of the most commonly used search tools in LangChain-based agents. The integration is a few lines of code, which makes it a natural choice for teams already in that ecosystem. Brave has community integrations but isn't as tightly coupled to LangChain out of the box.
Five core endpoints
- Search: Real-time web queries with AI-optimized, ranked results; optional raw content via
include_raw_content - Extract: Pull full content from specific URLs with JavaScript rendering
- Crawl: Navigate entire websites using natural language instructions
- Map: Discover website structure before extraction
- Research: Multi-step agentic research that synthesizes results across sources
Pricing at scale
Tavily's free tier covers about the same volume as Brave's $5 credit (1,000 basic searches a month) but needs no card. At higher volumes, Tavily's pay-as-you-go model adds up: basic search costs 1 credit and advanced search 2, at $0.008 per credit, so 100k basic searches cost around $800. Monthly plans bring the credit price down, from $0.0075 on the $30 Project plan to $0.005 on the $500 Growth plan. For comparison, Firecrawl's Standard plan covers 50,000 searches for $99/month billed monthly ($83/month billed annually), and Growth covers 250,000 for $399/month billed monthly ($333/month billed annually).
For a detailed comparison, see Firecrawl vs. Tavily and our full Tavily alternatives guide.
When to choose Tavily over Brave
Consider Tavily when you need AI-optimized search results that feed directly into agent context without additional formatting, especially if you're already using LangChain. It handles the "find relevant content and rank it for my LLM" use case more directly than Brave's raw SERP output. When you need full page content, include_raw_content and /extract cover that in the same platform.
Which Brave Search API alternative should you choose?
- Firecrawl if you need the full web data stack: Search finds fresh sources, Scrape turns them into clean context, Interact handles dynamic pages (one API covering Find → Extract → Clean → Use)
- Parallel AI if you're building enterprise-grade research agents and want evidence-backed, sourced results at scale (and are willing to evaluate a newer platform)
- LLMLayer if you want a single API covering search, scraping, crawling, and answers, paid from prepaid credits that never expire
- Exa if semantic understanding matters more than keyword matching, particularly for research-heavy or discovery-driven applications
- Tavily for AI search and research workflows, with drop-in LangChain integration and raw-content options on
/searchor/extract
If you need Google's own results or a free option instead, look at SERP APIs such as Serper and SerpApi, or self-host SearXNG.
Brave Search API is a solid choice for teams that want a lightweight, privacy-first search layer without depending on Google or Bing. But the end of its free plan, output limited to snippets and chunks from its own index, and still-maturing agentic tooling push many developers to look elsewhere.
For most AI teams, Firecrawl is the most complete starting point: built AI-first, used by over a million developers and with 190K+ GitHub stars, it covers Search, Scrape, Interact, and Crawl (the full web data stack) with token-efficient output and no platform lock-in. Try Firecrawl with no API key through Keyless, sign up for 1,000 free credits a month (no card required), or explore the docs. If you're specifically building Claude-based agent workflows, see the Anthropic web search alternatives guide for a Claude-focused comparison.
Use Firecrawl in your agent
Add Firecrawl to ChatGPT, Claude, Cursor and more in one click.
Frequently Asked Questions
What is the Brave Search API used for?
The Brave Search API lets developers query Brave's independent web index of 40B+ pages programmatically. It is used for building search features into apps, powering AI agents with real-time web data, and grounding LLM responses with cited, up-to-date results.
Is the Brave Search API still free?
No. Brave Search API no longer has a free plan. Each plan includes $5 in credits a month, which covers about 1,000 Search requests, and a credit card is required to sign up. After the credit runs out, Search costs $5 per 1,000 requests.
How much does the Brave Search API cost?
Search costs $5 per 1,000 requests at up to 50 requests per second, and the LLM Context endpoint is part of the Search plan. Answers costs $4 per 1,000 queries plus $5 per million input tokens and $5 per million output tokens, at up to 2 requests per second. Both plans include $5 in credits a month.
Which Brave Search API alternatives return full page content?
Firecrawl returns full pages as Markdown from the same search call. Parallel returns full pages through its Extract API, and LLMLayer through its Scraper. Exa returns page text and highlights with search and more through its Contents endpoint. Tavily returns raw page content with include_raw_content and full pages through its Extract endpoint. Brave returns snippets or ranked chunks from its own index.
Why do developers look for Brave Search API alternatives?
Developers explore alternatives when they need full-page content beyond snippets and ranked chunks, semantic search capabilities, richer AI-optimized output formats, more aggressive rate limits, or a unified search-plus-scrape pipeline in a single API.
Which Brave Search API alternative is best for AI agents?
Firecrawl is the strongest choice for AI agents. Built AI-first, it covers the full workflow agents need: Search finds fresh pages from the live web, Scrape turns them into token-efficient context, Interact handles dynamic pages, and Crawl goes deep across sites, all in one API without post-processing.
Can Brave Search API alternatives handle JavaScript-rendered pages?
Yes. Firecrawl includes automatic JavaScript rendering at no extra cost. LLMLayer's scraper also includes JavaScript rendering. Exa and Tavily can retrieve content from dynamic pages depending on the endpoint used.
Is Firecrawl a good replacement for Brave Search API?
Firecrawl complements or replaces Brave Search API depending on your use case. If search quality matters, Firecrawl returns full-content results from the live web: no snippets, no pre-digestion, no post-processing required. If you also need full-page extraction alongside search, Firecrawl's combined Search and Scrape pipeline goes further than Brave's snippets and ranked chunks, since it can also fetch any URL you choose and crawl whole sites.
Do any Brave Search API alternatives return data providers alongside web results?
Firecrawl does, through Firecrawl Alexandria. Add alexandria to the sources parameter and the search response carries a tools array next to the web results, drawn from official APIs such as SEC EDGAR and FRED, licensed publishers such as Fiscal.ai and Particle, and Firecrawl's Research, Developer, and Government indexes. Brave returns SERP-style JSON, and the other alternatives here return pages or snippets.
What data does Firecrawl Alexandria cover that Brave Search API doesn't?
Brave adds structured results for places, weather, stocks, currency, crypto, and sports scores to its web results. Firecrawl Alexandria covers categories Brave has no endpoint for, such as SEC EDGAR filings, company and contact enrichment from Apollo and FullEnrich, job postings from Workable and SmartRecruiters, ClinicalTrials.gov studies, and package data from npm and PyPI. Each tool returns records from the source itself, so an agent gets a filing or a company profile instead of web pages that mention it.
What does Firecrawl Alexandria cost?
Finding tools is free on any search. Running a tool goes through the scrape endpoint with an alexandria block (provider, capability, options) in place of a URL and is billed at the price listed on the tool, which is deducted from your Firecrawl credits. Prices vary by provider, so read the contract before wiring a tool into a loop. Firecrawl Alexandria needs an API key on a team where it is enabled, and some licensed publishers require an organization admin to accept their terms once before the first call.