
OpenAI’s current API page lists GPT-5.6 Sol at $4 per million input tokens and $20 per million output tokens for short context. Long-context rates are $8/M input and $30/M output. Cached input is $0.40/M short context or $0.80/M long context, and cache writes are $5/M or $10/M respectively.
The same page lists GPT-5.6 Cyber at $12.50/M input and $75/M output for short context. OpenAI says GPT-5.6 Sol promotional pricing is available at least through November 21, 2026. These are API rates; a ChatGPT plan or Codex credit is a different purchase.
For interactive work across models, coding, and creative functions, GlobalGPT gives you a subscription workspace around the task. The relevant question is whether you need a metered production call, a developer workflow, or a lower-cost place to compare and complete work before you commit API budget.
- GPT-5.6 pricing at a glance
- GPT-5.6 Sol and Cyber API rates
- Worked GPT-5.6 token estimates
- Cached input and long context
- ChatGPT plans and Codex credits are different from API pricing
- Choosing an API, CLI, or multi-model workspace
- ChatGPT plan access is a separate budget
- Choose the model route around the task
- A repeatable token-usage test
- When an upgrade is worth the extra API spend
- From API call to a complete developer workflow
- FAQ
GPT-5.6 pricing at a glance
| Model / mode | Short input | Short output | Long input | Long output |
|---|---|---|---|---|
| GPT-5.6 Sol | $4.00/M | $20.00/M | $8.00/M | $30.00/M |
| GPT-5.6 Cyber | $12.50/M | $75.00/M | — | — |
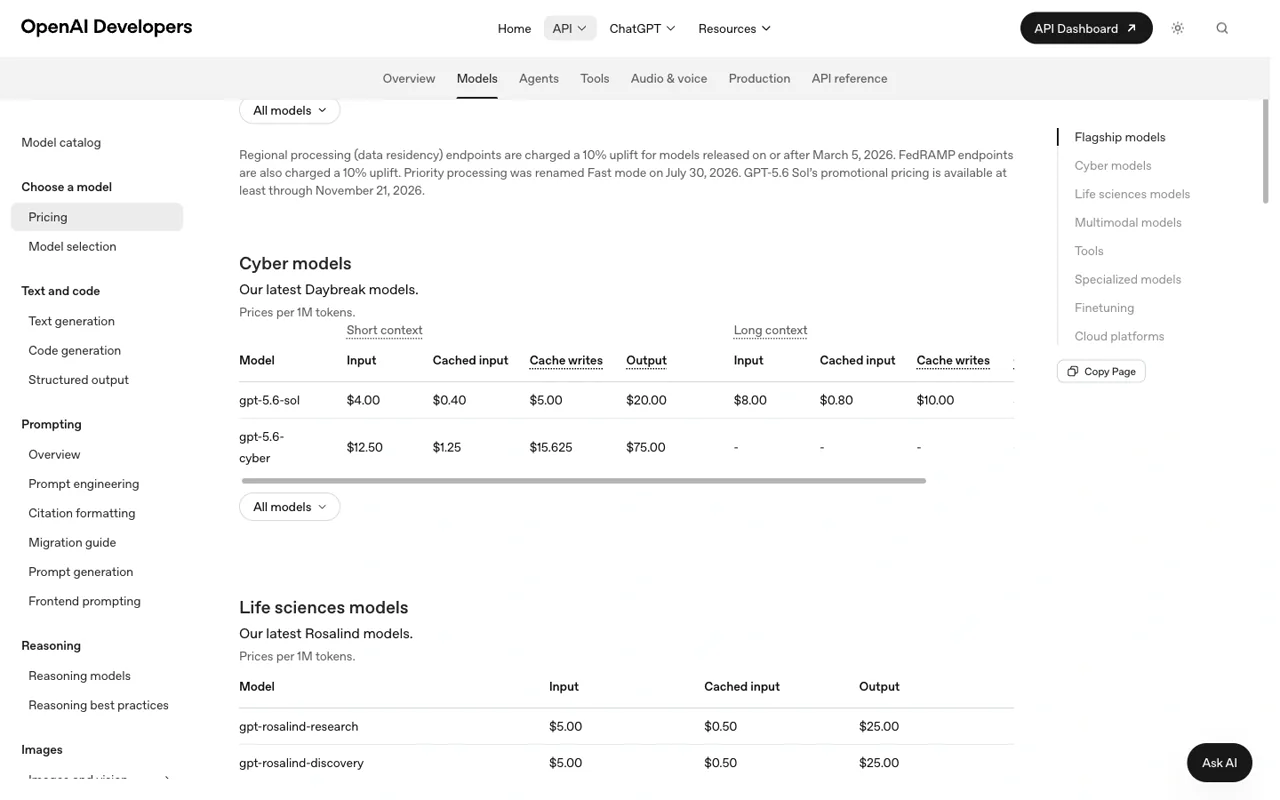
Read the rate card by billing unit: input, cached input, cache writes, and output are separate rows, while long-context requests use a different tier.
Cached input and cache writes have their own rates. OpenAI’s API page also separates Standard, Batch, and Flex columns; choose a mode that your application can actually use before applying a discount to a forecast.
GPT-5.6 Sol and Cyber API rates
| Rate per 1M tokens | GPT-5.6 Sol short | GPT-5.6 Sol long | GPT-5.6 Cyber short |
|---|---|---|---|
| Input | $4.00 | $8.00 | $12.50 |
| Cached input | $0.40 | $0.80 | $1.25 |
| Cache writes | $5.00 | $10.00 | $15.625 |
| Output | $20.00 | $30.00 | $75.00 |
GPT-5.6 Cyber is positioned as a Cyber model rather than a general replacement for Sol. Use it when the task specifically benefits from that route; do not compare the output price alone and call it a universal upgrade.
Worked GPT-5.6 token estimates
Use tokens ÷ 1,000,000 × the applicable rate. These examples use short-context GPT-5.6 Sol and exclude taxes, tool charges, Batch/Flex differences, and plan fees.
| Scenario | Input | Output | Estimate |
|---|---|---|---|
| Small edit | 20,000 × $4/M = $0.08 | 3,000 × $20/M = $0.06 | $0.14 |
| Code review | 250,000 × $8/M = $2.00 (long) | 20,000 × $30/M = $0.60 | $2.60 |
| Large short-context batch | 1M × $4/M = $4.00 | 100k × $20/M = $2.00 | $6.00 |
estimated API cost = input tokens / 1,000,000 × input rate + cached input / 1,000,000 × cached rate + output tokens / 1,000,000 × output rate + tool charges
Cached input and long context
Cached input helps when a repeated prefix—such as a system brief or repository context—qualifies for caching. It does not make every repeated prompt cheap. Use billing usage data to confirm cache hits and add cache-write or storage costs where the provider lists them.
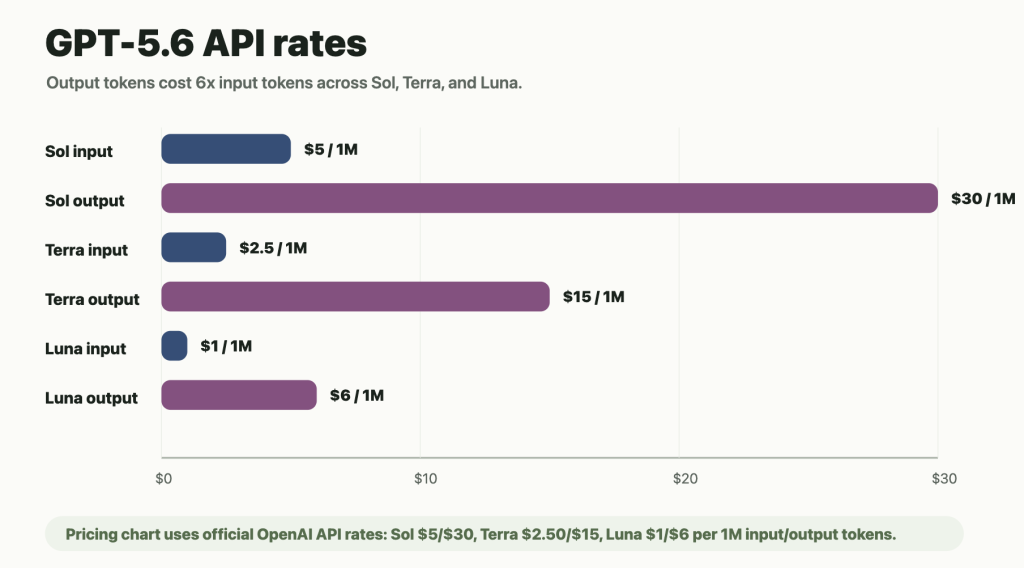
Long context also changes the rate tier. If the request crosses the provider’s long-context boundary, use the long-context input and output prices for that request rather than applying the short rate to the whole bill.
ChatGPT plans and Codex credits are different from API pricing
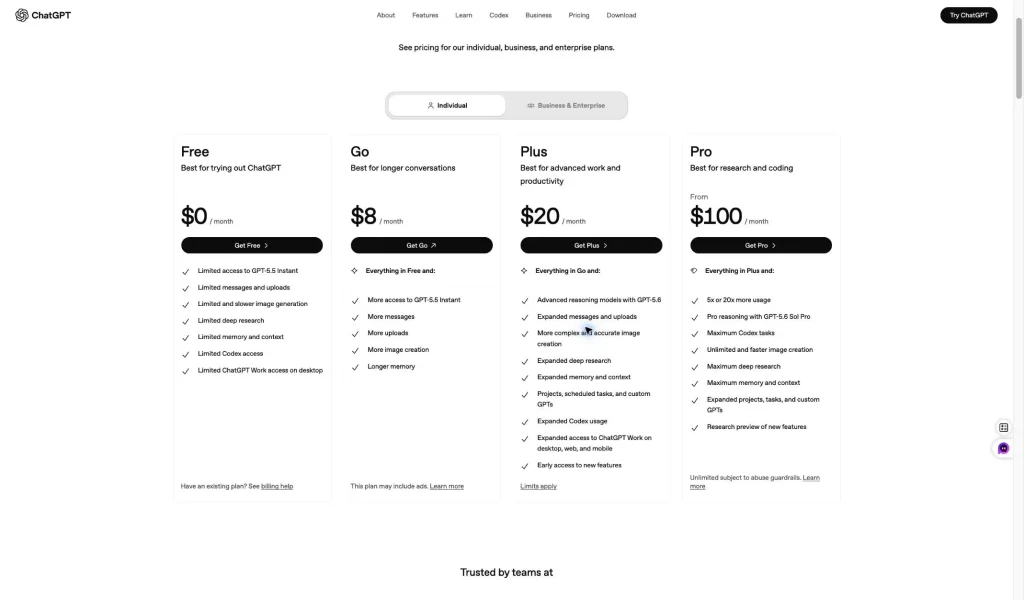
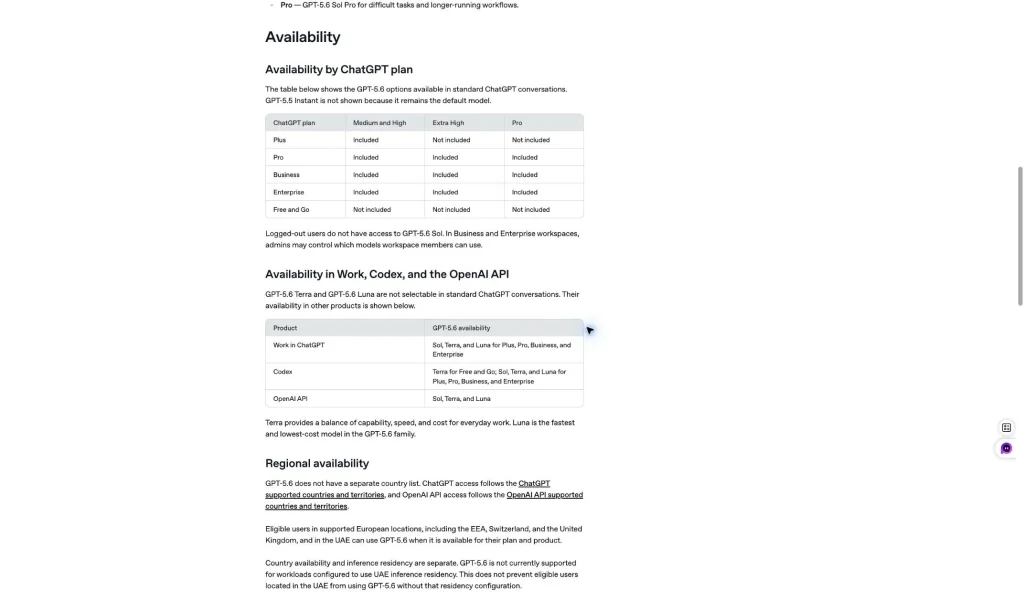
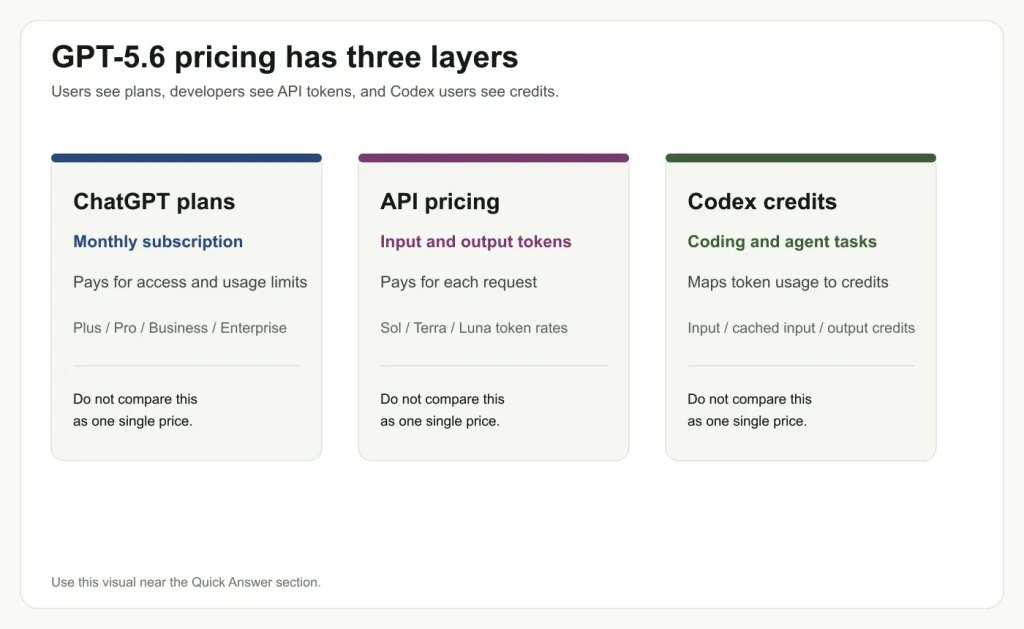
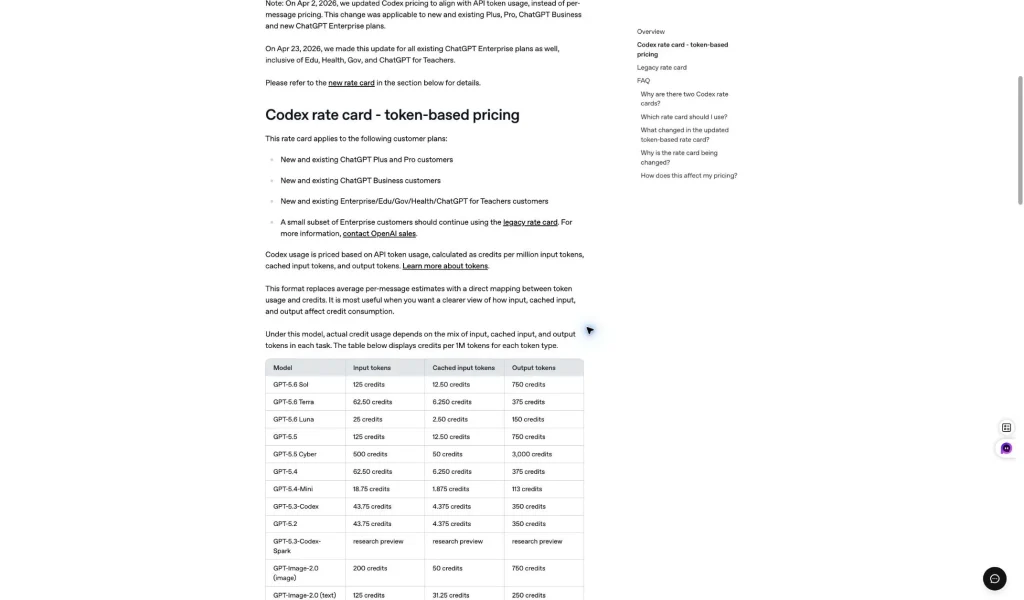
ChatGPT subscriptions bundle app access and features. Codex credits represent usage inside a product surface. API calls are metered against a developer project. Keep those three budgets separate when you compare “GPT-5.6 pricing.”
Choosing an API, CLI, or multi-model workspace

Use the API for programmable production traffic and token-level accounting. Use CLI when the model needs to sit next to a terminal and repository. Use MCP when the workflow depends on approved tools. Use a Yukie agent when the task spans planning, tool use, and handoffs.
GlobalGPT fits the interactive comparison and delivery layer: try different models, continue into coding or other AI functions, and keep the subscription decision separate from OpenAI’s API bill. Its lower overall workflow cost is a value proposition, not a claim that it changes OpenAI’s rates.
ChatGPT plan access is a separate budget
A ChatGPT subscription pays for access to a product surface. The API charges a developer project by token, and Codex credits represent usage inside a product workflow. These ledgers can be related to the same model family while still being different purchases.
| Route | What you pay for | Best question to ask |
|---|---|---|
| ChatGPT plan | Interactive app access and plan features | Does the plan expose the model and tools I need? |
| OpenAI API | Input, cached input, cache writes, output, and tool charges | What will this workload cost at its real token volume? |
| Codex credits | Usage inside the Codex product surface | How much repository or coding work does the credit budget cover? |
| GlobalGPT workspace | A broader subscription workflow across models and tools | Can I complete the task without paying for several separate products? |
Do not use a ChatGPT plan price as an API forecast, and do not use an API rate to describe subscription access. The clean comparison starts by naming the route that will actually deliver your work.
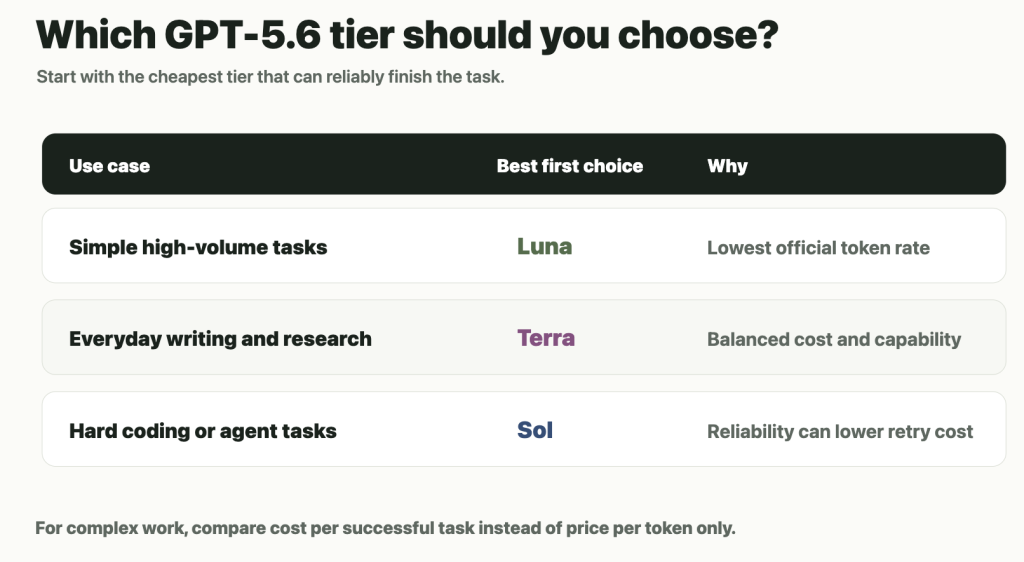
Choose the model route around the task
The cheapest row is not automatically the cheapest completed task. A short edit may be inexpensive on a general model, while a long repository context can make the context tier and output length matter more. For a production call, record input tokens, cached input, output tokens, and any tool calls separately.
| Work pattern | Budget signal | Good operating habit |
|---|---|---|
| Short text transformation | Output often stays small | Set a clear output format and stop condition. |
| Long code or document review | Long-context tier may apply | Measure the prompt size before sending the full repository. |
| Repeated system or repository context | Cached input can matter | Confirm actual cache hits in usage data. |
| Autonomous tool workflow | Tool calls add usage | Log model, tool, and output cost together. |
Use the current model picker and rate card for the exact model names and access conditions. If a model label changes, the budgeting method remains: match the task to the route, then multiply the real units.
A repeatable token-usage test
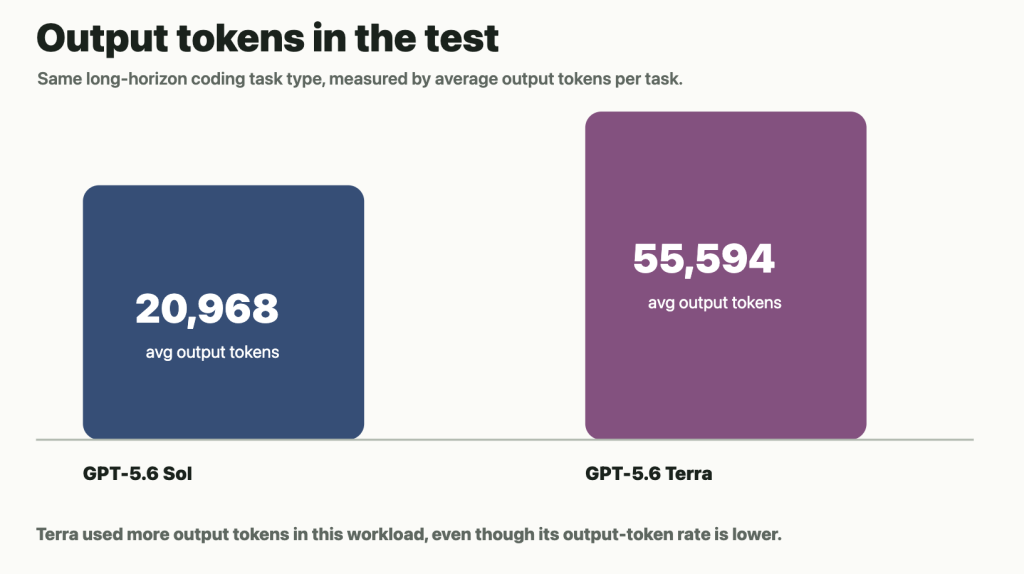
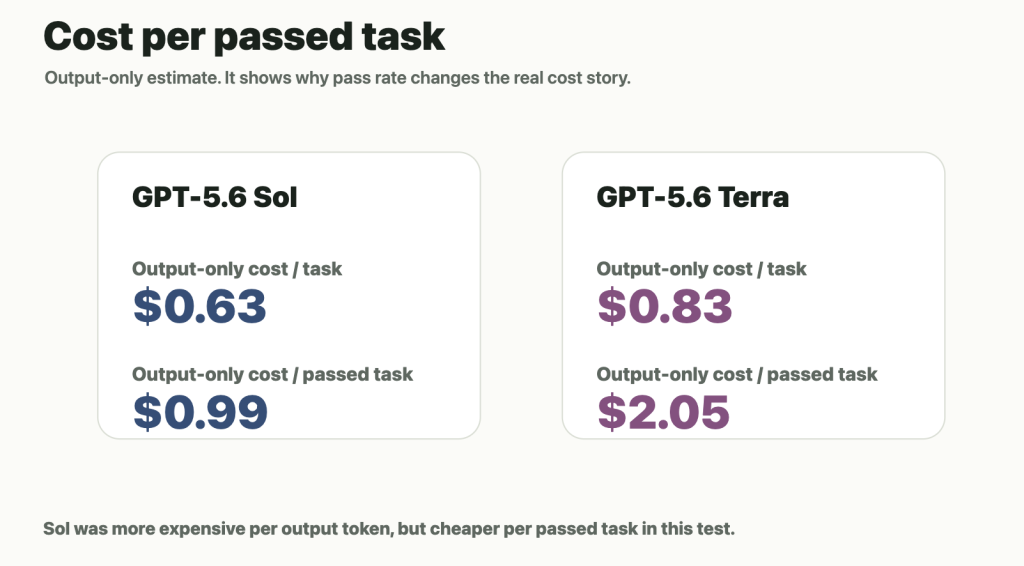
To estimate a real task, use the same prompt, input, and expected output across two runs. Record the input tokens, output tokens, cache status, and whether a tool call was made. Then compare the cost of a successful result, rather than comparing a headline price in isolation.
- Use a small, representative code or writing task.
- Keep the output format fixed so the comparison is fair.
- Record the first result and the final result after any retry.
- Separate provider errors, rate limits, and model quality from the price calculation.
- Keep a dated note because promotional pricing and model availability can change.
This turns “which model is cheaper?” into a useful operating question: which route completes the task with the least predictable spend and rework?
When an upgrade is worth the extra API spend
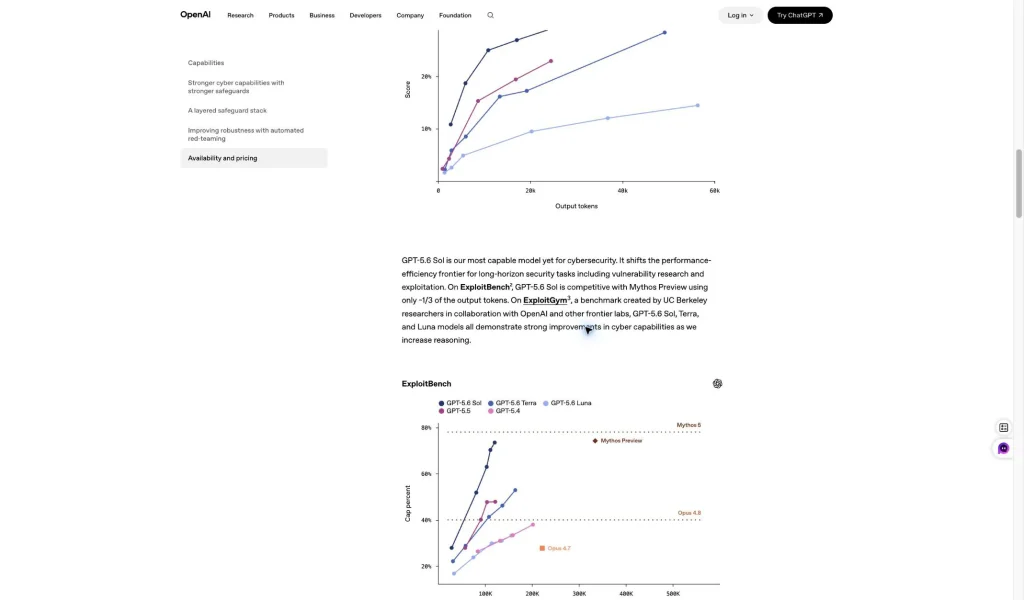
A newer model is worth its higher rate when it reduces a real failure mode: repeated correction, missed tool calls, fragile code, or a long prompt that the cheaper route cannot handle reliably. If the output is already correct and short, a more expensive model can be wasteful.
For a team, compare three numbers over the same task set: successful completions, average output tokens, and human correction time. The model with the lowest token price is not always the lowest total project cost.
From API call to a complete developer workflow
Use the GlobalGPT API route for programmable calls, CLI when the model needs to sit next to a terminal and repository, and MCP when the workflow depends on approved tools. A Yukie agent can coordinate planning, tool use, and handoffs. For interactive work, GlobalGPT GPT-5.6 workspace access lets you test the task before committing to a metered production path.
The practical advantage is the sequence: clarify the task, compare a suitable model, run the smallest useful test, then move the working prompt into API, CLI, or MCP. That keeps experimentation and production spend separate.
FAQ
What is GPT-5.6 Sol API pricing?
OpenAI lists $4/M input and $20/M output for short context, and $8/M input and $30/M output for long context. Cached input and cache writes use separate rates.
Is GPT-5.6 Cyber more expensive?
Its published short-context rates are $12.50/M input and $75/M output, so it is a different budget decision and should be chosen for a task that needs its specific route.
Does ChatGPT Plus include API credits?
Do not assume so. ChatGPT subscriptions and API projects are separate billing surfaces.
What are Codex credits?
They are product usage credits whose practical consumption depends on model and token usage. Keep them separate from an API project forecast.
What is the cheapest way to use GPT-5.6?
For interactive multi-model work, compare a current workspace plan. For production software, compare token estimates, cache hits, context tier, and the completion rate of the model you choose.
Start with the billing unit: token rates answer the API question; plan access, credits, and workflow value answer the product question.










