

Claude Sonnet 4.5 is a dated model with a clear identity: Anthropic introduced it on September 29, 2025 for coding, agentic workflows, computer use, and long multi-step tasks. If an existing application depends on it, the decision comes down to three things: its coding strengths, the cost of running it, and the work needed to move to another model.
For developers who move between research, writing, coding help, and model-specific tasks, GlobalGPT provides one connected workspace. One subscription brings a broad model catalog and multiple AI functions together, making it a budget-friendly way to cover a development workflow. GlobalGPT’s CLI connects that workflow with your terminal and existing development tools.
What Claude Sonnet 4.5 Is
Sonnet 4.5 was Anthropic’s practical middle tier at launch: stronger than a lightweight model for complex software work, while priced below its Opus line. Anthropic’s launch announcement highlighted coding, computer use, agent building, reasoning, and math.
Those statements describe the September 2025 release. They do not make Sonnet 4.5 the newest Claude option in 2026, and a vendor benchmark is not a guarantee for every codebase. The decision today is whether you need this model’s known behavior or can move to a newer default.
Current API Status and Retirement Watch
claude-sonnet-4-5Anthropic’s model-deprecation table showed the dated snapshot claude-sonnet-4-5-20250929 as Active when checked on September 30, 2026. The same row says Not sooner than September 29, 2026. That wording is a lower bound, not a scheduled shutdown date. Check the live lifecycle table before a production migration.
What the Launch Evidence Shows
The useful evidence is specific and dated. It shows why Sonnet 4.5 became a coding reference point, while the test conditions explain how far each number can travel.
Computer-use results at launch
OSWorld success rate, on a 0–100% scale. Higher is better.
Source: Anthropic launch announcement, September 29, 2025; checked September 28, 2026. A 19.2 percentage-point gain in the reported evaluation; this is not a general desktop-task success guarantee.
| Evidence | Launch-era result | How to read it |
|---|---|---|
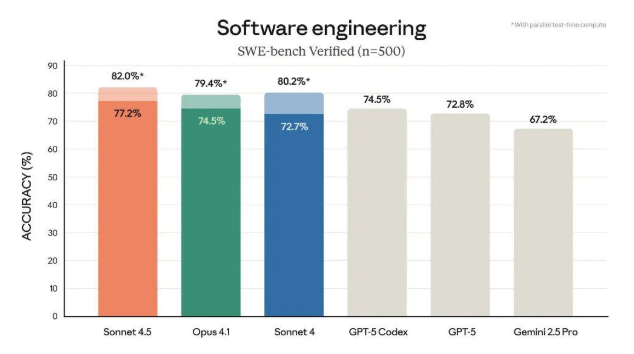
| SWE-bench Verified | 77.2% primary result | 500 problems, averaged over 10 trials, no extra test-time compute, 200K thinking budget |
| SWE-bench high-compute variant | 82.0% | Parallel attempts, visible-regression filtering, and internal candidate selection |
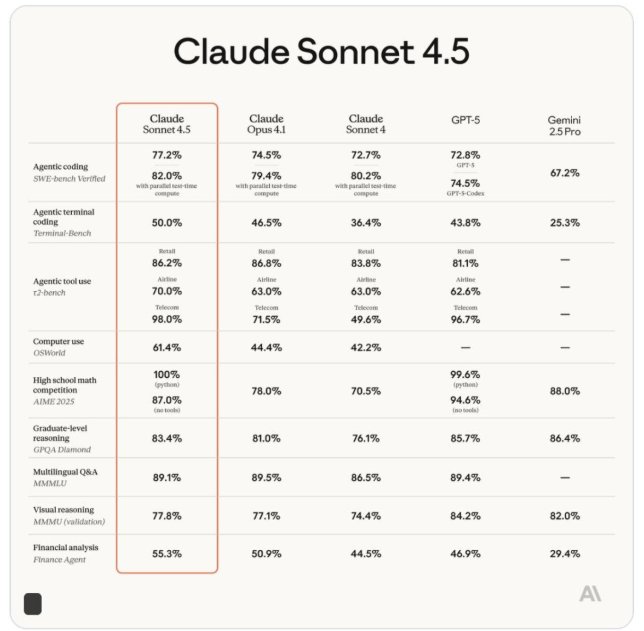
| OSWorld | 61.4% vs Sonnet 4 at 42.2% | Anthropic’s reported computer-use benchmark comparison |
Anthropic’s primary 77.2% SWE-bench Verified result covered all 500 problems, averaged 10 trials, used no extra test-time compute, and used a 200K thinking budget. The 82.0% figure came from a separate high-compute setup with parallel attempts, visible-regression filtering, and internal candidate selection. Those are different evaluation conditions.
Anthropic also reported 61.4% on OSWorld, compared with 42.2% for Sonnet 4 four months earlier. OSWorld tests computer-use tasks, so the result speaks to interacting with software environments; it does not predict success on every desktop workflow.
Anthropic said it had observed Sonnet 4.5 maintaining focus for more than 30 hours on complex, multi-step tasks. That is a vendor observation, not a promise that every user task will run for 30 hours or that uninterrupted autonomy is always desirable.
Coding and Agent Upgrades at Launch
The release bundled model and tooling changes. Anthropic highlighted checkpoints for saving and rolling back progress, a refreshed terminal, a native VS Code extension, context editing and memory tools, code execution and file creation, and the Claude Agent SDK.
- Checkpoints help a long coding session recover from a bad turn without losing the whole run.
- The Claude Agent SDK exposes the foundation Anthropic used for Claude Code so teams can build task-specific agents.
- Parallel tool use and longer-horizon tasks were part of the launch story; current commands and menus should be checked in the live docs.
- Claude Code, the API, and the web app are separate access paths. Choose the one that matches your permissions, billing, and review loop.
For implementation details, use Anthropic’s live developer documentation rather than copying a 2025 launch instruction. The model ID is a durable starting point; tools and client behavior should be checked against current API and Claude Code docs.
The launch announcement also quotes Cursor CEO Michael Truell describing stronger coding and longer-horizon task performance. That customer assessment helps explain the release’s appeal to developers, while the benchmark methods above provide the more precise basis for comparison.
API Pricing and Access
The Anthropic pricing table lists Sonnet 4.5 at $3 per million input tokens and $15 per million output tokens. Its pricing table also lists lower Batch rates and prompt-cache write/read rates for workloads that reuse long context; the pricing page was checked on September 28, 2026.
| API route | Input | Output | When it fits |
|---|---|---|---|
| Standard API | $3 / MTok | $15 / MTok | Interactive requests and normal production calls |
| Batch API | $1.50 / MTok | $7.50 / MTok | Asynchronous bulk work; Anthropic documents a 50% token discount |
| Prompt cache | $3.75 / MTok (5-minute write) or $6 / MTok (1-hour write) | — | Repeated long prompts; cache reads are $0.30 / MTok |
The same workload: Standard vs Batch
100,000 uncached input tokens + 10,000 output tokens. USD; zero-baseline scale up to $0.45.
Calculation from Anthropic’s rate card, checked September 28, 2026. Batch cuts this token charge by 50% when asynchronous processing fits. Excludes caching, regional modifiers, and other charges; this is an example, not a measured bill.
A request with 100,000 uncached input tokens and 10,000 output tokens would be about $0.45 at standard rates before cache, data-residency, or other modifiers. The same token counts in Batch would be about $0.225. These are arithmetic examples, not a billing quote.
For the consumer app, Claude Code, GlobalGPT, and the API, access and billing can differ. If you want Sonnet 4.5 inside a multi-model workspace, open the current GlobalGPT Sonnet 4.5 page. For direct production API calls, use Anthropic’s console and API documentation.
How to Use Sonnet 4.5 Today
There are three sensible routes, and each solves a different job:
- GlobalGPT workspace: open Sonnet 4.5 with other models and functions when you want connected chat, research, writing, or coding-help work without managing several separate model surfaces.
- Anthropic API: use
claude-sonnet-4-5in the Messages API when you own the application, need direct billing, or want to pin a snapshot. - Claude Code or an editor integration: use the tool path when repository work, shell access, and review permissions matter as much as the model.
Safety Evidence
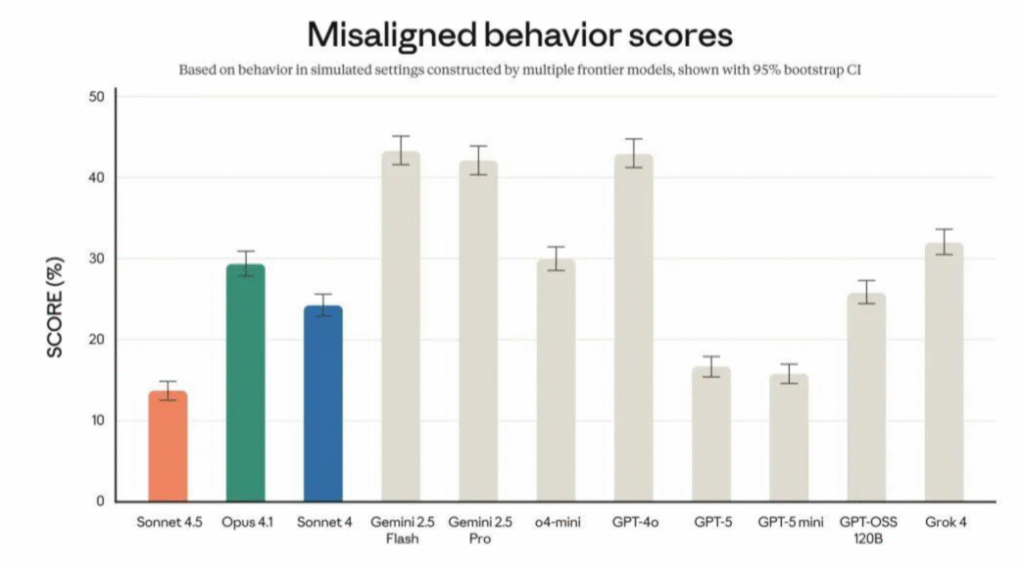
Anthropic’s launch announcement described Sonnet 4.5 as its most aligned frontier model at the time and reported reductions in behaviors such as sycophancy, deception, power-seeking, and encouragement of delusional thinking. It also described progress against prompt injection for agentic and computer-use systems.
The accompanying behavioral-auditor chart is narrower than a blanket safety guarantee. It is labelled as a simulated setting and uses 95% bootstrap confidence intervals; lower scores are better. The result is evidence about the tested setup, not proof that every deployment is safe or that prompt injection disappears.
Read the Claude Sonnet 4.5 system card for evaluation details and limitations before using the model in a high-impact workflow.
Current Alternatives and Compatibility Guidance
Anthropic’s current model overview lists newer families alongside the 4.5 snapshot. The choice is task-based:
Keep Sonnet 4.5
Choose it when your integration, prompt set, or regression history depends on the 2025 behavior and the lifecycle row still supports your deployment.
Move to a newer Sonnet
Choose the current Sonnet family when you want a supported default and can afford a compatibility pass before changing the model ID.
Use a different family
Choose an Opus-style model for deeper reasoning or a Haiku-style model for speed and lighter workloads; validate with the task you actually run.
For a Claude-specific comparison path, see GlobalGPT’s Claude Sonnet 4.5 alternatives guide. For API and plan context, the current Claude pricing guide explains how subscriptions, API charges, and usage limits fit together.
Is Sonnet 4.5 Still Worth Using?
Yes, when the job is compatibility-sensitive coding, a known Claude Code workflow, or a benchmark and regression reference. The launch evidence is still useful, the API ID is clear, and the lifecycle page showed the snapshot as Active at the latest recorded check.
It is less attractive as a new universal default if you have no compatibility constraint. A newer supported model may offer better current tooling or reasoning, and the September 29, 2026 lower-bound retirement line makes a migration plan sensible. Compare your own prompts and tool calls, then choose the model that passes the workflow you need.
FAQ
What is Claude Sonnet 4.5?
It is Anthropic’s September 2025 coding and agent model. Its API model ID is claude-sonnet-4-5, with the dated snapshot claude-sonnet-4-5-20250929.
Is Claude Sonnet 4.5 still active?
Anthropic’s lifecycle table showed the dated snapshot as Active when checked on September 30, 2026. The row also says “Not sooner than September 29, 2026,” which is a lower bound rather than a fixed retirement date. Recheck the live table before a long-lived deployment.
How much does the Sonnet 4.5 API cost?
Standard pricing is $3 per million input tokens and $15 per million output tokens. Batch pricing is $1.50 and $7.50 respectively. Cache writes and reads use separate rates.
Is Claude Sonnet 4.5 free?
Direct API usage is paid per token. Access through Claude or GlobalGPT follows the service’s plan and usage limits; check the selected service before starting a large workload.
Was the 30-hour claim a user guarantee?
No. Anthropic wrote that it had observed more than 30 hours on complex, multi-step tasks. That is a dated vendor observation, not a promise for every user or workload.
Is Sonnet 4.5 better than ChatGPT 5?
There is no single winner without a task, prompt set, tools, and scoring rule. Compare the models on your coding, reasoning, and tool-use workflow instead of treating a search snippet as a benchmark.
To work with Sonnet 4.5 alongside your other AI tools, open the current GlobalGPT model page. Start with a real coding question or debugging task, then carry the same project context into research and documentation.










