4 Best Bright Data Alternatives for Web Scraping and Web Search in 2026
 Hiba Fathima

TL;DR: best Bright Data alternatives in 2026
| Alternative | Best for | Quick differentiator |
|---|---|---|
| Firecrawl | AI agents/apps, unified scrape + search | Single API for scrape, search, crawl, and browse, plus licensed and official data via Firecrawl Alexandria. LLM-ready markdown output |
| ScrapingBee | Simple API + Google Search | Clean REST integration with built-in Google Search, starts at $49/month |
| Apify | Pre-built site-specific scrapers | 26,000+ ready-to-run Actors for specific sites, no code required |
| Scrape.do | Affordable API-first scraping | Pay only for successful requests, starts at $29/month |
Bright Data's proxy network spans 400M+ IPs across 195 countries. Its SERP API covers Google, Bing, Yandex, and Baidu. The enterprise SLA is genuine. So are the $499/month minimums, billed separately per product, and the multi-zone setup required before a first request goes out. For teams with a dedicated data engineering budget and petabyte-scale requirements, it's the right tool. For everyone else, there are better-value options.
This article covers two distinct use cases Bright Data serves: web scraping (extracting data from URLs) and search/SERP (querying search engines programmatically). Bright Data is strongest as proxy-first infrastructure; Firecrawl is built for the full AI-agent web data loop: search, scrape, clean, and use. Not every alternative covers both, and that matters for how you evaluate them.
What is Bright Data?
Bright Data is one of the largest commercial web data platforms on the market. It started in 2014 as Luminati Networks, a proxy provider. By 2021 it had rebranded and grown into a full data infrastructure company. Today it serves enterprises like Deloitte, McDonald's, Nokia, Pfizer, and Oxford University.
It covers three main product layers:
- Proxy infrastructure: 400M+ monthly residential IPs across 195 countries, plus datacenter and ISP networks
- Web Access APIs: Web Scraper API, Scraping Browser (Puppeteer and Playwright compatible), and Web Unlocker for complex sites
- SERP API: real-time search results from Google, Bing, Yandex, and Baidu with city-level geo-targeting
Each product has separate pricing and billing. SERP API starts at $499/month for 380K results. Web Scraper API starts at $499/month for 384K records.
What are the best Bright Data datasets alternatives for AI agents?
The best Bright Data datasets alternative for AI agents is Firecrawl Alexandria, a library of 400+ data providers, including official APIs, public registries, licensed publishers, and Firecrawl indexes, that an agent calls per record or per query through the Firecrawl API, with batch capabilities where a provider offers them, such as Apollo enriching up to ten companies in one call.
Bright Data's Dataset Marketplace sells pre-collected datasets, bought once or refreshed on a schedule. That shape suits a team loading a warehouse. An AI agent usually needs one company's latest filings, one economic series, or one podcast transcript at the moment a user asks, and a snapshot from last quarter may not hold the latest record.
| Firecrawl Alexandria | Bright Data Dataset Marketplace | |
|---|---|---|
| What you buy | One tool call per record or query | Pre-collected datasets |
| Freshness | Official APIs are called at request time; Firecrawl indexes return their indexed copy | One-time or scheduled refresh, varying by dataset |
| How an AI agent reaches it | Ranked tools from a Firecrawl search with alexandria in its sources, via API, MCP, or CLI | Dataset delivery or Bright Data's API, depending on the plan |
| Pricing shape | Firecrawl credits at each tool's listed price, discovery free | Set by dataset, volume, and plan |
| Sources | 400+ official APIs, registries, licensed publishers, and Firecrawl indexes | Records collected from 120+ domains |
Counts as listed on each vendor's site on October 21, 2026.
Firecrawl Alexandria listed 300+ providers and 1,800+ capabilities on October 21, 2026, from SEC EDGAR filings and Companies House records to FRED economic series and Particle podcast transcripts. An agent finds the right tool in the same /search call it already makes, then runs it for one record:
from firecrawl import Firecrawl

firecrawl = Firecrawl(api_key="fc-YOUR_API_KEY")

# Matching Firecrawl Alexandria tools come back next to web results.
# Tool discovery is free; the web results bill as a normal search.
results = firecrawl.search(
    "SEC filings for a public company by ticker",
    sources=["web", "alexandria"],
    limit=3,
)

# Run the tool you picked from results, here SEC EDGAR's company profile,
# billed at the capability's listed price in Firecrawl credits
company = firecrawl.scrape(
    alexandria={
        "provider": "sec-gov",
        "capability": "filings/company",
        "options": {"ticker": "AAPL"},
    },
)
result = company.alexandria[0]
if result.error:
    print(result.error)
else:
    print(result.data)
Firecrawl Alexandria needs a Firecrawl account. Keyless Firecrawl covers search, scrape, and parse without an API key: add https://mcp.firecrawl.dev/v2/mcp as a remote MCP server in Claude Code, Cursor, or Codex, within a rate limit (try keyless). For company records specifically, our company enrichment API benchmark covers the providers it can call, and our RapidAPI alternatives for AI agents post applies the same comparison to API marketplaces.
Top 4 Bright Data alternatives in 2026
| Tool | Best for | Starting price | Scraping | Search/SERP |
|---|---|---|---|---|
| Firecrawl | AI apps, unified scrape + search | Free (1,000 credits/month) | Yes | Yes, plus Firecrawl Alexandria providers |
| ScrapingBee | Simple API + Google Search | $49/month | Yes | Google only |
| Apify | Pre-built site-specific scrapers | $29/month | Yes | Via marketplace |
| Scrape.do | Affordable API-first scraping | $29/month | Yes | Google only |
1. Firecrawl: unified scrape, search, and browse API for AI teams
Firecrawl is the web data API to search, scrape, and interact with the web at scale, built for developers and AI teams. It consolidates scraping, search, crawling, and browser interaction into one API behind a single key. It's open source (180K+ GitHub stars), used in production by teams at Shopify, Apple, Canva, and Replit. It's also enterprise-ready: Enterprise plans add zero data retention, SAML SSO with SCIM, and a signed DPA.
With Bright Data you configure zones, pick a product, set up separate billing, then make your first request. With Firecrawl you can start with no API key, then add one when you scale.
For scraping:
/scrape: single page to markdown + structured JSON, 1 credit per page/crawl: multi-page site crawl with depth and filter controls, including list crawling across paginated pages/interact: browser automation actions (click, fill, navigate), similar to Bright Data's Scraping Browser but in the same API/agent: autonomous extraction from complex sites via natural language
For search:
/search: real-time web search results with full page content in one call- Returns LLM-ready markdown, no separate scrape step required
CLI and agent onboarding:
- Install the Firecrawl CLI:
npm install -g firecrawl-cli - AI coding agents (Claude Code, OpenCode) can auto-discover and configure it:
npx -y firecrawl-cli@latest init --all - Run scrapes, searches, and agent tasks from the terminal:
firecrawl search "query"orfirecrawl agent "Find top 5 AI startups" --wait
| Feature | Firecrawl | Bright Data |
|---|---|---|
| Output format | LLM-ready markdown + JSON by default | JSON, HTML, or Markdown (product-dependent) |
| Search + scrape | Single unified API | SERP API + Web Scraper = separate products |
| Licensed and official data | Firecrawl Alexandria providers in the search response, priced per tool | Dataset Marketplace, separate product |
| Browser interaction | Included via /interact | Separate Scraping Browser product |
| Open source | Yes (AGPL-3.0, self-hostable) | No |
| Setup time | No API key to start, minutes | Zones, product selection, separate billing |
| SOC 2 Type II | Yes (renewal audit in progress) | Yes |
- Free: 1,000 credits every month, no credit card required
- Hobby: $19/month billed monthly, or $16/month billed annually, 5,000 credits/month
- Standard: $99/month billed monthly, or $83/month billed annually, 100,000 credits/month
- Growth: $399/month billed monthly, or $333/month billed annually, 500,000 credits/month
- Scale: $749/month billed monthly, or $599/month billed annually, 1,000,000 credits/month
Start for free on Firecrawl. No credit card required.
Choose Firecrawl when you're building AI apps, RAG pipelines, or LLM workflows and want scraping and search behind a single key without managing separate products or billing.
For a direct feature-by-feature comparison, see Firecrawl vs. Bright Data.
2. ScrapingBee: developer API with built-in Google Search
ScrapingBee is a REST API that handles proxy management and JavaScript rendering. The Google Search API is bundled in at every tier, which is the reason most teams pick it over rolling their own SERP solution. If you're evaluating ScrapingBee alternatives beyond Bright Data, our dedicated guide covers the full landscape.
Here's a quick breakdown of what ScrapingBee offers as a Bright Data alternative:
For scraping:
- Distributed proxy infrastructure
- JavaScript rendering via headless Chrome
- Screenshots, CSS selector extraction, and custom JS execution
For search:
- Google Search API returns organic results, ads, and related searches as structured data
- 15 credits per standard search request; 10 credits for light requests
| Feature | ScrapingBee | Bright Data |
|---|---|---|
| Search engines | Google only | Google, Bing, Yandex, Baidu, others |
| Output format | HTML / JSON | JSON, HTML, or Markdown |
| Proxy pool | Managed (size not published) | 400M+ residential IPs |
| Free tier | 1,000 API calls, no CC | Credit-matched trial up to $500 |
| Geo-targeting | Country level | City-level, 195 countries |
- Free: 1,000 API calls, no credit card
- Freelance: $49/month, 250,000 credits, 10 concurrent
- Startup: $99/month, 1,000,000 credits, 50 concurrent
- Business: $249/month, 3,000,000 credits, 100 concurrent
- Business+: $599/month, 8,000,000 credits, 200 concurrent
One thing to watch. Credit costs stack up quickly on JavaScript-heavy targets. Premium proxies with JS rendering cost 75 credits per request, versus 1 for a basic call. That's a 75x multiplier. A Capterra reviewer (Rob B., Jan 2024) put it plainly: "the jump in cost to utilise premium proxies and javascript rendering is quite steep (25x)."
A Proxyway December 2025 benchmark found success rates dropped from 84.47% at 2 requests/second to 72.98% at 10 requests/second under load. ScrapingBee was also acquired by Oxylabs in June 2025.
Choose ScrapingBee when you need a simple REST scraping API and Google Search is your only SERP source. It's a significant step down in cost from Bright Data's $499/month SERP minimum.
3. Apify: actor marketplace for pre-built site scrapers
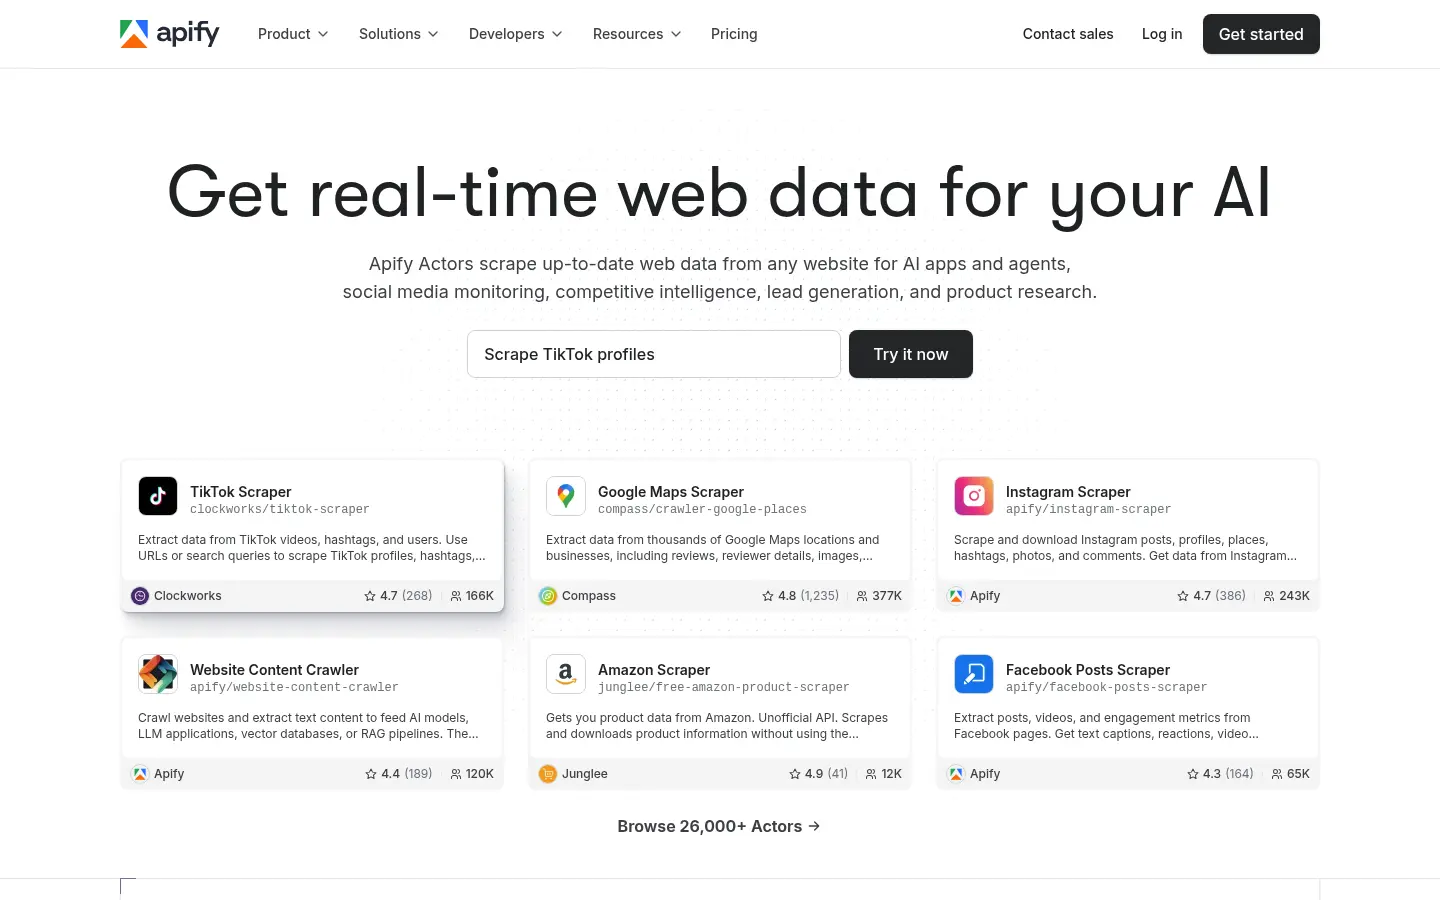
Apify is a cloud platform built around a marketplace of 26,000+ pre-built scrapers called Actors. Each Actor targets a specific site or use case: Amazon, LinkedIn, Instagram, Google Maps, TikTok, and hundreds more. If your target site has an Actor, you configure it in the UI and run it — no scraper to build or maintain.
The platform also ships Crawlee, an open-source JS/Python SDK for building custom scrapers, with 23,000+ GitHub stars. Customers include T-Mobile, Microsoft, Accenture, the European Commission, and Groupon.
For scraping:
- 26,000+ Actors for specific sites and use cases
- Full API access on all paid plans
- Crawlee SDK for building custom scrapers
- Cloud infrastructure for scheduling and monitoring
For search:
- No dedicated SERP API product
- Google Search results available via a marketplace Actor (community-maintained)
| Feature | Apify | Bright Data |
|---|---|---|
| Pre-built scrapers | 26,000+ Actors | Industry-specific scrapers |
| SERP API | Via marketplace Actor | Dedicated multi-engine SERP API |
| Proxy infrastructure | Managed (built-in with actors) | 400M+ IPs, owned network |
| Open source | Crawlee SDK | Proxy Manager tooling |
| Starting price | $29/month | ~$500/month typical minimum |
- Free: $5 platform credit included
- Starter: $29/month (compute + storage + proxy from one credit pool)
- Scale: $199/month
- Business: $999/month
Note: Apify's credit model bundles compute, actor usage, and proxy bandwidth together. Test on the free tier before committing to predict your costs accurately. Capterra reviewer Dragos M. (April 2026) captured the core issue: "Estimating the cost of a new Actor run before executing it is largely guesswork." The plan structure also jumps directly from $199/month (Scale) to $999/month (Business) with no middle option.
For a full comparison, see Firecrawl vs. Apify.
Choose Apify when you need to scrape a specific site without building from scratch, and an Actor already exists for it. Or when you want full code control via the Crawlee SDK.
4. Scrape.do: affordable API scraping at 99.98% success
Scrape.do charges only for successful requests. Failed calls cost nothing. It runs 110M proxies, processes 10B+ requests per month, and holds a Capterra Best Customer Support badge. At $29/month it's the cheapest paid option here by a significant margin.
The product is deliberately narrow. One REST endpoint, reliable HTTP scraping, no infrastructure to manage.
For scraping:
- Geo-targeting (160+ countries), sticky sessions
- JavaScript rendering and full browser support
- Unlimited bandwidth on all plans
- Only charges for successful API calls, failed requests are free
For search:
- Google Search API returns SERP results, AI Overviews, and AI Mode responses as structured JSON
- Google Trends API for search interest and trending topics
- Google only, no multi-engine support
| Feature | Scrape.do | Bright Data |
|---|---|---|
| Starting price | $29/month | ~$500/month typical minimum |
| Proxy pool | 110M+ IPs | 400M+ residential IPs |
| Google Search API | Yes (structured JSON) | Yes (multi-engine) |
| Billing model | Successful requests only | Per-GB / per-request |
| Bandwidth | Unlimited on all plans | Metered (proxies billed per GB) |
| Support response time | Under 5 minutes | Under 10 minutes |
- Free: 1,000 credits, all features unlocked, no credit card
- Hobby: $29/month, 250,000 credits, 10 concurrent
- Pro: $99/month, 1,250,000 credits, 50 concurrent
- Business: $249/month, 3,500,000 credits, 100 concurrent
- Advanced: $699/month, 10,000,000 credits, 200 concurrent, custom SLA
One thing to watch. Scrape.do's Proxies and Scraping Browser products are both listed as "Coming Soon" as of April 2026. Credits are allocated monthly and do not roll over to the next billing period. The platform also has no SOC 2 certification listed anywhere on the site. If your team has compliance requirements or needs advanced browser automation, verify current status before committing.
Choose Scrape.do when budget is the primary constraint. The success-only billing model removes the most common source of wasted spend on scraping APIs, and the free tier includes all features.
How to choose
If you're building AI or LLM workflows, Firecrawl removes the most friction: unified API, markdown output by default, free tier to start.
Firecrawl Alexandria adds the licensed and official data sources (filings, financials, economic series, podcast transcripts) that a dataset marketplace would otherwise sell you, returned as tools in the same search call.
The catalogue itself is the argument for choosing Firecrawl here. It includes the Wayback Machine for how a page looked on any past date, Greenhouse job boards for every open role at a company, code repositories, Hugging Face, PyPI, and Stack Exchange for developer questions, Companies House and SEC EDGAR for registries and filings, and nearly 300 other providers, all reachable from the one search call an agent already makes. For AI-native web search for AI agents with richer context, see our comparison of dedicated search APIs.
All four tools offer free tiers or trials. Test on your actual target sites — success rates and cost-per-result vary enough that a quick test beats any pricing page estimate. See Firecrawl pricing if you want to start there.
Here's a quick summary of the free plans offered by the popular Bright Data alternatives:
- Firecrawl: Try the Playground, no signup required, or call the API without a key to try it
- ScrapingBee: 1,000 free API calls, no credit card
- Apify: Free tier with $5 platform credit
- Scrape.do: 1,000 free credits, all features included
Use Firecrawl in your agent
Add Firecrawl to ChatGPT, Claude, Cursor and more in one click.
Frequently Asked Questions
What is the best alternative to Bright Data for web scraping?
It depends on your use case. For AI and LLM pipelines, Firecrawl returns clean markdown by default and covers scraping and search in one API. For pre-built scrapers targeting specific sites, Apify's Actor marketplace is the fastest path. For enterprise-scale proxy infrastructure, Oxylabs is the closest like-for-like. For budget-first teams, Scrape.do at $29/month charges only for successful requests.
Does Bright Data still offer mobile proxies in 2026?
No. As of April 2026, Bright Data no longer offers mobile proxies to new customers. Existing subscribers with active mobile proxy plans can continue using them. Bright Data now recommends residential and ISP proxies as alternatives.
What is cheaper than Bright Data for SERP data?
Several options cost significantly less. Oxylabs charges from $0.80–$1.00/1,000 Google Search results depending on plan tier. ScrapingBee's Google Search API starts at $49/month. Scrape.do's Google Search API starts at $29/month. All three are substantially cheaper than Bright Data's SERP API, which starts at $499/month for 380K results.
Can Firecrawl replace Bright Data's SERP API?
For most use cases, yes. Firecrawl's /search endpoint returns real-time web search results with full page content in one API call, and outputs LLM-ready markdown. If you need multi-engine SERP coverage (Bing, Baidu, Yandex) with advanced geo-targeting and SLA guarantees, Bright Data or Oxylabs are better fits.
Is there a free alternative to Bright Data?
Firecrawl has a free tier (1,000 credits per month, no credit card). Scrape.do offers 1,000 free credits with all features unlocked. ScrapingBee offers 1,000 free API calls. Apify includes $5 platform credit on the free plan.
Is Bright Data worth it for small teams?
Community feedback consistently points to cost as the blocker. Multiple Reddit threads document teams finding 90%+ cost savings after switching. For smaller teams, ScrapingBee ($49/month), Scrape.do ($29/month), or Firecrawl (free tier available) offer better value per dollar unless you need Bright Data's proxy infrastructure scale or enterprise SLA.
How do I migrate from Bright Data to Firecrawl?
Replace Bright Data's zone configuration and product-specific API calls with a single Firecrawl API key. Scraping calls map to /scrape. SERP queries map to /search. Browser interactions map to /interact. Most teams complete the migration in under a day.
Does Firecrawl offer licensed data like Bright Data's dataset marketplace?
Through Firecrawl Alexandria it reaches licensed publishers and official APIs, including Fiscal.ai for company financials, Benzinga for financial news, Particle for podcast transcripts, and SEC EDGAR, FRED, and the World Bank for public records and economic data. The difference in shape is that Firecrawl Alexandria returns these as tools in a search response that an agent calls per record or per query, billed at the tool's listed price, rather than as a bulk dataset download.
How does an agent find a Firecrawl Alexandria provider?
Add alexandria to the sources parameter of a Firecrawl search call. The response carries a tools array next to the web results, and each tool names its provider and capability and describes what it returns. Tool discovery is free, and the web results bill as a normal search. The agent then reads the tool's inputs and price in Firecrawl credits with Find Tools, also free, and runs it through the scrape endpoint with an alexandria block in place of a URL.
Can an AI agent read Bright Data datasets directly?
Bright Data datasets are delivered as JSON, CSV or Parquet snapshots, so an agent usually reads them after you load them into a database or vector store it can query. Firecrawl Alexandria works at request time, so the agent calls a provider tool through the Firecrawl API or MCP server and gets the records back in the same session.
How current is Firecrawl Alexandria data compared with a purchased dataset?
For official APIs such as SEC EDGAR or FRED, Firecrawl Alexandria calls the provider when the agent runs the tool, so a record is as current as that source. Firecrawl's own indexes return their indexed copy. A purchased dataset is as current as its last refresh, and refresh schedules on Bright Data's marketplace vary by dataset and plan.